Related Experiment Video
Updated: Aug 27, 2026
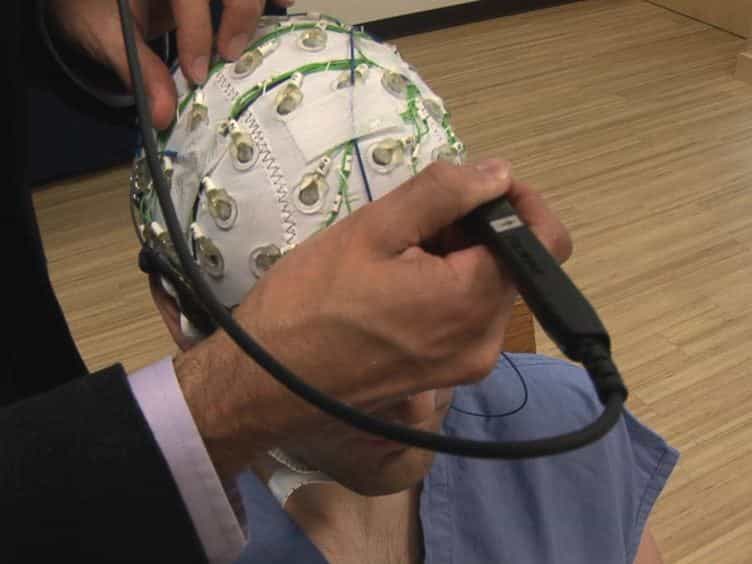

Mapping Cortical Dynamics Using Simultaneous MEG/EEG and Anatomically-constrained Minimum-norm Estimates: an Auditory Attention Example
Published on: October 24, 2012
TriGA-Net: a graph attention network for brain-controlled speaker extraction
Youhao Si1, Yuan Liao2, Qiushi Han1
1College of Electronic and Optical Engineering & College of Flexible Electronics (Future Technology), Nanjing University of Posts and Telecommunications, Nanjing, People's Republic of China.

Abstract:
Objective.Electroencephalography (EEG)-guided target speaker extraction aims to recover the listener's attended speech from mixed speech. However, effectively representing and integrating the target-related information shared between EEG and speech remains challenging. This study focuses on this challenge.Approach.We propose TriGA-Net, a Graph Attention Network for Brain-Controlled Speaker Extraction, in which EEG recorded from the listener is used to guide target speech extraction. The EEG encoder combines multi-scale temporal features and frequency-domain features with graph convolution to model dependencies among electrodes, while self-attention captures interactions across the full set of EEG channels. The resulting EEG representation is fused with encoded speech features and passed to a MossFormer2 separator. By combining MossFormer with a recurrent module that does not rely on recurrent neural networks, the separator models long-range context together with the rhythmic and prosodic structure of speech.Main results.Experiments on the public Cocktail Party and KU Leuven (KUL) datasets yielded scale-invariant signal-to-distortion ratio (SI-SDR) values of 15.91 and 16.90 dB, respectively. Compared with the strongest baseline on each dataset, TriGA-Net improved SI-SDR by 1.96 dB on the Cocktail Party dataset and by 2.30 dB on the KUL dataset. Additional improvements were observed in short-time objective intelligibility (STOI) and extended STOI (ESTOI) on both datasets and in perceptual evaluation of speech quality on the KUL dataset.Significance.These results suggest that jointly modeling temporal-frequency EEG information, inter-electrode relationships, and long-range speech structure is effective for EEG-guided target speaker extraction.