Leakage-audited benchmarking reveals limited evidence for cross-subject auditory-evoked EEG vowel perception decoding
Related Experiment Video
Updated: Sep 12, 2026
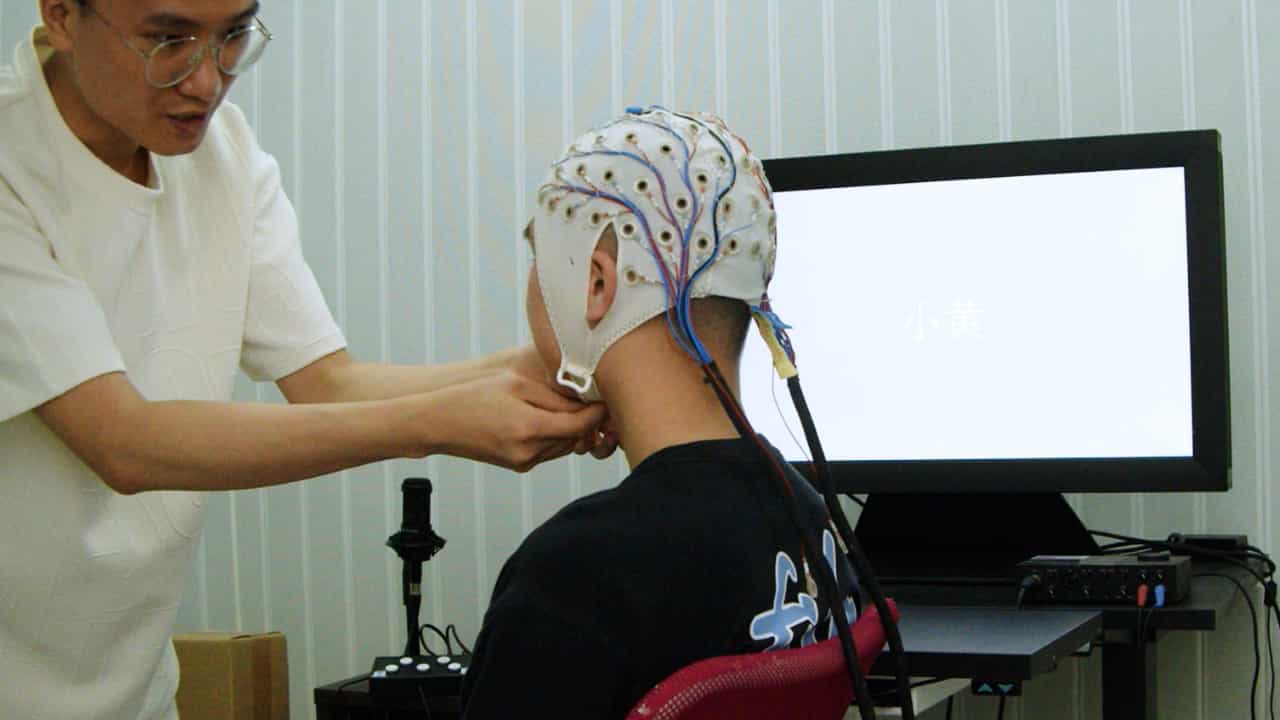
Memorization-Based Training and Testing Paradigm for Robust Vocal Identity Recognition in Expressive Speech Using Event-Related Potentials Analysis
Published on: August 9, 2024
1College of Medicine and Biological Information Engineering, Northeastern University, Shenyang 110016, People's Republic of China.

Abstract:
Objective.We evaluated cross-subject five-vowel perception decoding from auditory-evoked EEG with explicit trial definitions, participant-grouped validation, complete prediction coverage, and participant-level inference.Approach.We parsed all Study 2 event tables from OpenNeuro ds006104 version 1.0.1 and analysed the consonant-vowel (CV) pair task. Marker-stimulus pairing converted 7680 event rows into 3840 independent CV trials. Excluding active-condition trials left 1280 eligible control trials. A 400V maximum across-channel peak-to-peak criterion rejected 186 epochs, retaining 1094 epochs from 16 participants and 61 EEG channels. Thirteen unique implementations underwent leave-one-subject-out testing. Participant metrics came from 36 102 trial predictions across 33 complete replicas. Descriptive analyses assessed deep-model stability across five seeds, class-resolved errors, and retention sensitivity. An exploratory MDM analysis comprised 9616 genuine model refits across training cohorts of 3-15 participants.Main results.Two independent cohort-construction implementations preserved the same ordered 1094 trials and labels (maximum tensor difference,V). Thus, corrected accounting changed the reported exclusion decomposition but not the analysed cohort or model inputs. Random Forest achieved the highest mean balanced accuracy: 21.474% (95% participant-bootstrap interval, 19.526%-23.482%; five-class chance, 20%). The one-sided Wilcoxon, Bonferroni-adjusted, and sign-flipvalues were 0.090 897, 1.000 000, and 0.092 791, respectively. All 13 implementations remained non-significant after multiplicity correction. Deep-architecture means were near chance, with substantial within-participant seed ranges and low trial-label agreement for several architectures. Across 3-15 training participants, refitted MDM means ranged from 20.553% to 20.922%, without a monotonic increase.Significance.This dataset and protocol provide limited evidence for cross-subject five-vowel decoding. Explicit trial units, participant-grouped validation, complete seed reporting, prediction-level traceability, and multiplicity-adjusted inference sharpen the interpretation of small-cohort EEG benchmarks.