Related Experiment Video
Updated: Sep 11, 2026
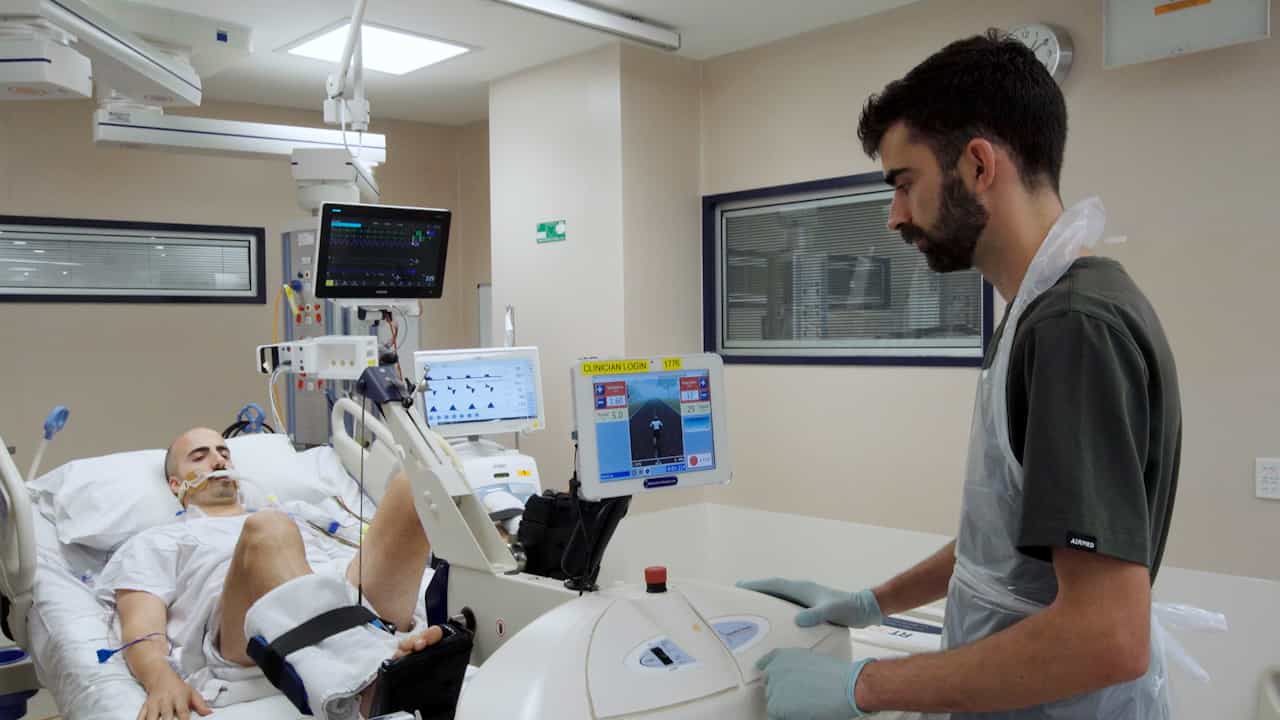

Implementing In-bed Cycle Ergometry for Mechanically Ventilated Patients using the Rehabilitation Treatment Specification System
Published on: July 7, 2026
ChatGPT-generated rehabilitation programs in sports physiotherapy: an expert evaluation and a mixed-methods study of
Adem Cali1, Mehmet Erdem Yorukoglu2, Gorkem Acar3
1Faculty of Health Sciences, Department of Occupational Therapy and Rehabilitation, Istanbul Topkapi University, Istanbul, Türkiye.

Background:
Individualized rehabilitation supports safe return to sport, yet clinical workload may limit personalized program design. This study evaluated ChatGPT-4.1-generated programs for five sports injury scenarios using a structured rubric scored by two independent sports physiotherapy experts and examined inter-rater reliability and clinical applicability.
Methods:
Mixed-methods design combining rubric scoring with deductive qualitative content analysis of expert commentary. Five cases covered muscle (hamstring strain), ligament (anterior cruciate ligament [ACL] reconstruction), tendon (rotator cuff tendinopathy), neural (lumbar disc herniation) and bone (clavicle fracture) injuries. Exactly one 6-week tabular program per case was generated with ChatGPT-4.1 from a standardized prompt in a fresh session with memory, cross-chat history and custom instructions disabled. Two sports physiotherapists (>20 years' experience) independently rated accuracy, exercise selection, progression and applicability on 1-5 scales, blinded to each other's ratings, the verbatim prompt (including the imposed six-week horizon), model identity and study aims, while retaining the clinical scenario. ICC[2,1] (two-way random-effects, absolute agreement) with 95% CIs was computed across the 20 case × criterion units; exact and within-one-point agreement, weighted κ and Bland-Altman limits were supplementary.
Results:
The overall mean of 40 ratings was 3.85 ± 1.21 (95% CI 3.48-4.22), reported alongside disaggregated case- and criterion-level values. Case 5 (clavicle fracture) scored highest (5.00 ± 0.00), Case 2 (ACL) lowest (1.88 ± 0.83, 95% CI 1.18-2.57); exercise selection scored highest (4.20 ± 1.32, 95% CI 3.26-5.14), clinical applicability lowest (3.60 ± 1.26, 95% CI 2.70-4.50). Inter-rater reliability was good (ICC[2,1] = 0.84, 95% CI 0.52-0.94; p < 0.001); exact agreement 65%, within-one-point agreement 95%, weighted κ = 0.69. Experts praised structural organization and progression logic but noted weakness in multifactorial, postoperative-timing-sensitive cases.
Conclusion:
ChatGPT-4.1 generates plausible, structured programs for linear, protocol-based recovery (e.g., post-fracture), but performance declines markedly in complex, postoperative-staging-sensitive cases; it should serve as a clinician-supervised support tool, not an autonomous decision-maker. Because the six-week length was fixed across all scenarios, case complexity and prompt-scenario congruence are confounded. Findings rest on five programs from one prompting strategy and model, requiring confirmation in larger multi-prompt, multi-model studies.