Related Experiment Video
Updated: Sep 15, 2026


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Autogenerating a Domain-Specific Question-Answering Data Set to Enable High-Performing Language Models for Magnetic
Charles R Kelly1, Jacqueline M Cole1
1Ray Dolby Centre, Cavendish Laboratory, Department of Physics, University of Cambridge, J. J. Thomson Avenue, CambridgeCB3 0US, U.K.

Abstract:
Domain-specific language models are attractive because they can be tailored to suit their users. However, the high-end computational resources needed to pretrain large language models (LLMs) by conventional methods tend to prohibit their development. Furthermore, there is a dearth of large, domain-specific, question-answering (QA) data sets to finetune LLMs for prompt engineering, even when computational resources can be found to pretrain LLMs. Our paper presents a method for autogenerating a data set of 168,080 domain-specific QA pairs relating to magnetic materials. We show how this can be employed to finetune LLMs for the downstream task of Question-Answering (QA) for the magnetic materials domain. We use the bidirectional encoder representations from transformers (BERT) architecture as our benchmark LLM to compare the relative performance of 6 LLMs. These include 3 vanilla (BERT-base-cased) LLMs that have been finetuned on various QA data sets (i) our domain-specific QA data set (MagQA); (ii) the Stanford Question-Answering Data set (SQuAD v2); (iii) our QA data set mixed with SQuAD v2. The other 3 (BERT-base-cased) LLMs have been subjected to domain-adaptive pretraining on a corpus of 97,308 magnetic papers prior to their finetuning on the same combination of QA data sets (i)-(iii). As well as our QA data set autogeneration pipeline, we show how our work can be extrapolated to the larger architectures of RoBERTa-base and DeBERTa-base. We also undertake an ablation study of the finetuning process using four sizes of QA data sets to gain insights into the quantity of data that are needed for sufficient domain-specification. The highest performing LLM was MagBERT_MagQA_Mixed, a vanilla BERT-base-cased LLM that had been finetuned on the combination of our autogenerated MagQA data set and SQuAD v2, achieving an F1 score of 78.43% and an exact-match score of 72.84% when tested on a manually annotated data set on magnetic materials. These results demonstrate that domain-specific BERT models only need to be finetuned from vanilla BERT models (i.e. no domain-adaptive pretraining is needed), pending the availability of sufficiently large, high-quality, domain-specific QA data sets that this work shows how to autogenerate.
Related Concept Videos
 01:31
Ferromagnetism
 01:23
Energy In A Magnetic Field
Take an ideal inductor with zero resistance. Although it's practically impossible, assume that the coil's resistance is so small that it is practically negligible. The loss of the field's energy to dissipate thermal energy (or heat) is thus negligible.
The energy...
 01:25
Magnetic Field due to Moving Charges
Consider a point charge moving with a constant velocity. Like the electric field, the magnetic field at any point is directly proportional to the magnitude of the charge and inversely proportional to the square of the distance between the source point and the field point. However, unlike the electric field, the magnetic field is always perpendicular to the plane containing the line...
 01:05
Atomic Nuclei: Magnetic Resonance
 01:31
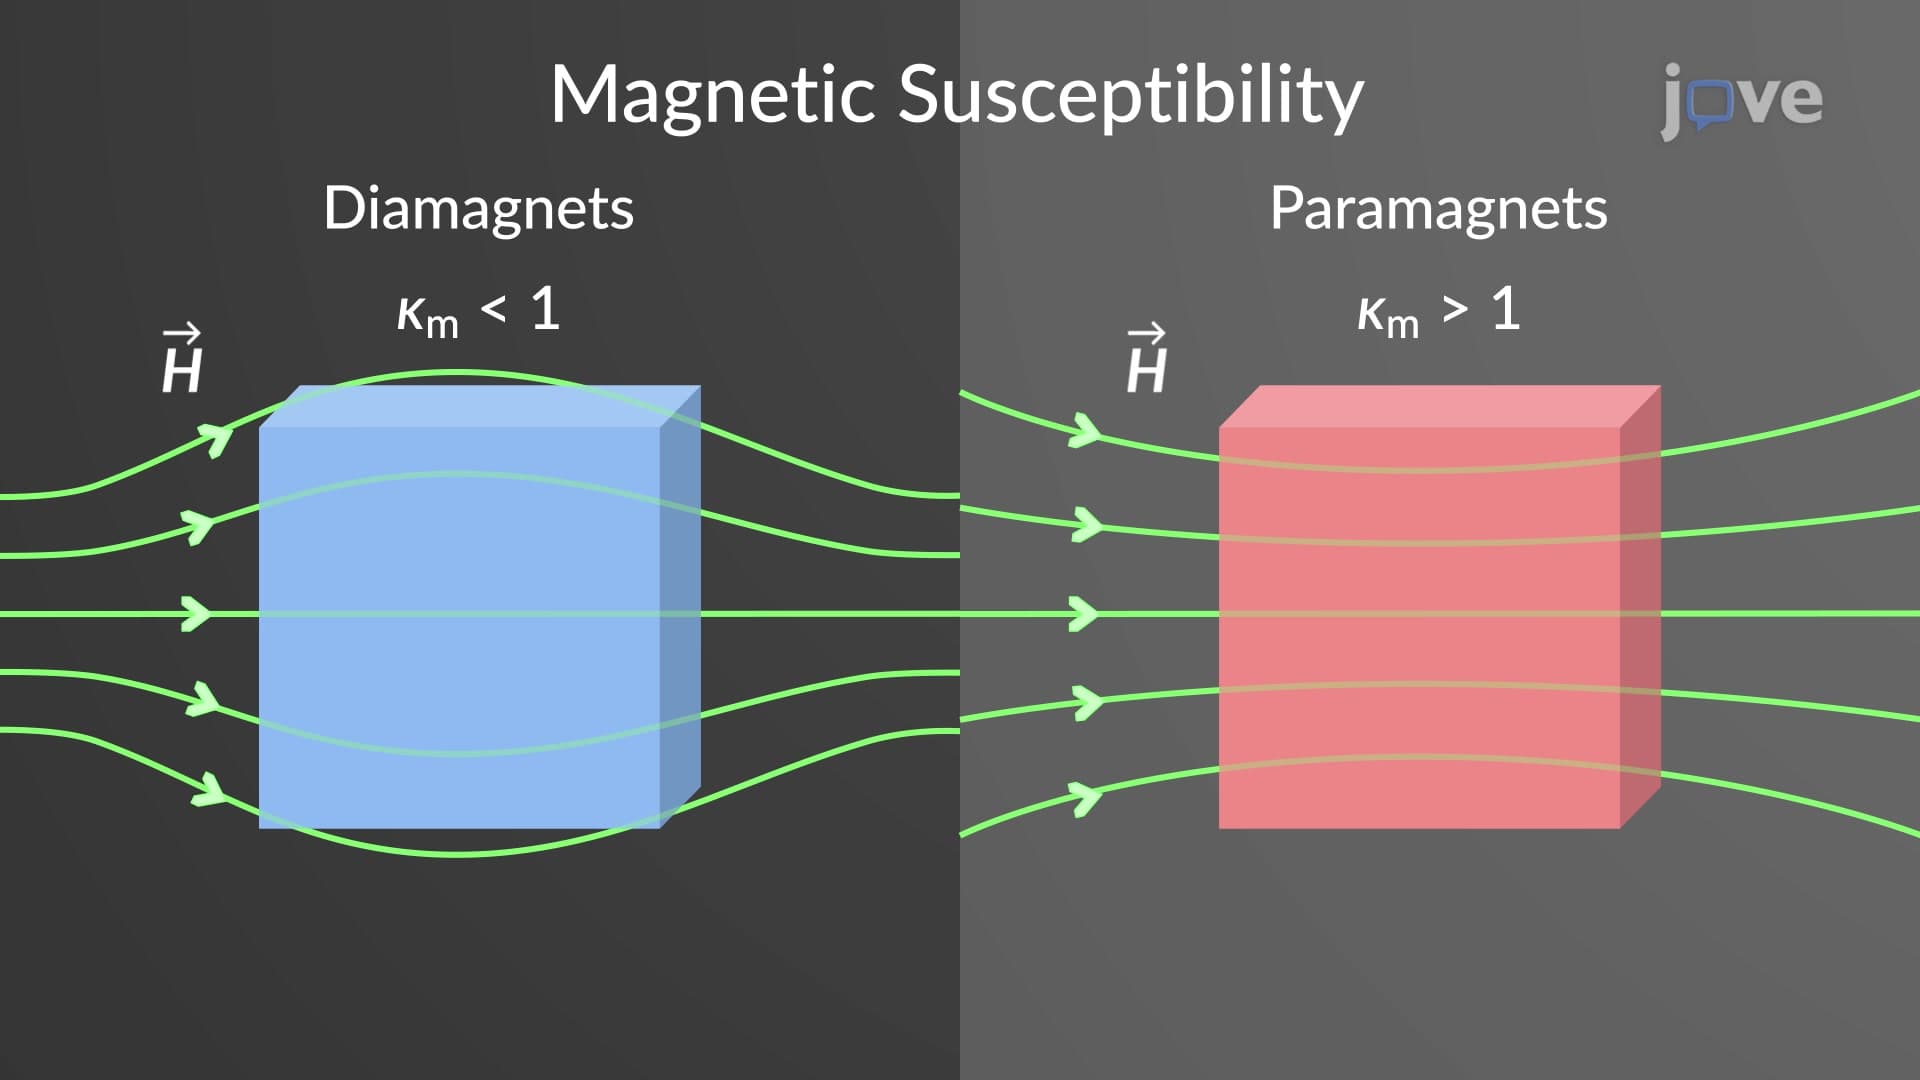
Magnetic Susceptibility and Permeability
When diamagnetic materials are placed under an external magnetic field, the moments opposite to the field are induced. Hence, the susceptibility for diamagnets has a minimal negative value of 10-5–10-6. Since...
 01:26
Diamagnetism
Diamagnetism was discovered by Anton Brugmans in 1778 when he observed that bismuth gets repelled by magnetic fields, thus theorizing that diamagnets get repelled by magnets.