Related Experiment Video
Updated: Sep 16, 2026
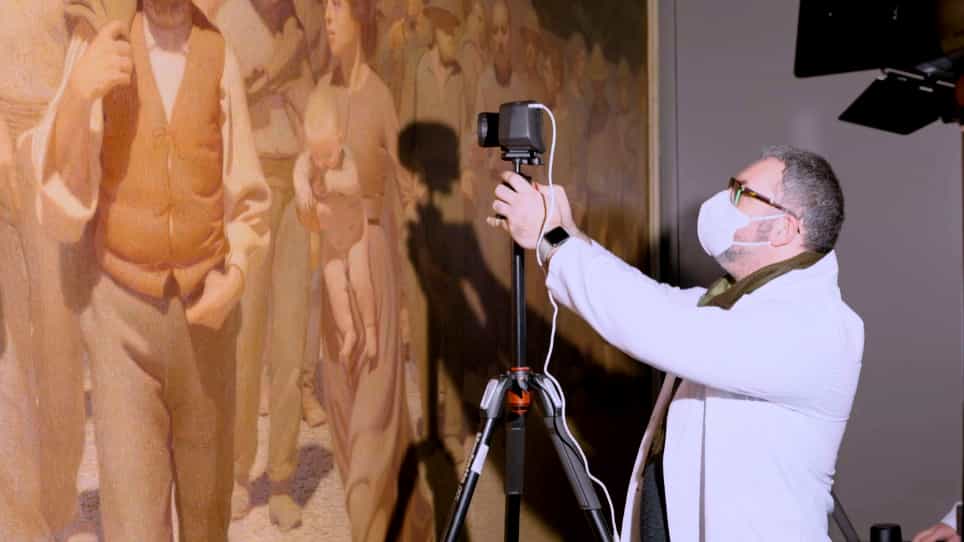

Applying Hyperspectral Reflectance Imaging to Investigate the Palettes and the Techniques of Painters
Published on: June 18, 2021
Explainable Superpixel-Guided Graph Vision Transformer for Hyperspectral Image Analysis
Jieli Chen1,2, Kah Phooi Seng3,4, Chee Shen Lim1
1School of Advanced Technology, Xian Jiaotong-Liverpool University, Suzhou 215123, China.

Abstract:
Hyperspectral imaging provides rich spectral-spatial information for fine-grained material discrimination, but effective and interpretable modeling remains challenging because land-cover regions often have irregular spatial structures and class-specific spectral responses. Conventional methods typically rely on fixed grid patches or local neighborhoods, which may not align with natural object boundaries, whereas pure superpixel or graph models may lose fine pixel-level details. This paper proposes an explainable superpixel-guided graph vision transformer (ESG-ViT) for hyperspectral image classification and analysis. The proposed framework contains two complementary branches: a graph superpixel vision transformer (GS-ViT) that represents hyperspectral scenes as adaptive superpixel tokens and injects graph topology into self-attention, and a windowed pixel vision transformer (WP-ViT) that preserves dense local spectral-spatial details through efficient local attention. The two representations are adaptively fused for pixel-wise classification. To support interpretability, the model further derives class-wise superpixel relevance maps and spectral channel importance from gradient responses, revealing both the spatial regions and wavelength channels that contribute to each category. Experiments on multiple benchmark hyperspectral datasets demonstrate that the proposed method improves classification accuracy while producing clearer, more human-aligned explanations. Visualization results show that the model highlights meaningful class-related superpixel regions and assigns distinct spectral-channel importance patterns to different classes. These results indicate that the proposed framework provides an accurate and explainable alternative to conventional patch-based transformers for hyperspectral image analysis.