Head-Decoupled Logit Distillation Framework for Boosting Logit Transfer Across Tasks
Related Experiment Video
Updated: Oct 8, 2026

Generating the Transcriptional Regulation View of Transcriptomic Features for Prediction Task and Dark Biomarker Detection on Small Datasets
Published on: March 1, 2024

Abstract:
The efficacy of logit transfer in knowledge distillation (KD) is often hampered by disparities in model architectures and imbalances in data distributions. Existing decoupled distillation methods predominantly rely on rigid category partitioning (e.g., target vs. non-target), failing to adapt to varying logit scales across different teacher models and showing instability in long-tailed learning scenarios. In this paper, we propose Head-Decoupled Logit Distillation (HDLD), a novel framework that redefines the distillation decoupling process from the perspective of instance-specific dynamic semantic structures. By introducing a dynamic gating mechanism, HDLD decouples logits into Head Category Knowledge Distillation (HCKD) and Non-Head Knowledge Distillation (NHKD). This approach adaptively extracts core semantic correlations based on sample characteristics, effectively filtering background noise in long-tailed settings and rectifying decision boundary collapse. Extensive experiments on image classification and object detection benchmarks demonstrate that HDLD consistently outperforms state-of-the-art methods, validating its superior robustness and transferability across diverse architectures and tasks. Our code can be found at https://github.com/Hans-KnowledgeDistillation/HDLD.
Related Concept Videos
 01:01
Distillation: Vapor–Liquid Equilibria
 01:14
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an organic...
 01:15
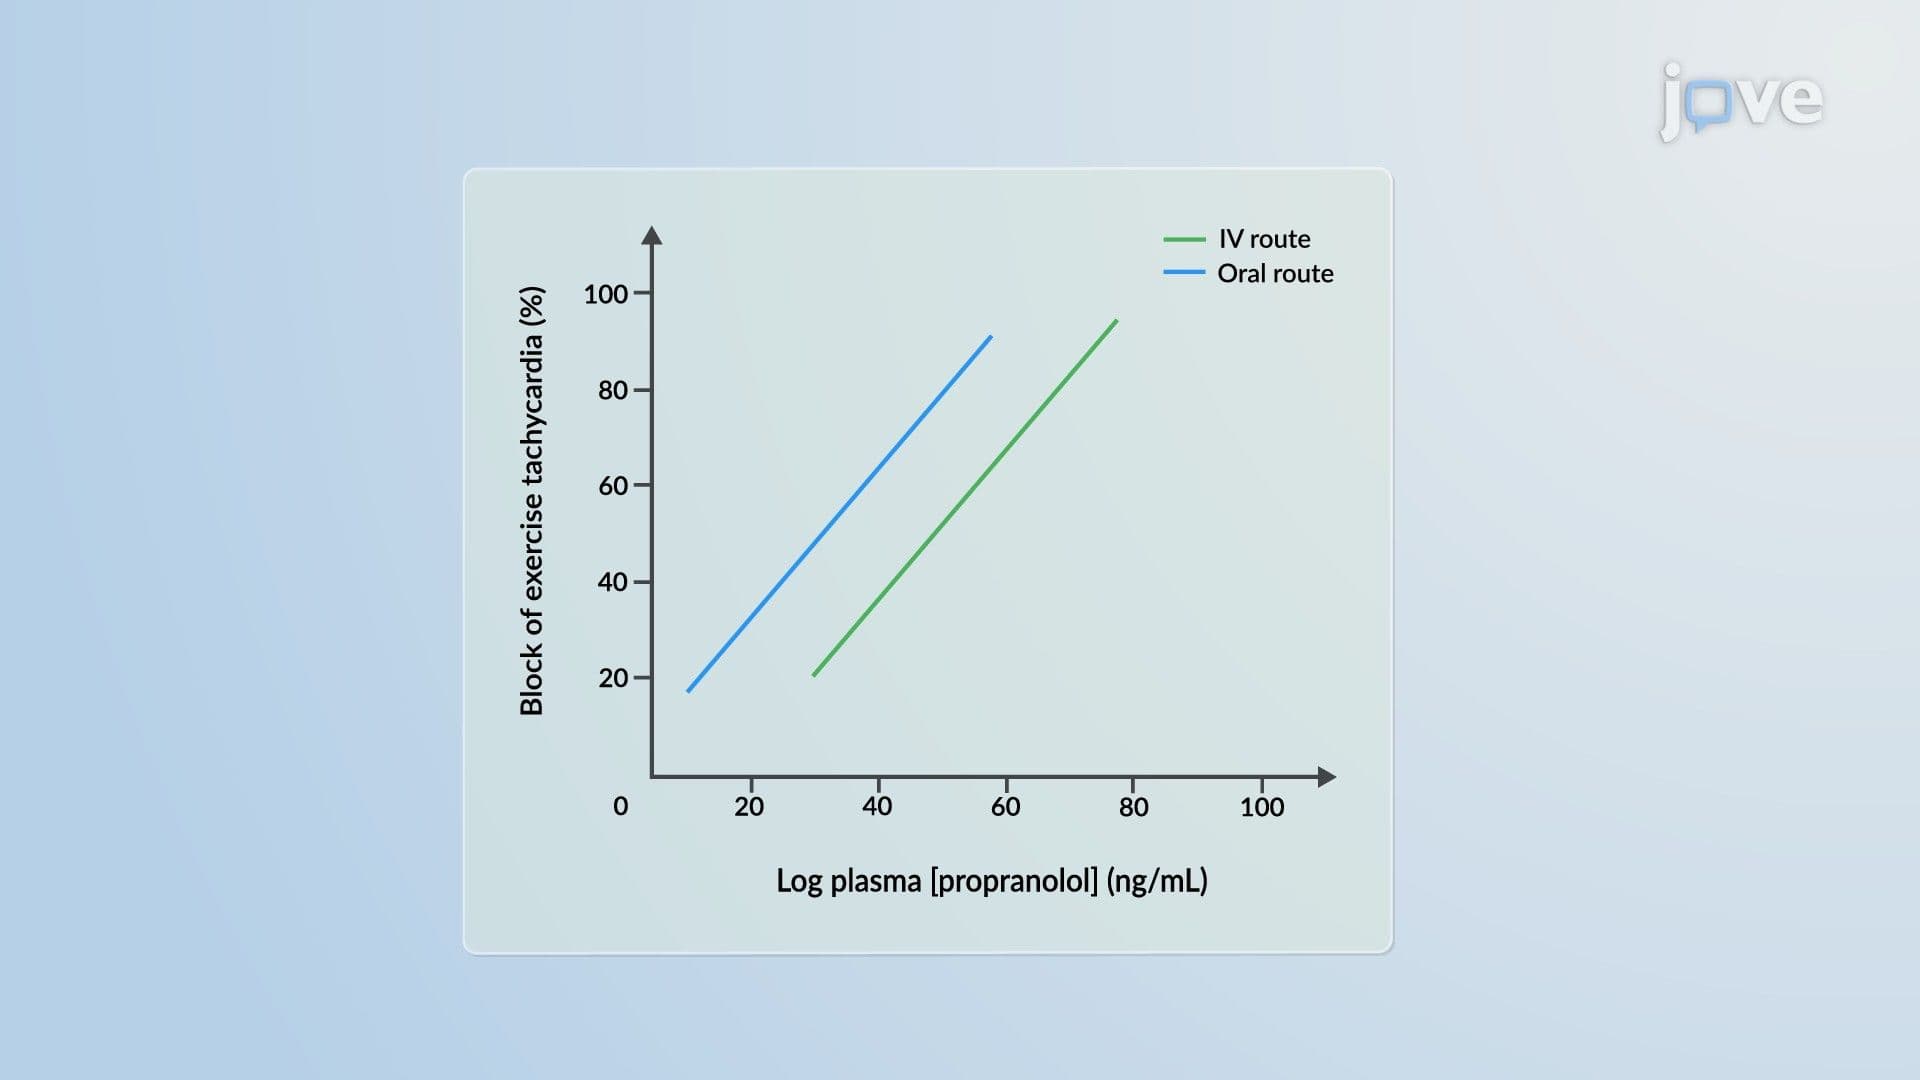
Pharmacodynamic Models: Logarithmic Concentration–Effect Model