Related Experiment Video
Updated: Sep 18, 2026

Standardized Modular Assembly of Polycistronic Operons with Modular Cloning (MoClo) using the In-Cloning toolkit
Published on: September 2, 2025
MoEP: Compact and efficient sparsity with modular expert paths
Joonas Tapaninaho1, Mourad Oussalah1
1University of Oulu, Faculty of ITEE, CMVS, Pentti Kaiteran Katu 1, Oulu, 90570, Finland.

Abstract:
The transition from dense to sparse model architectures has become a key trend in the field of Large Language Models (LLMs). Mixture-of-Experts (MoE) methods can be used to increase model conditional representation capacity by activating only a subset of parameters for each input token. However, the practical efficiency of such sparsity depends on the routing design and hardware implementation. This paper introduces MoEP (Modular Expert Paths), a layer-level routing architecture, which is designed to study sparsity under a fixed and comparable parameter budget. MoEP parallelizes decoder-only Transformer blocks with MoE-style linear projections to implement selective token-dependent routing across reduced-dimensional paths. Originally MoEP was developed in the BabyLM setting using GPT-2 as its architectural baseline. We extend this study by applying the same MoEP routing and overall design to additional small decoder-only baseline architectures. To further examine architectural transferability, we applied the MoEP structure to GPT-2-, LLaMA-, and Gemma-style small baselines trained under the same protocol. Each one of those baselines was converted into a MoEP variant using the same modular routing design, enabling controlled comparison across architectures. All models were trained and evaluated under the official BabyLM strict-small protocol to ensure comparability. The results show small average gains with stronger task-specific improvements, but also task-dependent decrease, which indicates that MoEP's benefits are architecture and scale dependent. A larger scale comparison using the Pythia-1B model as baseline, further suggests that the current layer-level MoEP design probably does not inherit the same scalability and efficiency advantages as standard FFN-level MoE. This is because it routes complete Attention-FFN blocks rather than only feed-forward experts.
Related Concept Videos
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:14
Multicompartment Models: Overview
These models offer a more comprehensive representation of drug behavior in the body than one-compartment models. They accommodate the complexity of drug distribution,...
 01:22
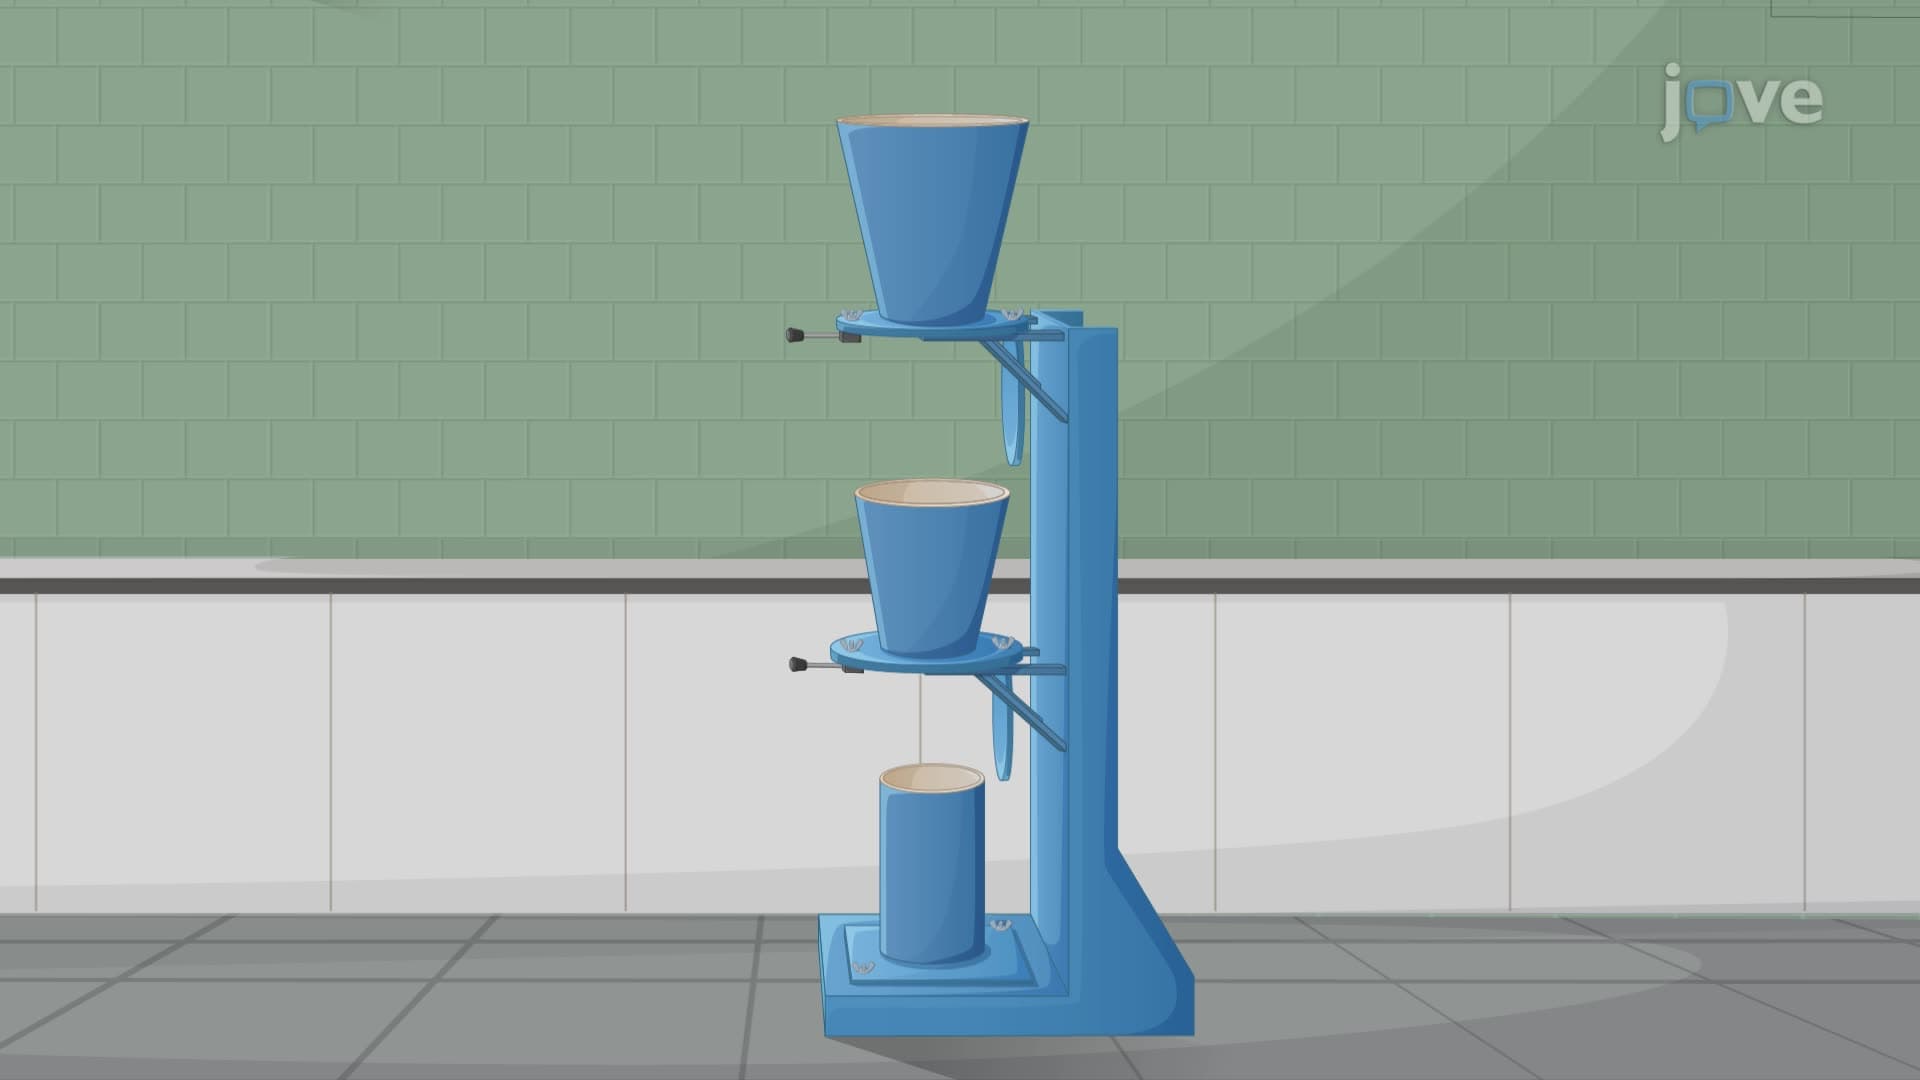
Compacting Factor test
The procedure begins by placing concrete into the upper hopper without any compaction. Once filled, the bottom door of this hopper is opened,...
 01:25
Clearance Models: Compartment Models
 01:28
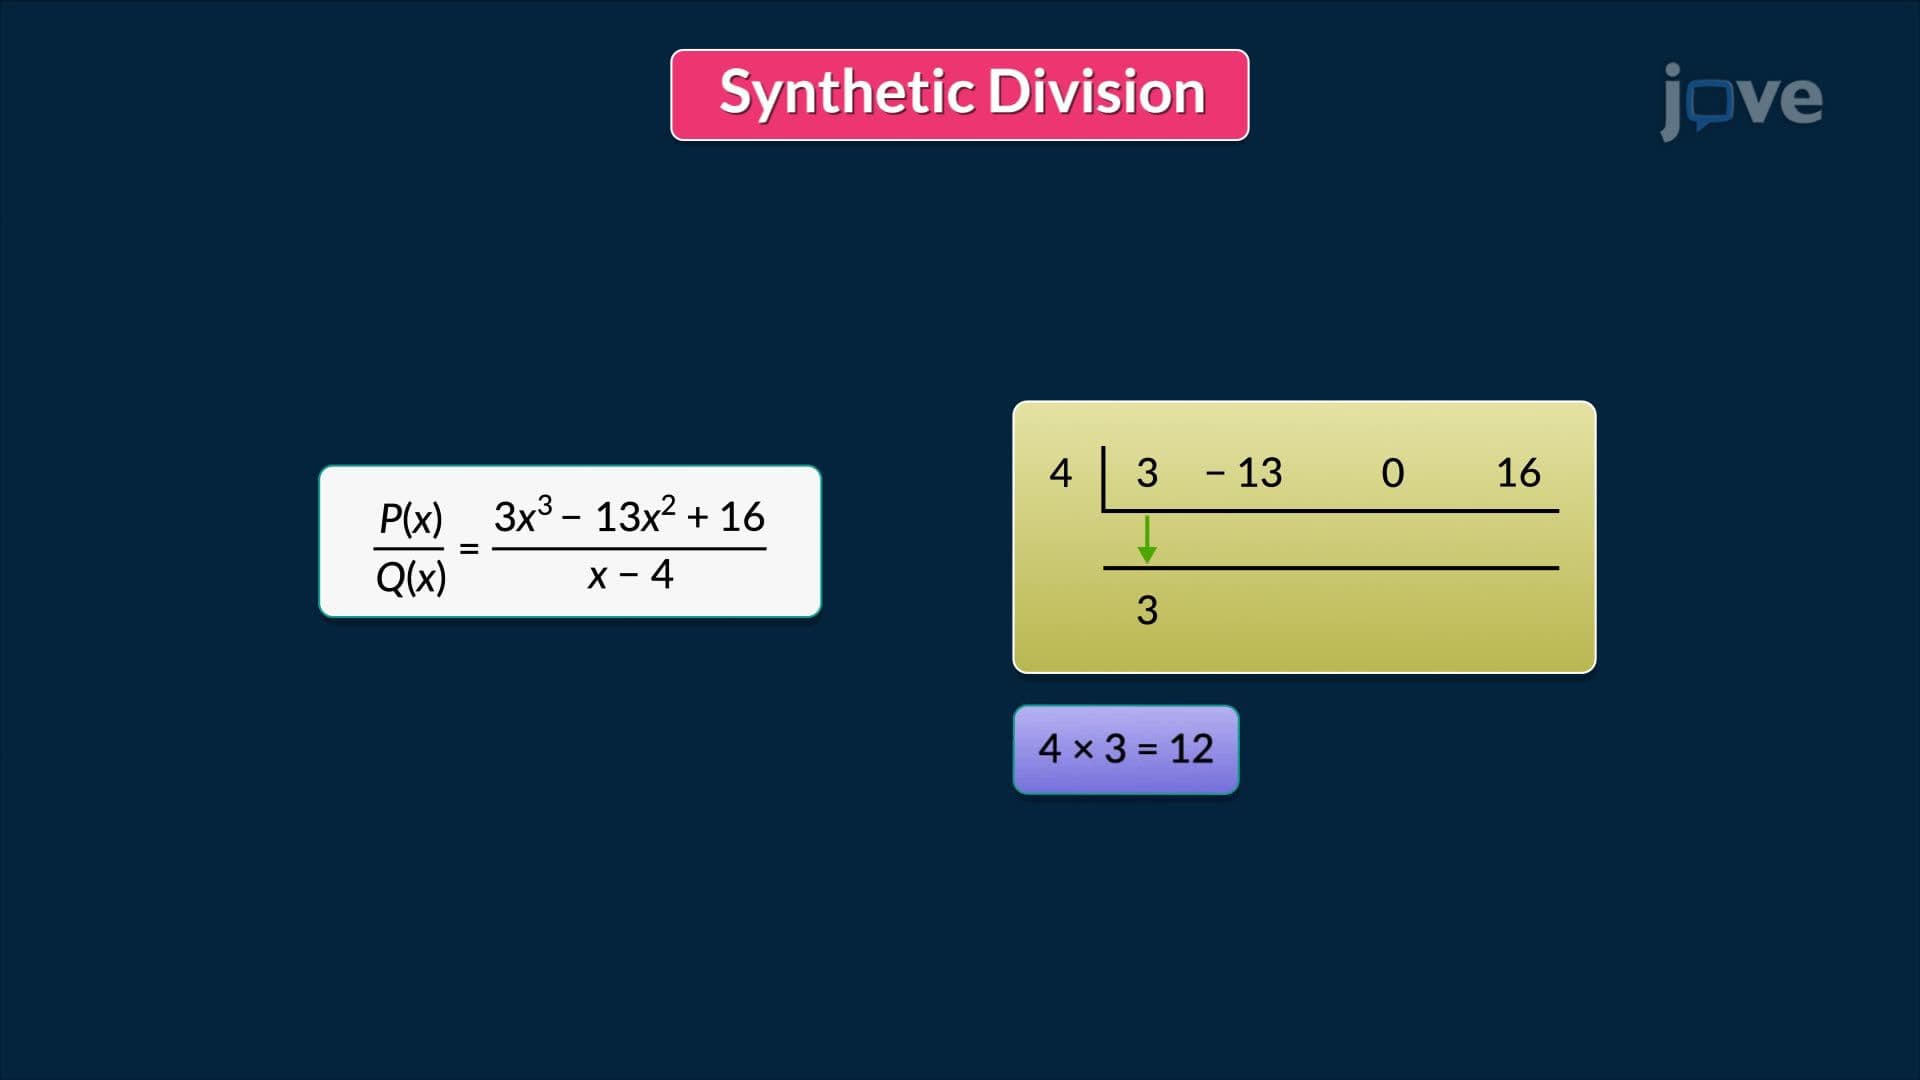
Synthetic Disvision of Polynomials
 01:28
Methods of Medium Optimization