Related Experiment Video
Updated: Sep 20, 2026


Capturing Dynamic Finger Gesturing with High-resolution Surface Electromyography and Computer Vision
Published on: March 28, 2025
Time2Vec Transformer for Robust Gesture Recognition from Low-Density sEMG
Blagoj Hristov1, Hristijan Gjoreski1, Vesna Ojleska Latkoska1
1Faculty of Electrical Engineering and Information Technologies, Ss Cyril and Methodius University in Skopje, Rugjer Boshkovikj 18, Skopje, 1000, North Macedonia.

Objective:
To determine whether temporal embeddings can recover the discriminative information lost when reducing sEMG sensing from dense electrode arrays to a sparse two-channel configuration, and under what conditions they can be integrated without degrading spatial features.
Approach:
Using a publicly available dataset of 8 subjects performing 10 dynamic finger gestures, we develop a hybrid Transformer optimized for two-channel sEMG. We identify a failure mode in standard additive integration, where the two branches differ in latent magnitude by a factor of four, so the spatial branch dominates the sum. We therefore integrate Time2Vec embeddings through a normalized additive fusion strategy that layer-normalizes both latent distributions before integration. A two-stage curriculum (augmentation-driven pre-training followed by clean-signal fine-tuning) supports robust feature extraction under data scarcity.
Main Results:
Under leave-one-subject-out cross-validation the proposed model achieves a mean F1-score of 95.9% ± 0.15%, outperforming standard additive, gated, and cross-attention fusion. A gain sweep and a parameter-free normalization variant identify scale alignment as the operative mechanism, as a learnable basis performs worse than fixed sinusoidal encodings under standard addition but exceeds them once normalized. Zero-shot transfer to unseen subjects yields 21.0% ± 2.98%, and classical hand-crafted-feature models collapse comparably, consistent with a sensing constraint rather than a representational one. Supervised calibration with two trials per gesture recovers performance to 96.9% ± 0.52%. Inference runs in 21.5ms on a consumer CPU core.
Significance:
Temporal embeddings can compensate for reduced spatial sensing density provided their integration preserves the scale of both representations, enabling rapidly personalizable myoelectric interfaces.
Related Concept Videos
 01:25
Transformers with Off-Nominal Turns Ratios
 01:16
Types Of Transformers
If the ratio of the number of turns in the secondary winding to that of the primary winding is greater than one, then the transformer is said to be a step-up transformer. In a step-up transformer, the voltage at the secondary winding is greater than the voltage applied at the primary winding.
However, if this ratio is less than one, the transformer is said to be a step-down...
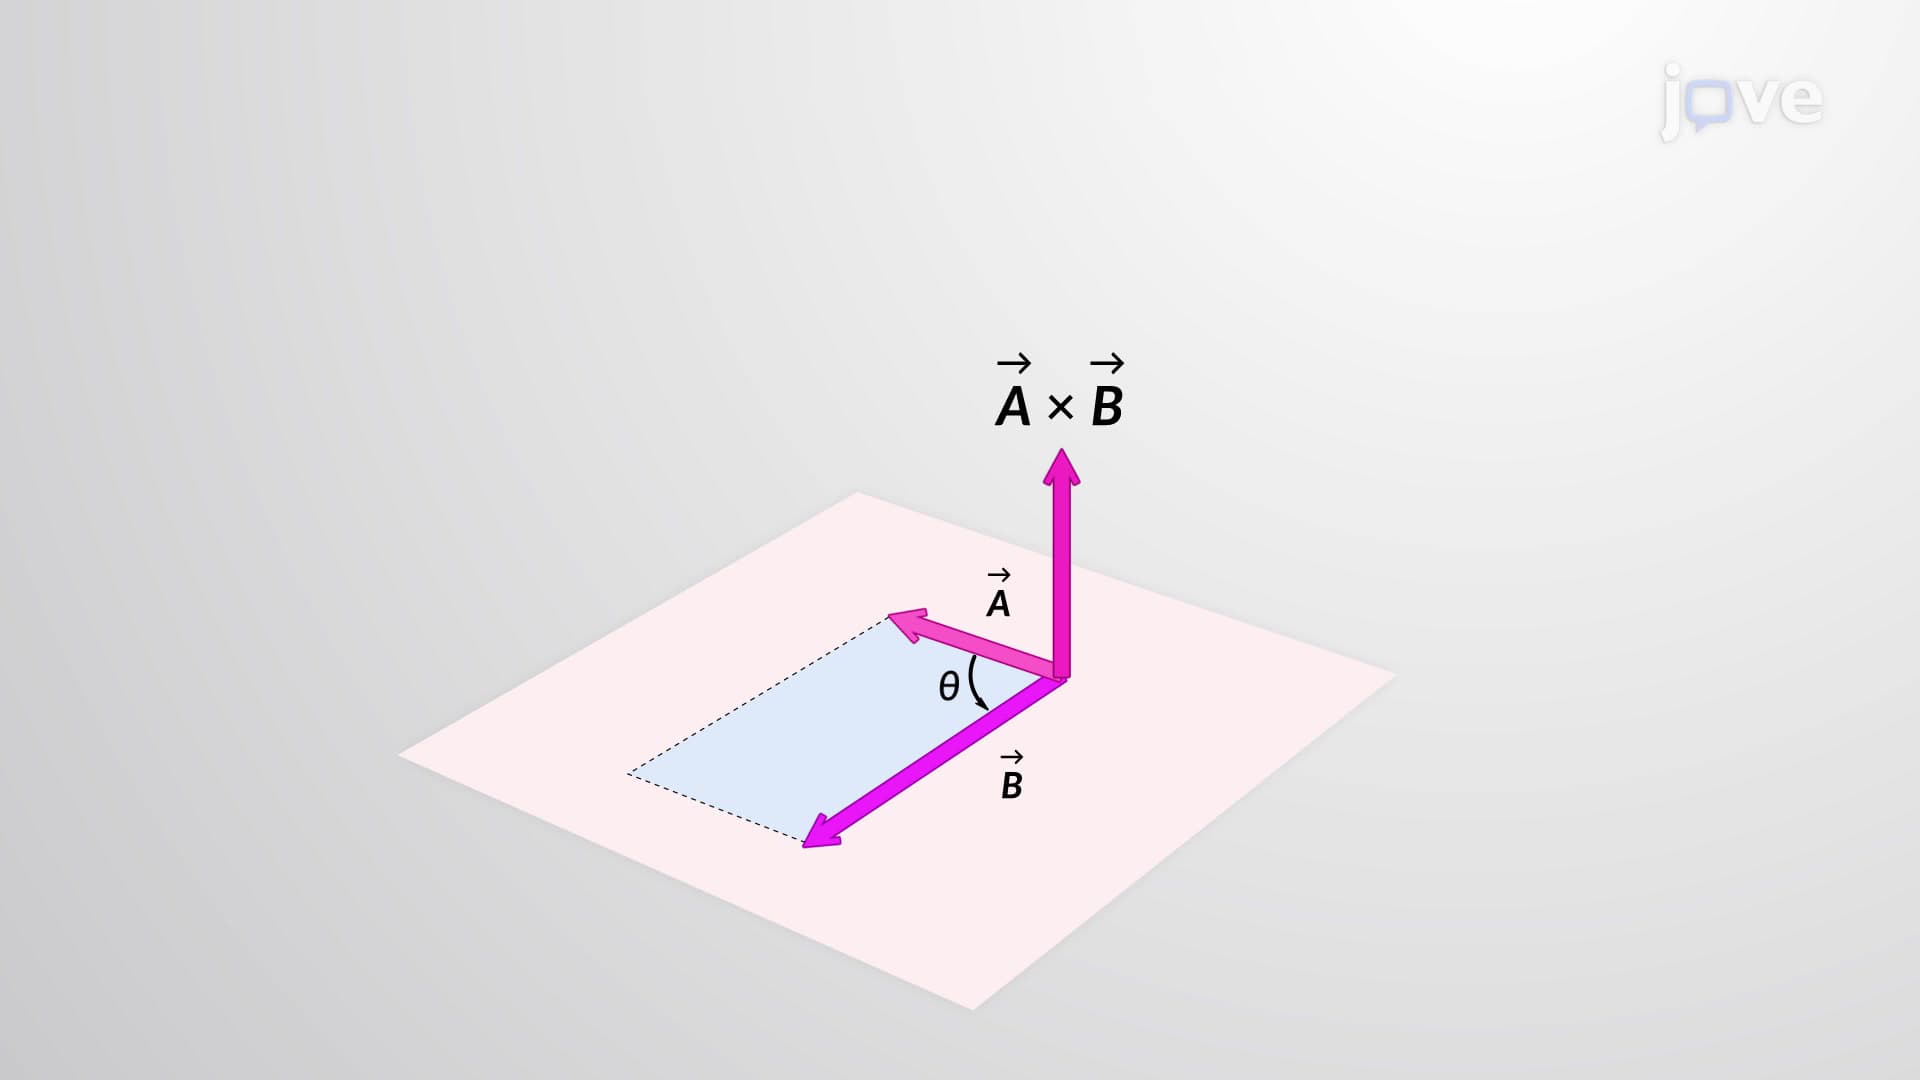 01:17
Vector or Cross Product
Consider the cross product of two vectors. Imagine rotating the first vector about...