Related Experiment Video
Updated: Sep 23, 2026

Liquid-cell Transmission Electron Microscopy for Tracking Self-assembly of Nanoparticles
Published on: October 16, 2017
Neural-network parametrization of fundamental measure theory: From hard spheres to Lennard-Jones fluids
Conrard Giresse Tetsassi Feugmo1
1University of Waterloo, University of Waterloo, Department of Chemistry, 200 University Ave. West, Waterloo, Ontario, Canada N2L 3G1 and Department of Physics, 200 University Ave. West, Waterloo, Ontario, Canada N2L 3G1.

Abstract:
We introduce a neural-network framework for parametrizing fundamental measure theory (FMT) applied to hard-sphere and Lennard-Jones fluids. Lutsko's extended scalar FMT expresses the excess free-energy density through two parameters, A and B, which control the relative weight of tensor invariants in the third-order contribution Φ_{3}; different choices recover established functionals (Rosenfeld, White Bear, and the recent optimized values of Gül et al.). We treat A and B as learnable functions of the packing fraction η=(π/6)ρσ^{3}, predicted by a small neural network and optimized end to end through a JAX-based density functional solver. Four training strategies are examined, namely matching the Carnahan-Starling equation of state, minimizing chemical-potential and compressibility deviations, optimizing wall contact densities, and a combined multiobjective loss. All four converge to parameters near the Percus-Yevick line defined by the constraint combination C=8A+2B-9≈0, with subpercent agreement with Carnahan-Starling thermodynamics. Extension to Lennard-Jones fluids via Weeks-Chandler-Andersen perturbation theory, using the temperature-dependent Barker-Henderson effective diameter to define an effective packing fraction, yields vapor-liquid coexistence with a critical temperature T_{c}^{*}=k_{B}T_{c}/ε≈1.28, consistent with mean-field DFT benchmarks. The learned parameters remain close to the fixed Lutsko baseline (A=1, B=0) throughout, confirming that bulk phase equilibria alone cannot drive nontrivial density dependence. A three-phase training strategy-bulk equation-of-state fitting, test-particle sum-rule optimization, and wall-contact density fine tuning via numerical gradients-breaks this degeneracy, yielding contact densities within 1-2% of molecular dynamics data across all benchmark packing fractions and a 5.5-fold reduction in final wall-contact loss relative to direct wall fine tuning, at the cost of 5-8% bulk thermodynamic errors that quantify a genuine bulk-interface tradeoff. These results provide a starting point for adaptive density functionals trained on inhomogeneous simulation data.
Related Concept Videos
 01:15
Dimensionless Groups in Fluid Mechanics
 01:23
Dimensional Analysis
Dimensional analysis allows us to analyze and compare physical quantities on a...
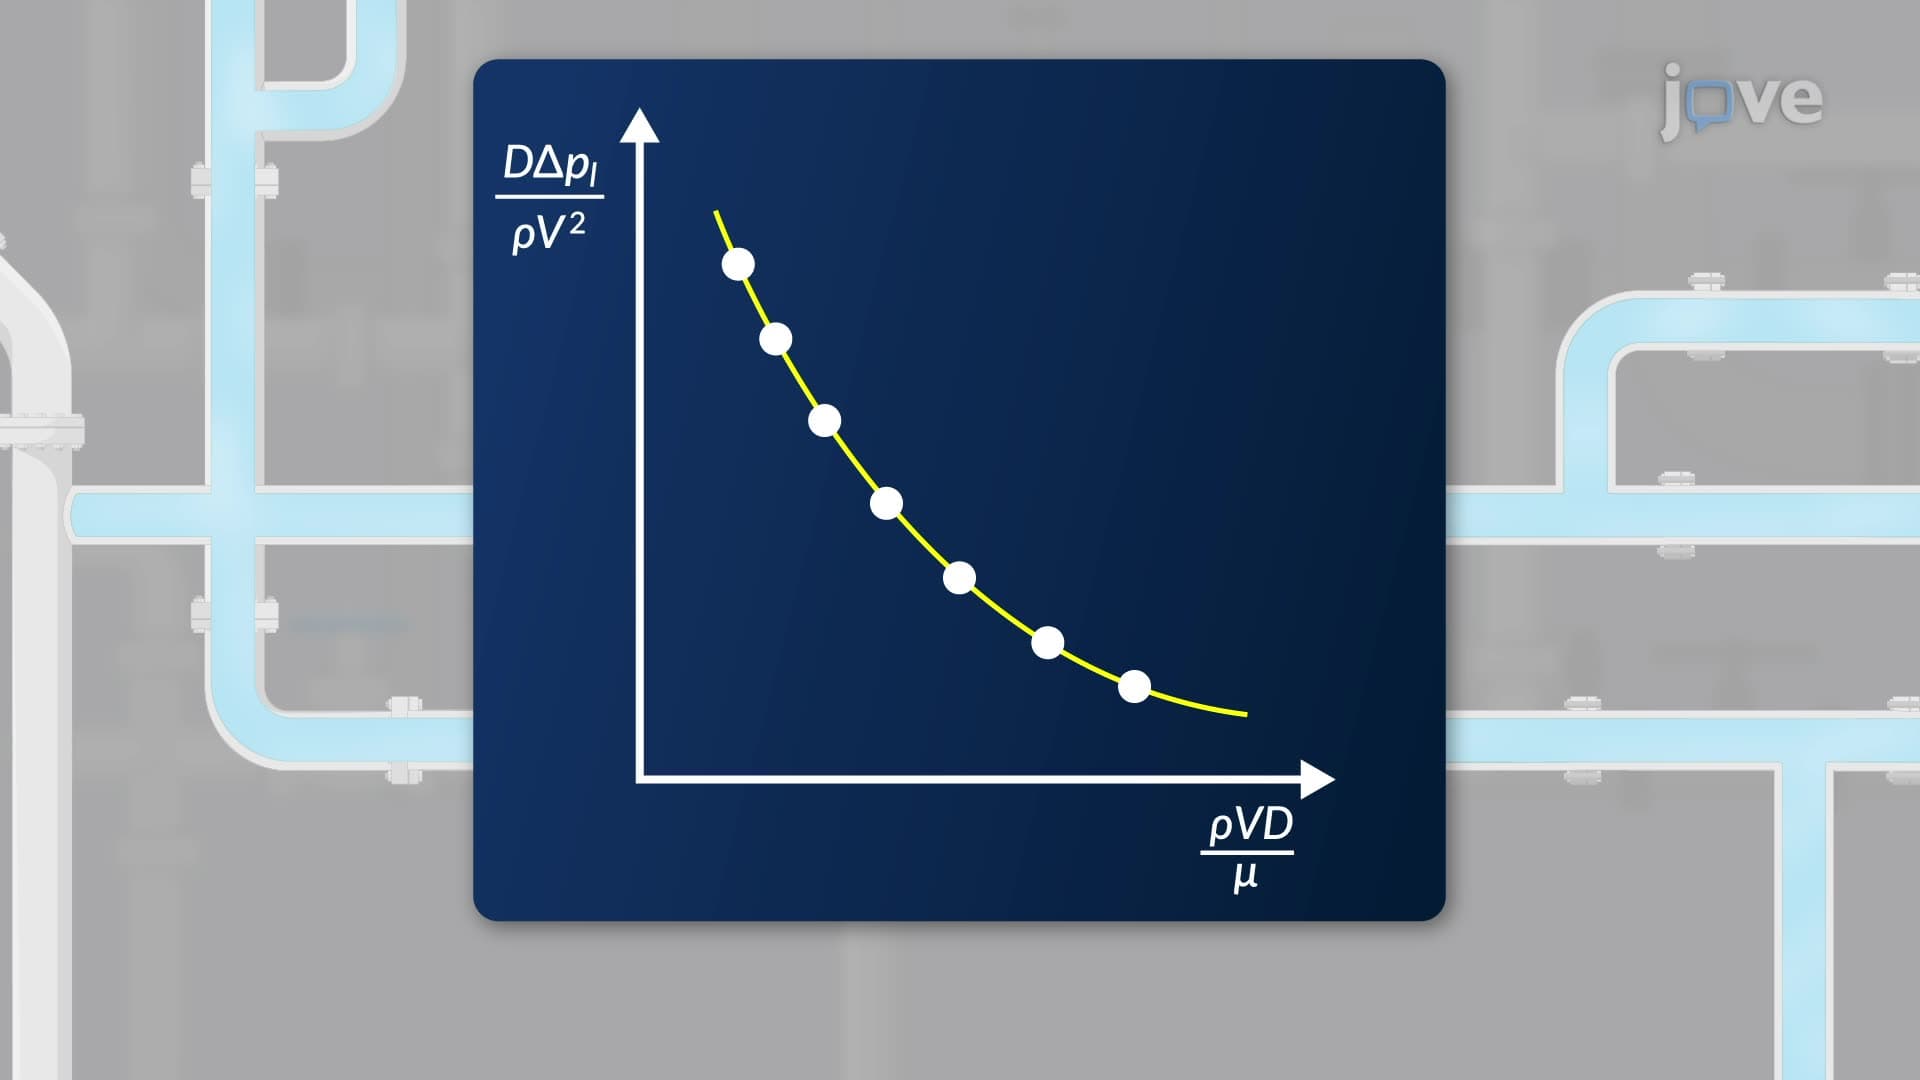 01:27
Dimensional Analysis
In fluid mechanics, dimensional...
 01:10
First Law: Particles in One-dimensional Equilibrium
 01:18
First Law: Particles in Two-dimensional Equilibrium
Newton's first law tells us about the...
 01:18
Newtonian Fluid: Problem Solving
A velocity gradient forms within the fluid when a Newtonian fluid is placed between two parallel plates, with...