Related Experiment Video
Updated: Sep 23, 2026

Leveraging CyVerse Resources for De Novo Comparative Transcriptomics of Underserved (Non-model) Organisms
Published on: May 9, 2017
Enhancing the SIB Literature Services (SIBiLS) with annotations to support biocuration
Déborah Caucheteur1,2, Alexandre Flament1,2, Julien Gobeill1,2
1HES-SO Genève, Tambourine 17, 1227 Carouge, Switzerland.

Abstract:
Text-mining techniques are essential tools to efficiently access information within an increasing number of publications. The SIB Literature Services (SIBiLS) are dedicated to the text-mining and biocuration communities. SIBiLS features an extensive repository comprising ~40 million abstracts from MEDLINE, 8 million full-text articles accessible through the National Library of Medicine (NLM) via PMC, 29 million supplementary data files, and ~1 million taxonomic treatments sourced from Plazi and other contributors. The full-text articles are also containing original Open Access journals, which are not commonly indexed by PMC but relevant for research and scientific communities, the so-called PMC + collection. SIBiLS is thus a superset of the NLM collections. Several text-processing strategies have been implemented (e.g. tokenization, hyphenation, concept normalization), leading to the enrichment of SIBiLS with automatic annotations based on term mapping from ~30 ontologies. The aim is to improve literature triage and curation time by automating the extraction and organization of relevant information from large volumes of scientific texts. The annotation process has generated over 16 billion annotations. One of the goals of this enhancement is to improve the recall of rare contents, including genomic variants and information on rare diseases. It is also used in various contexts, including studying biotic interactions and curating genomic variants through dedicated front-end applications such as the BiotXplorer and Variomes. Annotations are performed using the BioC standard. By combining JATS and BioC, SIBiLS enables curators to perform high-precision evidence tracking at any textual representation levels via an original annotation schema (e.g. IDs, onto-terminological sources, provenance). An assessment of the annotation quality has been carried out for the different annotated entities. The average annotation accuracy is approaching 90% but exhibits high variation depending on both the entity and the source vocabulary.
Related Concept Videos
 00:58
Symbiosis
 02:21
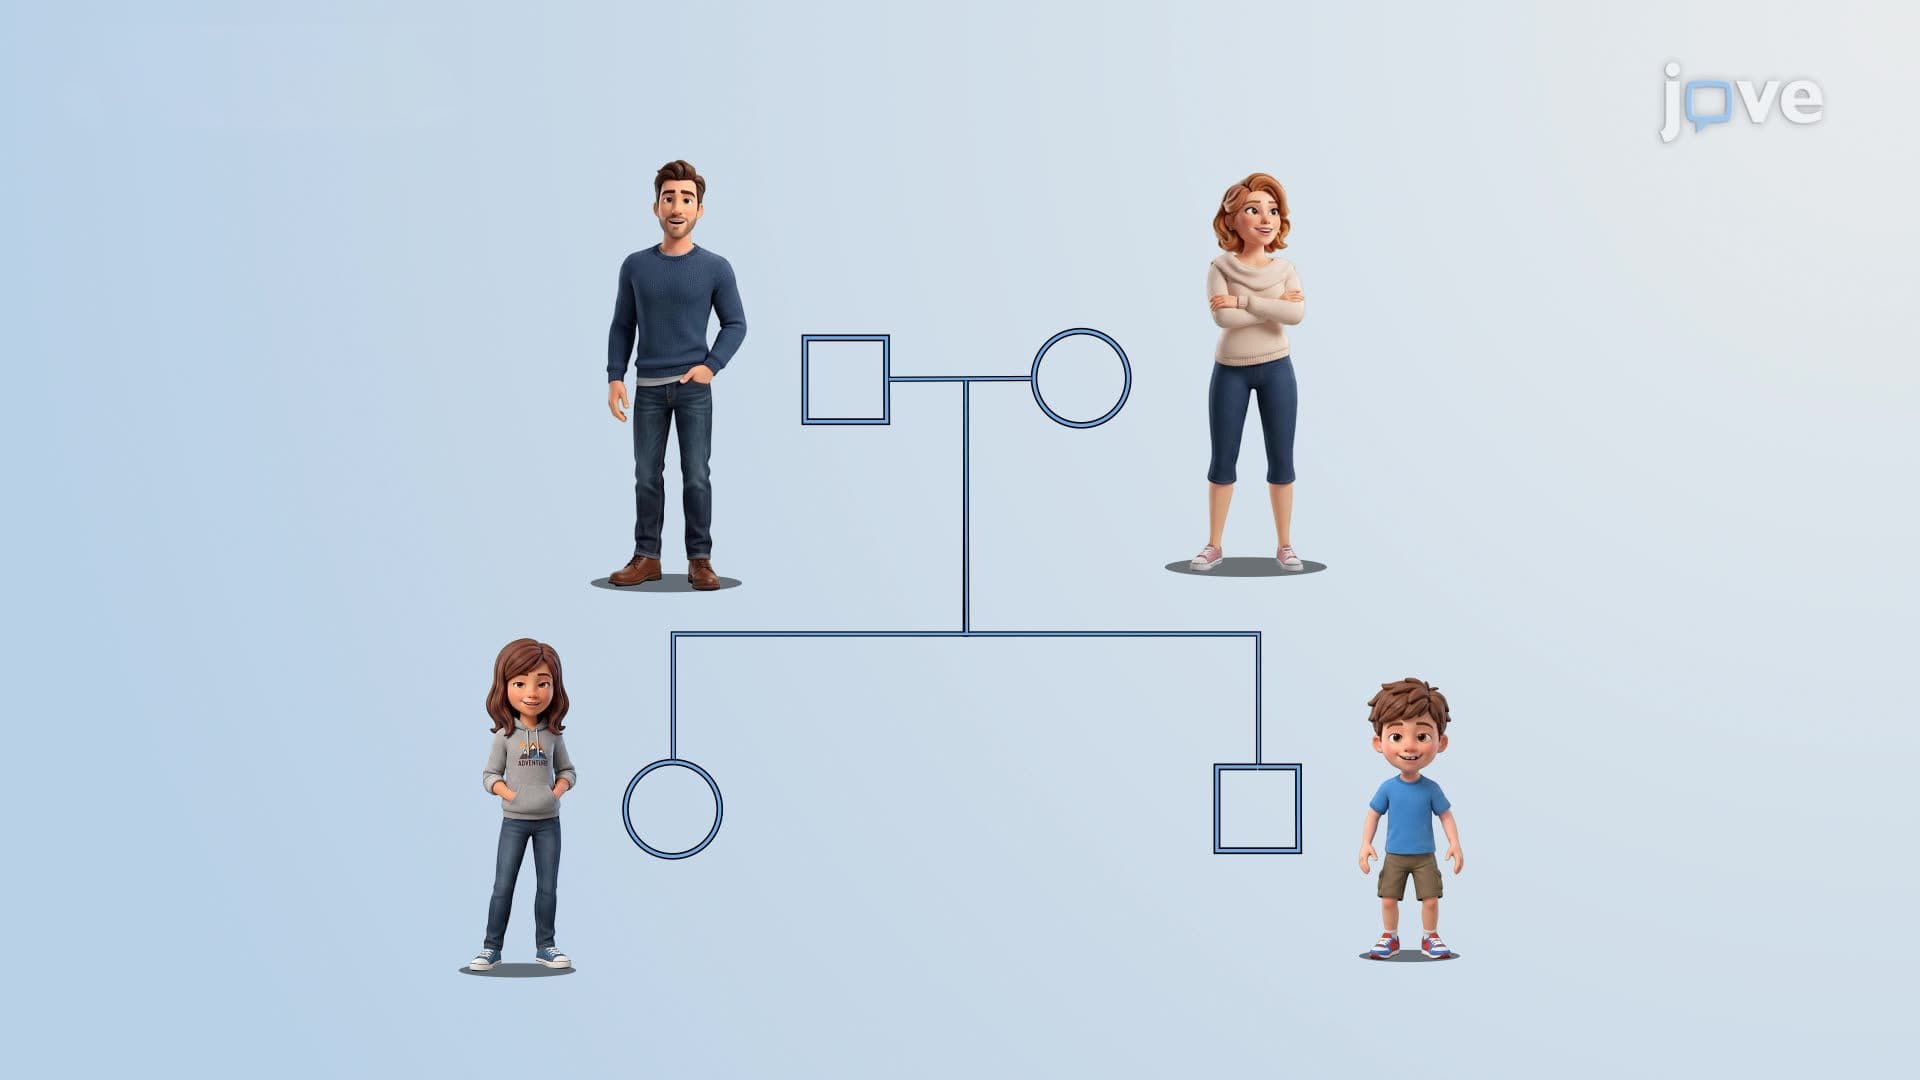
Pedigree Analysis
 01:22
Bone Marrow Sampling and Transplants
The transplant begins with high doses of chemotherapy and radiation treatment, which aim to destroy the...
 01:20
Biostatistics: Overview
Discrete variables are...
 00:46
Bioremediation
 01:19
What is Biodiversity?