Related Experiment Video
Updated: Sep 28, 2026
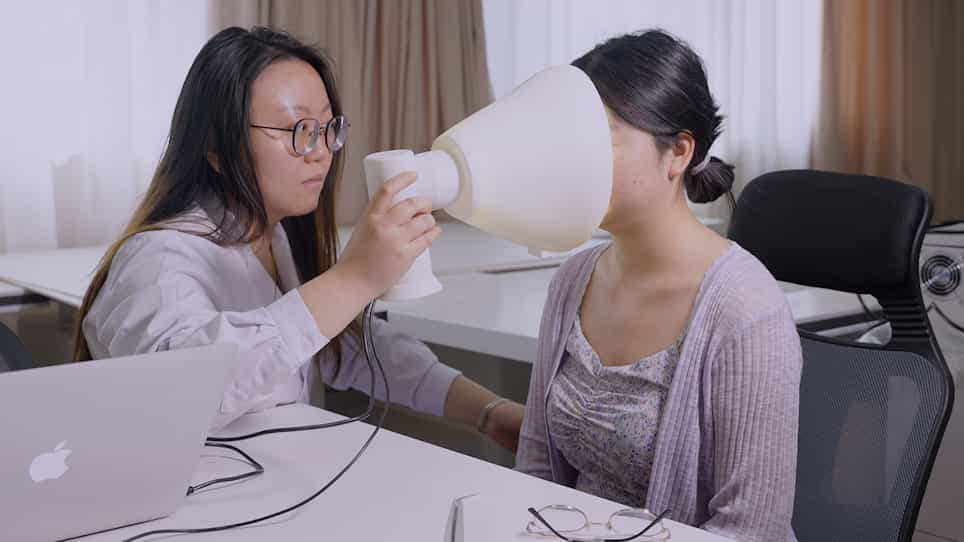

Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023
Diagnostic performance of large language models for discrepancy detection in non-English resident-authored abdominal
Mehmet Ali Ozel1, Ibrahim Feyyaz Naldemir2, Aslıhan Unal Ozen2
1Department of Radiology, Duzce University, Düzce, Turkey. drmaliozel@gmail.com.

Purpose:
To evaluate the diagnostic performance of large language models (LLMs) for detecting clinically meaningful discrepancies in non-English, resident-authored abdominal CT and MRI reports, using Turkish-language reports as a test setting, and to compare the educational quality of model-generated feedback.
Methods:
This retrospective study included 488 abdominal imaging reports, comprising 317 CT and 171 MRI examinations, each with a resident-authored preliminary report and an attending-approved final report. Two abdominal radiologists established an expert consensus reference standard using both report pairs and corresponding imaging studies. Three LLMs-GPT-5.3, Claude 4.6 Sonnet, and Gemini 3.0 Pro-were prompted to detect and classify discrepancies and generate brief educational feedback. Importantly, models evaluated text-based report pairs without direct image access. Primary outcomes were event-level discrepancy detection sensitivity and false-positive behavior; educational feedback was assessed using a 5-point Likert scale.
Results:
The reference standard identified 776 clinically meaningful discrepancies in 390 reports; 98 reports were error-free. Event-level sensitivity differed significantly among models (p < 0.001). Claude 4.6 Sonnet achieved the highest overall sensitivity (93.4%), followed by GPT-5.3 (91.9%) and Gemini 3.0 Pro (72.6%). Claude also showed the highest sensitivity for major discrepancies (97.8%) and the lowest false-positive rate (0.6%). Gemini 3.0 Pro achieved the highest educational feedback score (4.60 ± 0.65), followed by GPT-5.3 (4.41 ± 0.68) and Claude 4.6 Sonnet (3.95 ± 0.80; p < 0.001).
Conclusion:
Under a single structured prompt, LLMs showed model-dependent performance in the text-based comparison of Turkish preliminary and final abdominal radiology reports. These single-center findings do not establish image-based diagnostic accuracy or readiness for autonomous clinical use and require prospective multicenter validation.