Related Experiment Videos
When are AI measures of caregiver sensitivity useful? Moving beyond accuracy
Anna Madden-Rusnak1, Priyanka Khante2, Kaya de Barbaro3
1Department of Women's Health, Dell Medical School at the University of Texas at Austin, Austin, TX 78712, United States.

Abstract:
AI is a promising tool for automatically classifying caregiver sensitivity-a central predictor of socioemotional development that is traditionally labor-intensive to measure and difficult to scale in naturalistic settings. We systematically evaluated our previously published audio-based AI classifier of caregiver sensitivity to infant distress by directly comparing model classifications with human annotations and evaluating performance across conditions relevant to real-world research use. Data included 387 infant distress events from 32 mother-infant dyads captured using daylong home audio. Dyads contributed a mean of 12.1 episodes; median episode duration was 3.53 min (range: 1.01-36.86). Infants averaged 4.25 ± 2.26 months of age, and 59.4% were female. AI-derived caregiver-level sensitivity showed moderate correspondence with human annotations (Spearman's ρ =.52, p = .002), although episode-level accuracy varied. Accuracy was higher for shorter episodes (≤3.5 min) and episodes with greater human-coded sensitivity, but lower for episodes containing crying versus fussing alone. Distress density did not predict performance. At the caregiver level, higher average sensitivity predicted greater odds of correct episode-level classification, whereas within-caregiver variability did not. Our in-depth evaluation suggest that AI-based classifications may capture meaningful variation in caregiver sensitivity at both the event and person level, while also identifying systematic patterns of error that highlight opportunities for algorithmic refinement. Rather than replacing observational approaches, audio-based AI measures may complement established methods and extend assessement to larger-scale naturalistic research. More broadly, this work provides a framework for evaluating the use cases in which automated assessment are most informative and accurate.
Related Concept Videos
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:15
Receiver Operating Characteristic Plot
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5% chance...
 01:52
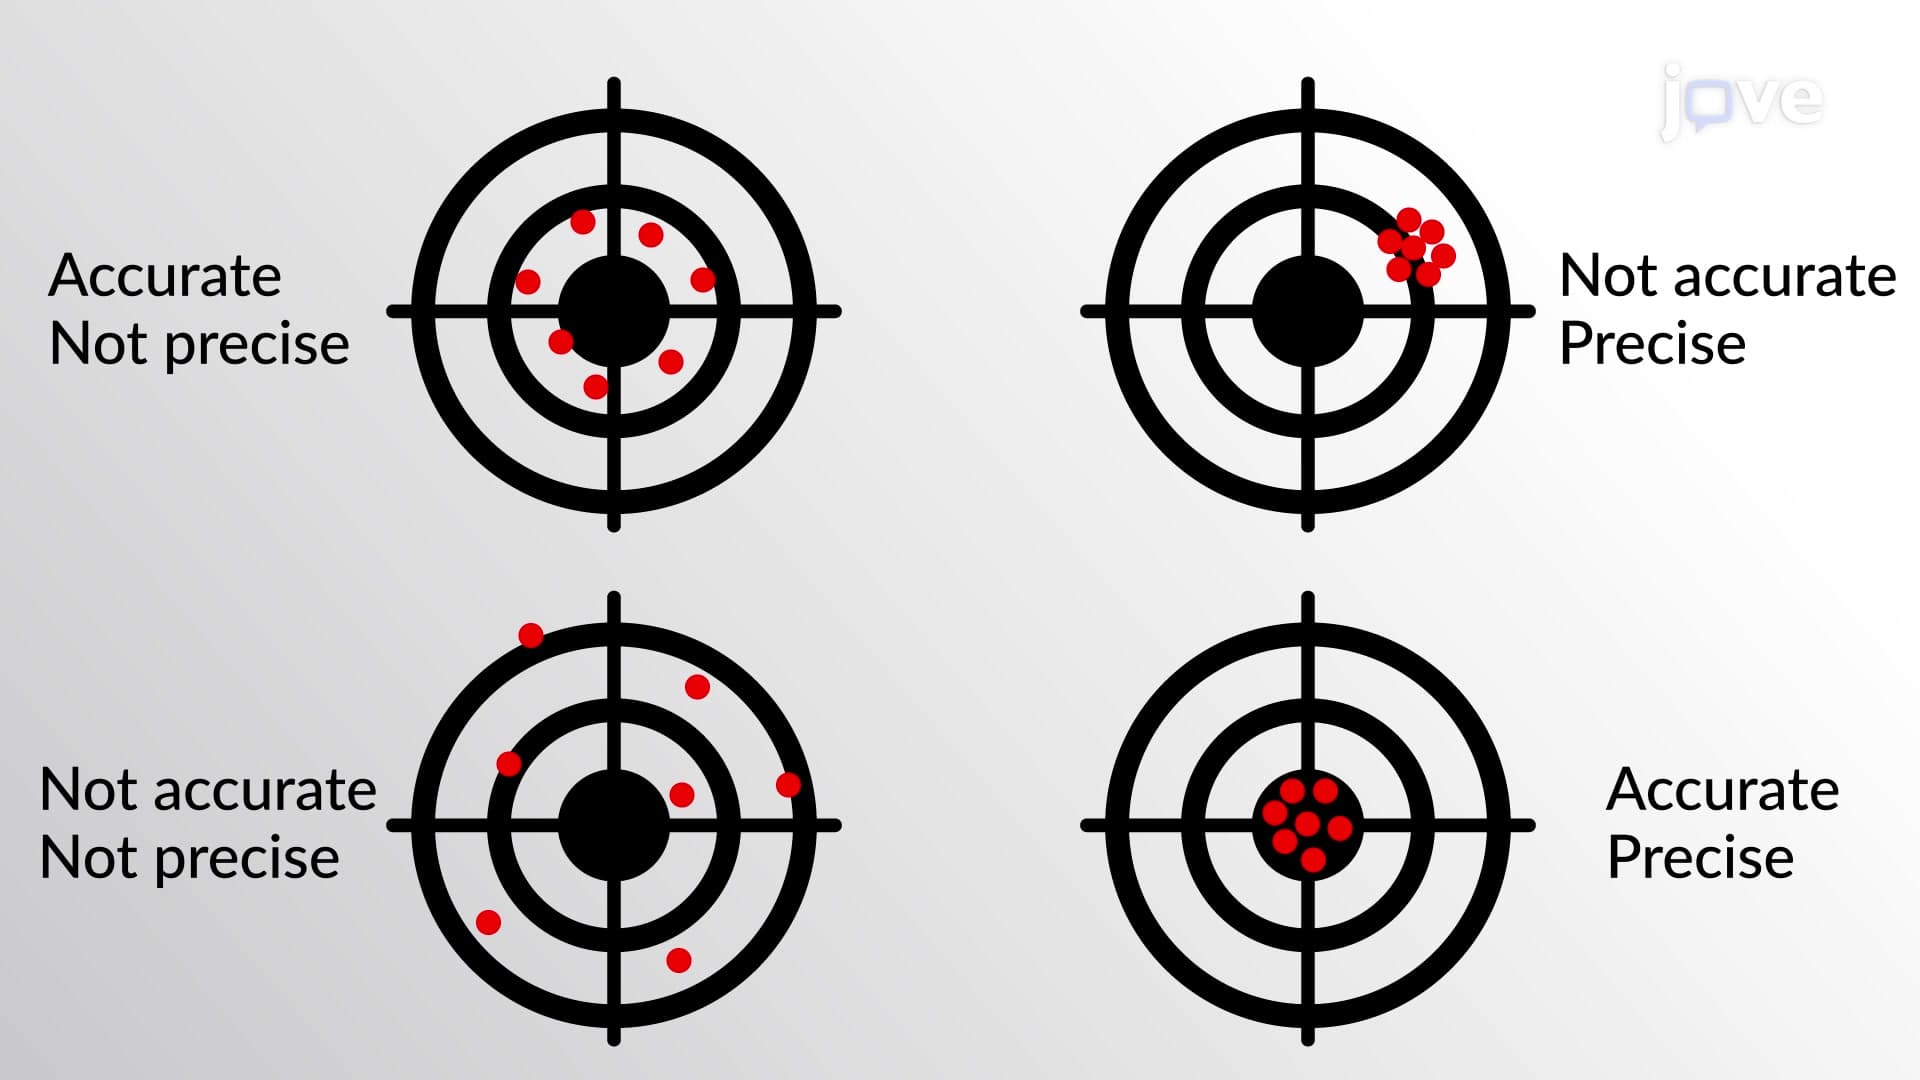
Accuracy and Precision