Related Experiment Video
Updated: Sep 30, 2026
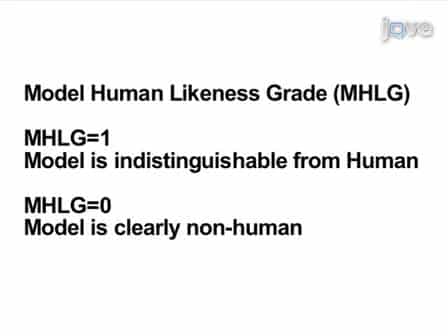

One Dimensional Turing-Like Handshake Test for Motor Intelligence
Published on: December 15, 2010
On Benchmarking Human-like Intelligence in Machines
Lance Ying1,2, Katherine M Collins3, Lionel Wong2
1Department of Psychology, Harvard University, Cambridge, MA, USA.

Abstract:
Recent advances in Artificial Intelligence (AI) have yielded powerful computational models that, by learning from vast amounts of human-generated data, are increasingly posited as approximate models of human cognition. However, we argue that many current evaluation paradigms for AI are insufficient for assessing human-like cognitive capabilities in these models. We identify a set of key shortcomings: a lack of human-validated labels, inadequate representation of human response variability and uncertainty, and reliance on simplified and ecologically invalid tasks. We support our claims by conducting a human evaluation study on nine existing AI benchmarks, suggesting major limitations in task and label designs. To address these limitations, we propose five concrete recommendations for future AI evaluation efforts that will enable more rigorous and meaningful understanding of human-like cognitive capacities in AI models.
Related Concept Videos
 01:29
Measures of Intelligence
Validity refers to how well a test measures what it claims to measure. An intelligence test should accurately assess intelligence rather than another characteristic, like anxiety. Criterion validity is one way to evaluate this; it...
 01:23
Binet's Contribution to Measures of Intelligence
 01:30
Machines: Problem Solving II
 01:22
Machines: Problem Solving I
The toggle clamp system is a machine structure consisting of movable, pin-connected multi-force members that form a stabilized system to transmit forces. The...
 01:27
Intelligence
 01:20
Introduction to Cognitive Psychology
This field emerged in the mid-20th century, following a period dominated by behaviorism, which...