Related Experiment Video
Updated: Oct 1, 2026
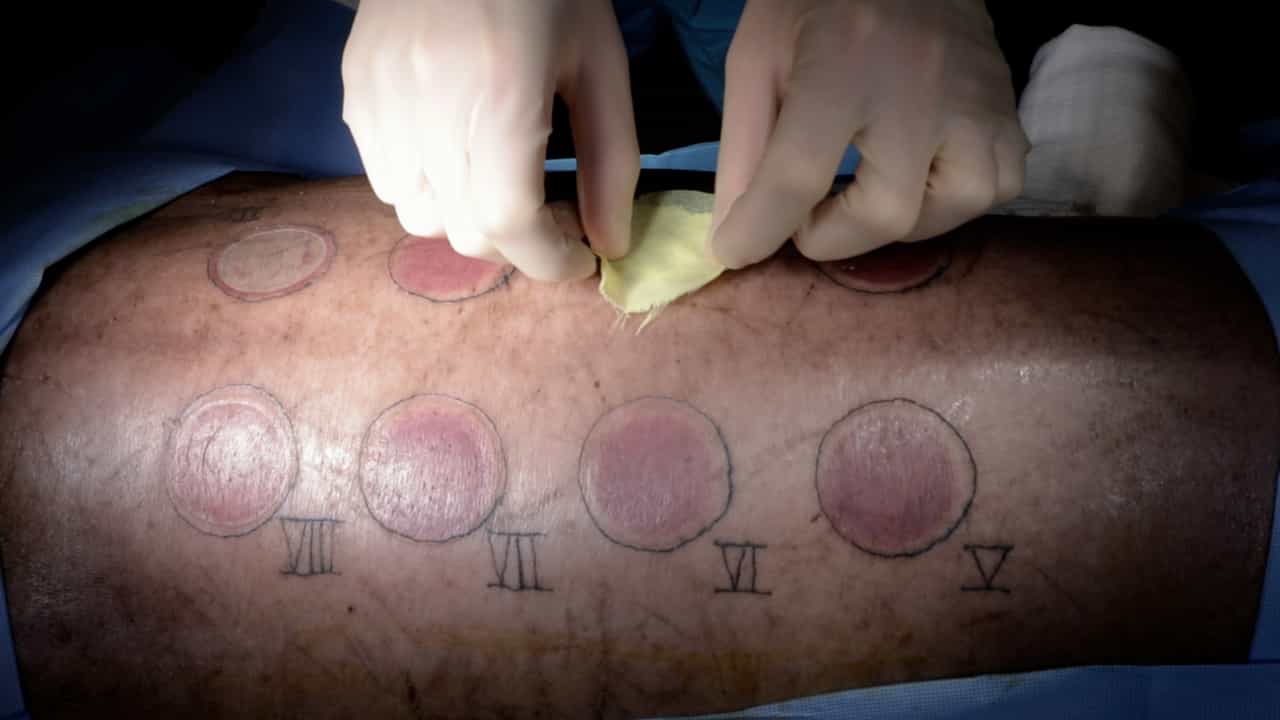

A Swine Burn Model for Investigating the Healing Process in Multiple Depth Burn Wounds
Published on: February 23, 2024
[Application effect of LLMs as decision-support tools in emergency burn treatment]
M T Yan1, J T Wei2, S Y Jiang2
1Department of Nursing, the Second Affiliated Hospital of Zhejiang University School of Medicine, Hangzhou 310009, China.

Abstract:
Objective: To explore the application effect of large language models (LLMs) as decision-support tools in emergency burn treatment. Methods: This study was a cross-sectional study. A total of 100 burn patients meeting the inclusion criteria were admitted to the Department of Emergency Medicine of the Second Affiliated Hospital of Zhejiang University School of Medicine between September 2025 and April 2026, including 52 males and 48 females, aged 34.5 (25.0, 56.8) years. Based on patients' discharge summaries, the diagnoses and treatment plans reviewed and confirmed by an expert panel, consisting of two emergency medicine physicians with associate senior titles and one burn and wound-repair specialist with a senior title from the hospital, were taken as the gold standard. Based on the gold standard and in a blind manner, two burn and wound-repair physicians with more than 5 years of working experience in the hospital used the Likert scale to evaluate the diagnostic accuracy and rationality of treatment plans, which were generated during May 25-28, 2026 for the aforementioned 100 patients by 4 LLMs (ChatGPT-5.5, Doubao-2.0-Pro, Qwen-3.6-Max-Preview, and Gemini 3.5 Flash) as well as 10 emergency medicine department junior physicians (EDJPs). The percentage of diagnostic accuracy scores and treatment plan rationality scores for the 100 patients were compared among EDJPs and the four LLMs; the percentage of diagnostic accuracy scores across patients with varying burn severities were also compared among EDJPs and the four LLMs; the consistency of diagnostic accuracy scores and treatment plan rationality scores were compared between the two evaluators. Results: The percentages of diagnostic accuracy scores for the 100 patients by Doubao-2.0-Pro, Gemini 3.5 Flash, ChatGPT-5.5, and Qwen-3.6-Max-Preview were 100% (100%, 100%), 100% (100%, 100%), 100% (50%, 100%), and 100% (50%, 100%), respectively, which were all significantly higher than the 100% (50%, 100%) by EDJPs (P<0.05). The treatment plan rationality scores for the 100 patients by Doubao-2.0-Pro, ChatGPT-5.5, and Gemini 3.5 Flash were 4.0 (4.0, 4.0), 4.0 (4.0, 4.0), and 4.0 (4.0, 4.0), respectively, which were all significantly higher than the 4.0 (3.0, 4.0) by EDJPs (P<0.05). The treatment plan rationality scores for the 100 patients by Doubao-2.0-Pro and ChatGPT-5.5 were significantly higher than the 4.0 (3.0, 4.0) by Qwen-3.6-Max-Preview (P<0.05). The percentages of diagnostic accuracy scores for patients with mild burns by Doubao-2.0-Pro, Gemini 3.5 Flash, and ChatGPT-5.5 were significantly higher than that by EDJPs (P<0.05); the percentages of diagnostic accuracy scores for patients with moderate burns by Doubao-2.0-Pro, Qwen-3.6-Max-Preview, and Gemini 3.5 Flash were significantly higher than that by EDJPs (P<0.05); the differences in percentages of diagnostic accuracy scores were not statistically significant among EDJPs and the four LLMs for patients with severe and extremely severe burns (P>0.05). Good consistency was observed for diagnostic accuracy scores between the two evaluators (with an interclass correlation coefficient of 0.821, with a 95% CI of 0.746-0.876), and moderate consistency was noted for treatment plan rationality scores (with an interclass correlation coefficient of 0.650, with a 95% CI of 0.522-0.749). Conclusions: Doubao-2.0-Pro, ChatGPT-5.5, and Gemini 3.5 Flash matched or even surpassed EDJPs in terms of diagnostic accuracy and treatment plan rationality for emergency burn patients, showing preliminary potential to serve as tools for second clinical opinions in burn care.
