Related Experiment Videos
Online Policy-Wise State Abstraction for Reinforcement Learning Agents Leveraging Free Energy

Abstract:
Constructing compact, informative state representations from high-dimensional observations is a key challenge in reinforcement learning (RL). Directly mapping often introduces irrelevant or redundant dimensions in the state space. This causes the curse of dimensionality and increases regret, particularly during early learning. To address this challenge, we propose a dynamic, online, policy-wise state abstraction framework that constructs compact, task-relevant state representations (state abstraction candidates) during learning without prior knowledge. Our method uses parallel learners with a shared replay buffer to mitigate the potential adverse impact of abstraction on regret. One learner operates on the full state. Additional learners independently apply adaptive binary masking to dynamically select relevant state dimensions based on importance scores. At each decision step, a free energy-based metric is used to select the optimal learner for action selection. Experimental results demonstrate that our method achieves superior performance across diverse RL benchmarks, yielding lower regret and higher reward, particularly under limited learning budgets.
Related Concept Videos
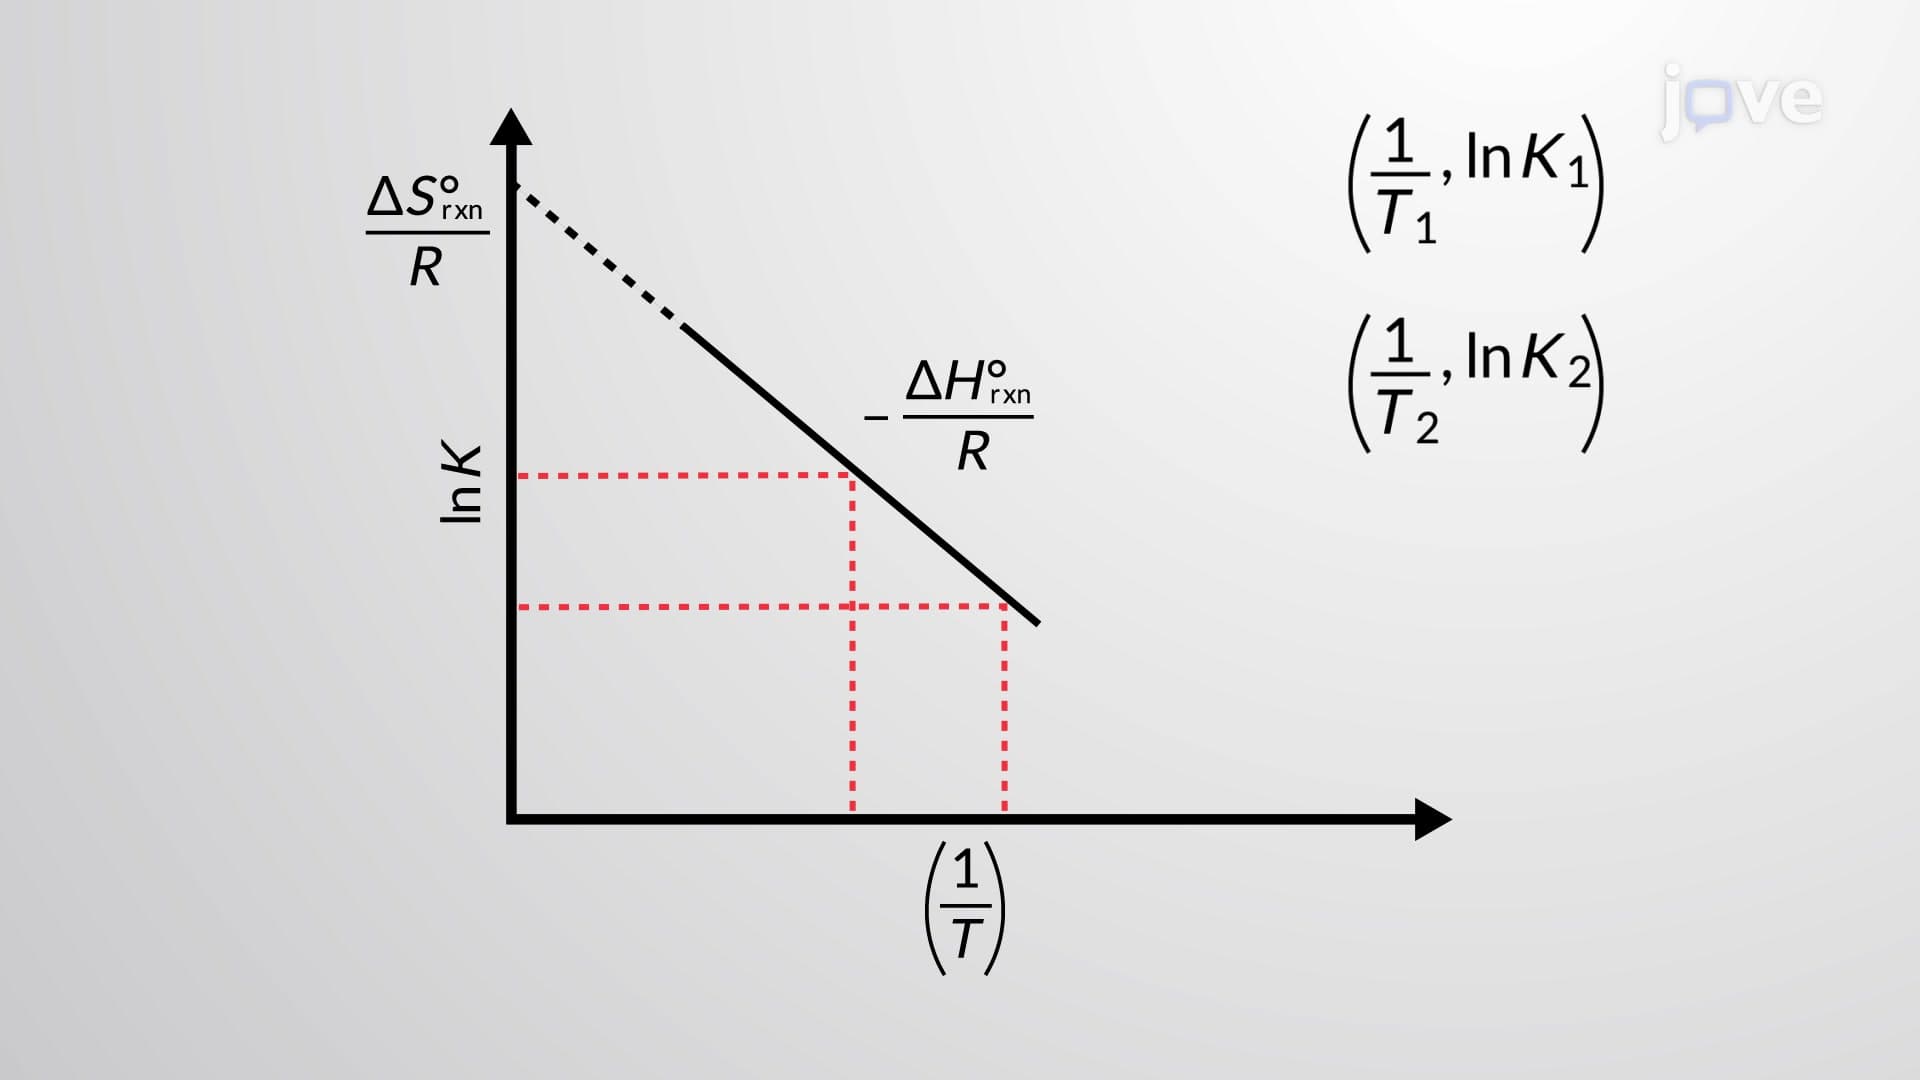 02:56
Free Energy and Equilibrium
Recall that Q is the numerical value of the mass action expression...
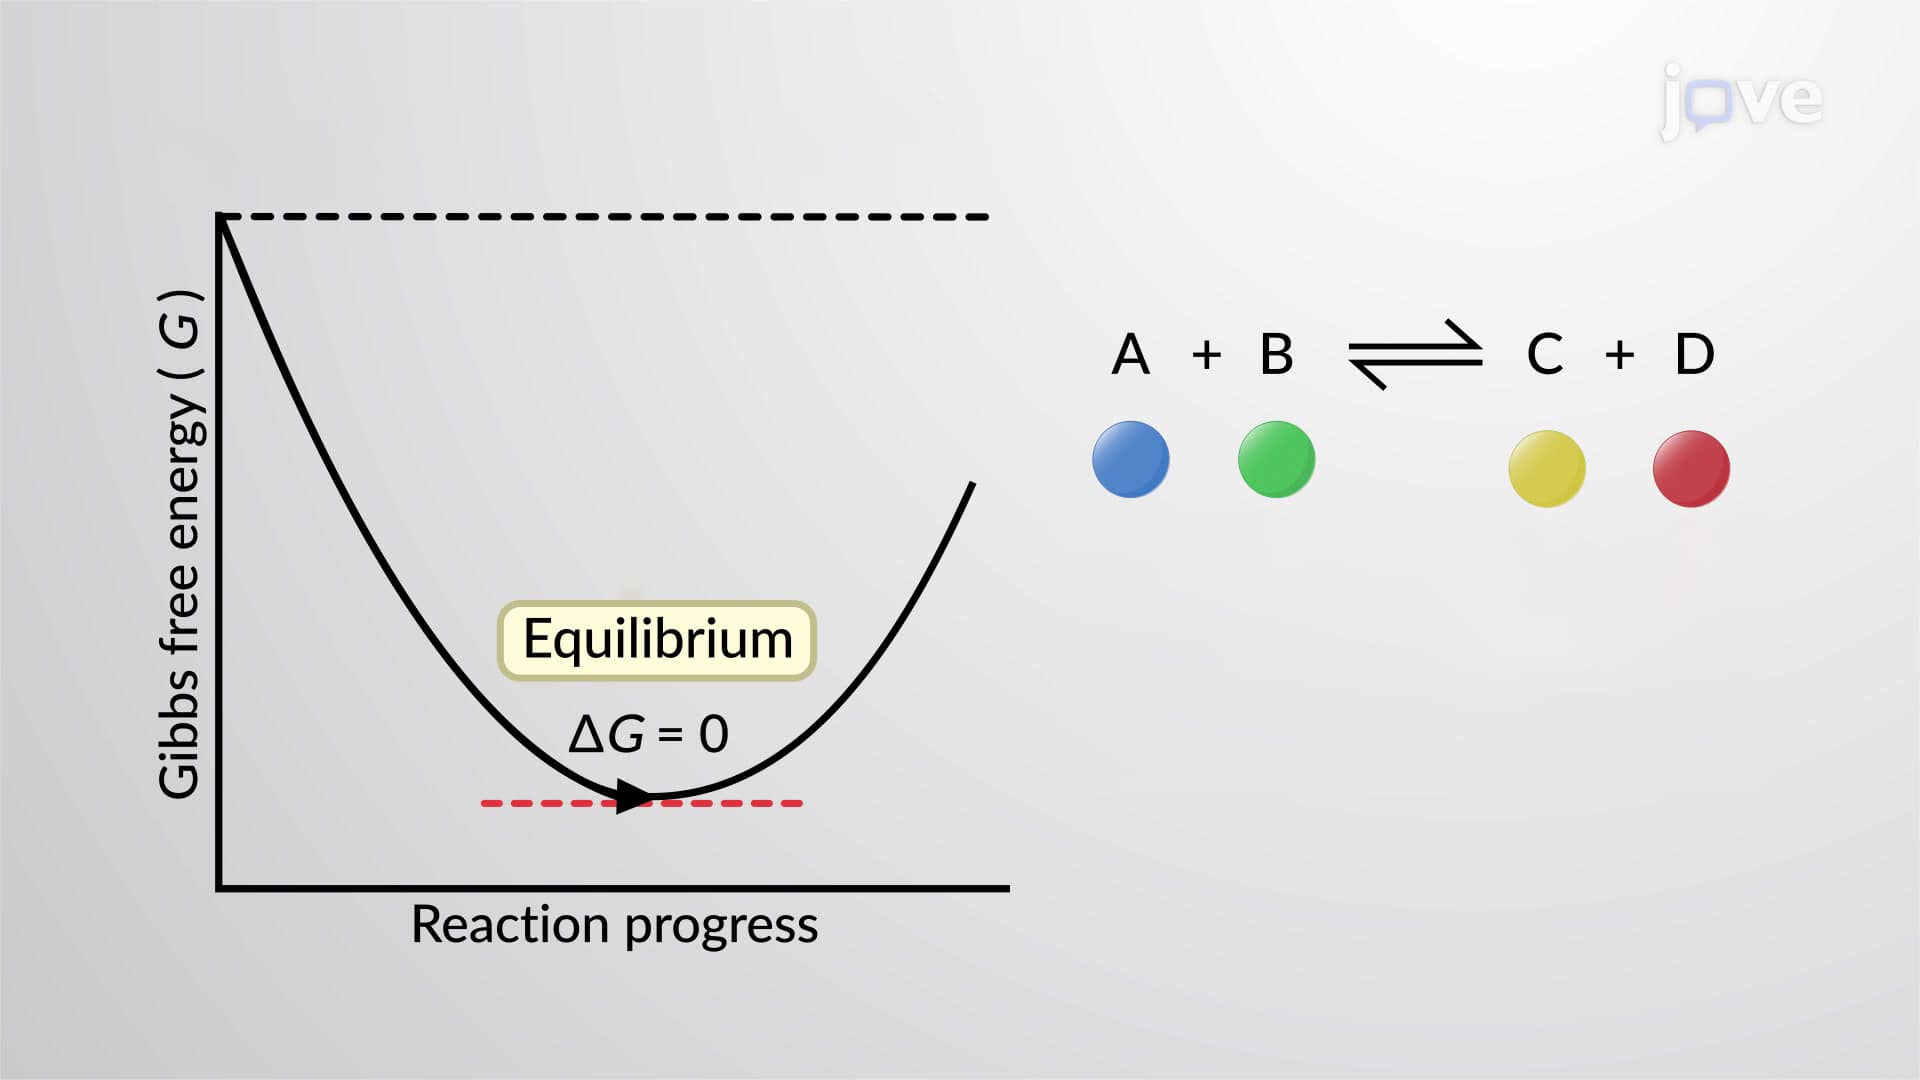 00:55
Free Energy and Equilibrium
The reaction quotient, Q, is a convenient measure of the status of an...
 03:25
Free Energy Changes for Nonstandard States
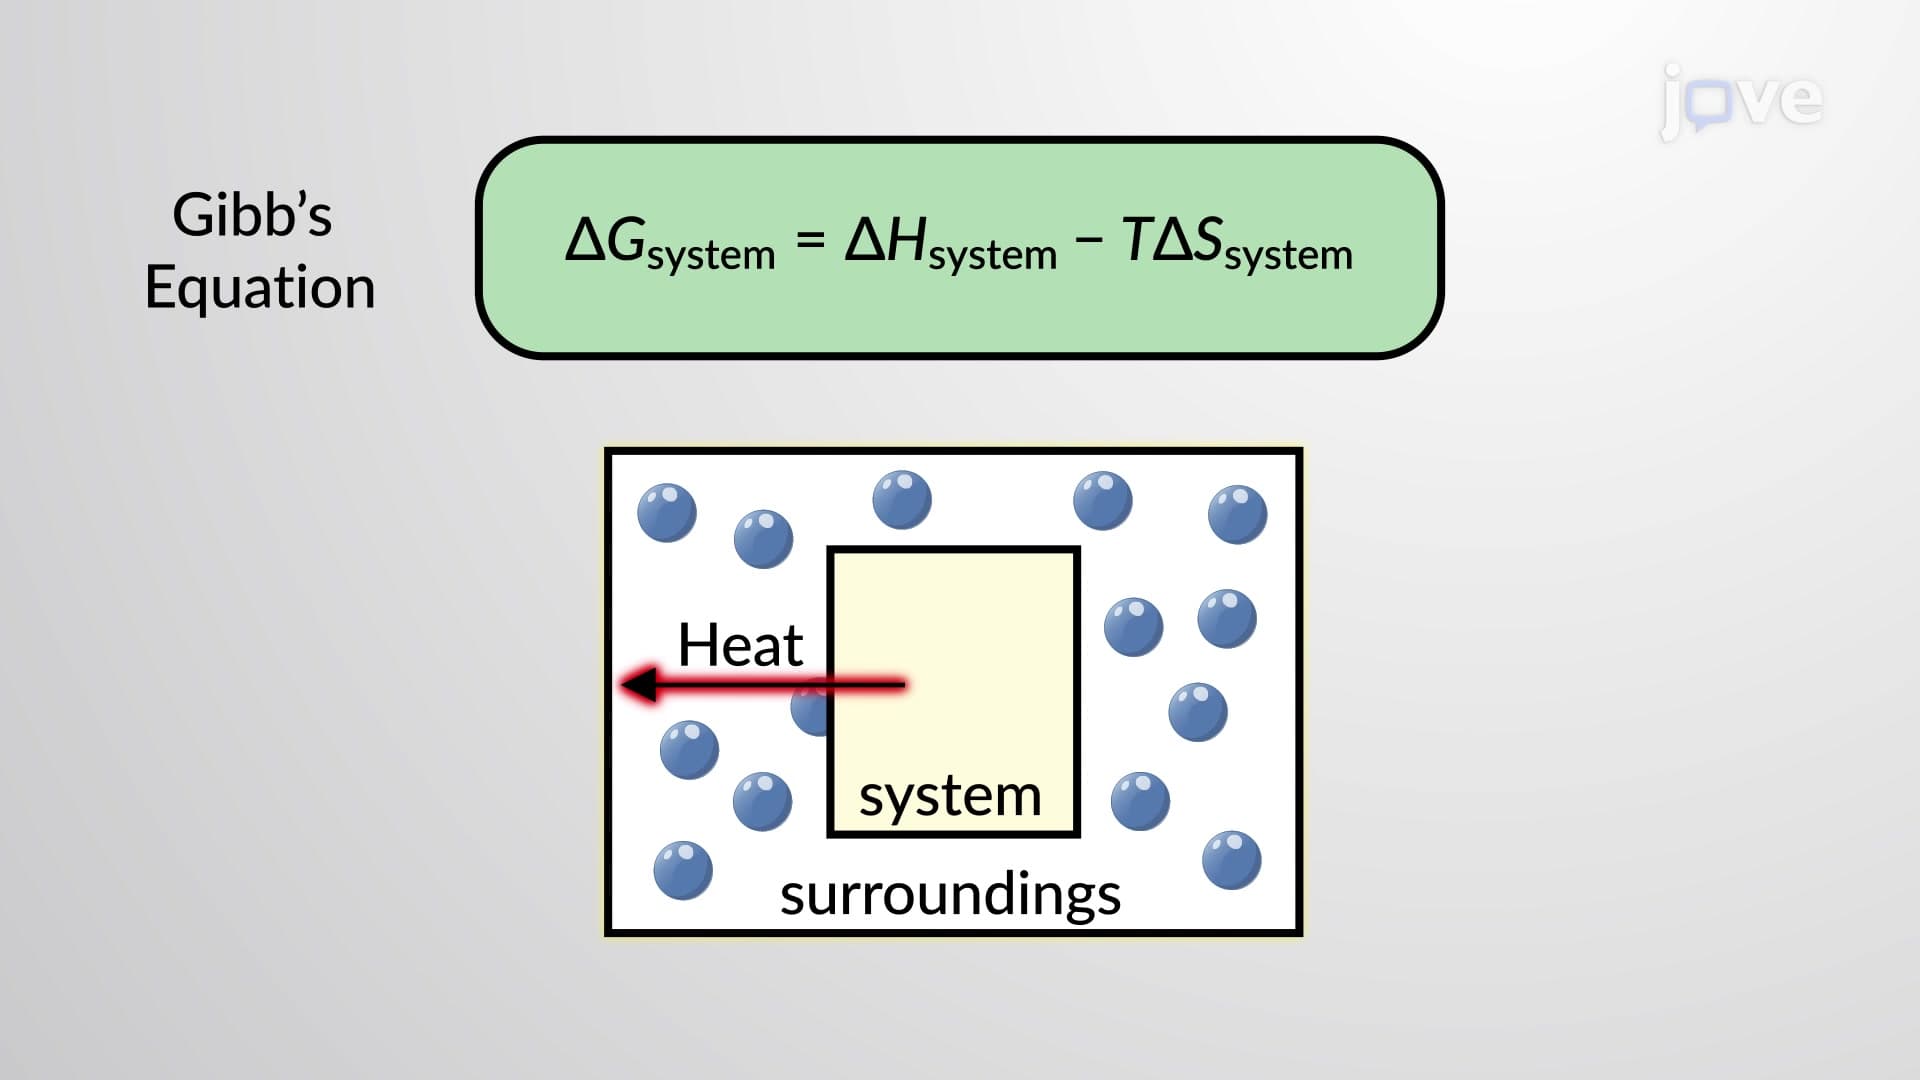 01:05
An Introduction to Free Energy
 01:12
Observational Learning
 01:16
Potential-Energy Criterion for Equilibrium