Related Experiment Video
Updated: Oct 3, 2026
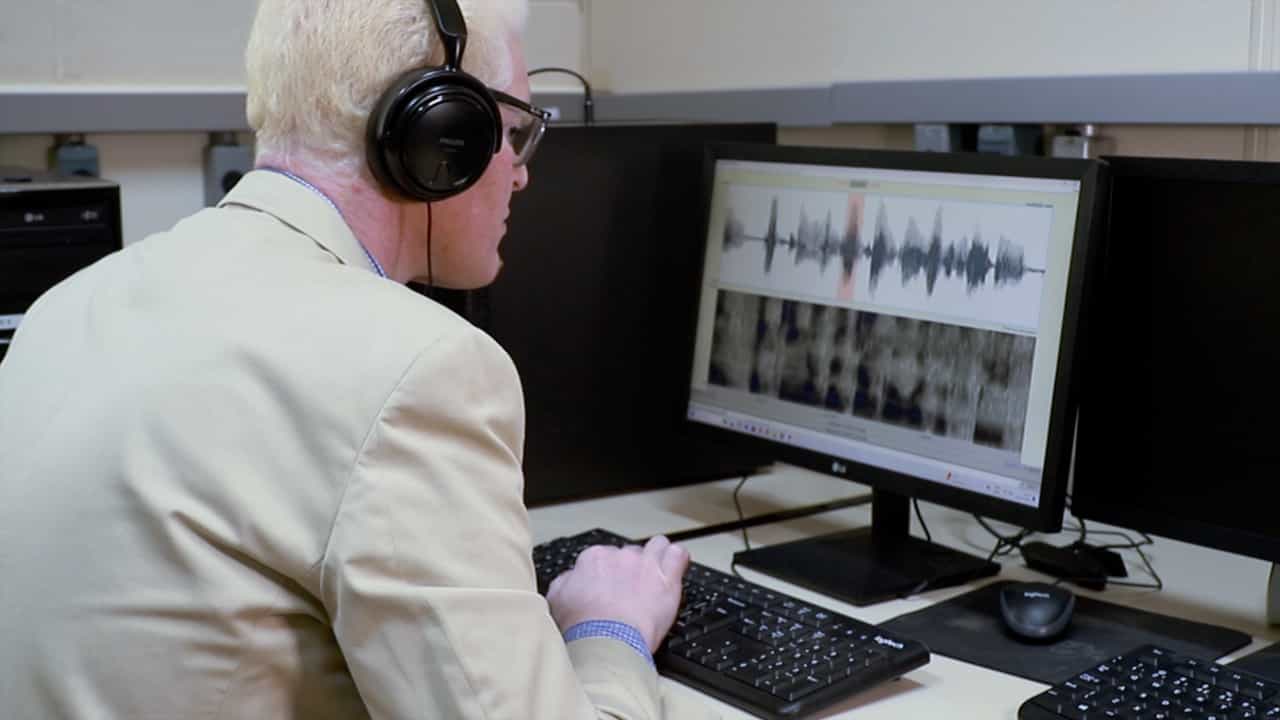

Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
AudioHate-DB: An audio dataset for English hate speech detection in Bengali accent
Arif Faisal1, Syeda Sumaia Sultana1, Suprove Chandra Sarkar1
1Department of Software Engineering, Daffodil International University, Dhaka, 1216, Bangladesh.

Abstract:
Hate speech detection has gained significant attention in recent years due to the rapid increase in offensive and harmful content across social media and other digital platforms. Although there are many resources for written hate speech and for accented native English, there are few resources for offensive English speech in South Asian accents, which hinders the development of accent-aware hate speech detection and speech recognition systems. To address this need, the following paper introduces a speech dataset for hate speech detection in spoken English with a Bangladeshi accent, in which slurs, gendered epithets, and general profanity are mixed with otherwise neutral English speech, which is prevalent in Bangladesh and South Asia. This dataset contains 3018 audio samples with a controlled sentence inventory of 1006 sentences (505 hate-class, 501 non-hate-class). Every hateful class sentence has at least one word from a set of 23 hateful terms divided into six semantic categories: racial slurs, gendered/sexual slurs, ability derogatory terms, LGBTQ+ slurs, profanity, and compound/contextual words. Audio samples were collected on mobile telephones using a 44,100 Hz, 16-bit depth format and by multi-regional, multi-gender speakers in natural indoor and outdoor settings and were recorded for two balanced classes. Both raw and noise-cancelled processed versions are offered, where the class name is represented by the directory structure. Baseline experiments using Logistic Regression, Random Forest, Gradient Boosting, and LSTM demonstrate the dataset's effectiveness, with LSTM achieving the highest accuracy of 83.94%. The dataset can support research on spoken hate speech detection, accent-aware speech recognition, and audio content moderation.
Related Concept Videos
 01:31
Hearing
 01:15
Auditory Pathway
When viewed cross-sectionally, the cochlea reveals the scala vestibuli and scala tympani flanking the...
 01:02
Sample Handling
Samples should be transported carefully from collection points to the laboratory. They should be properly sealed and clearly labeled to prevent cross-contamination. To preserve the sample integrity, optimal temperature conditions during transport are essential. This could involve using...
 01:09
Censoring Survival Data
 02:35
RACE - Rapid Amplification of cDNA Ends
Since the...
 00:58
Sound Intensity