Related Experiment Video
Updated: Oct 9, 2026
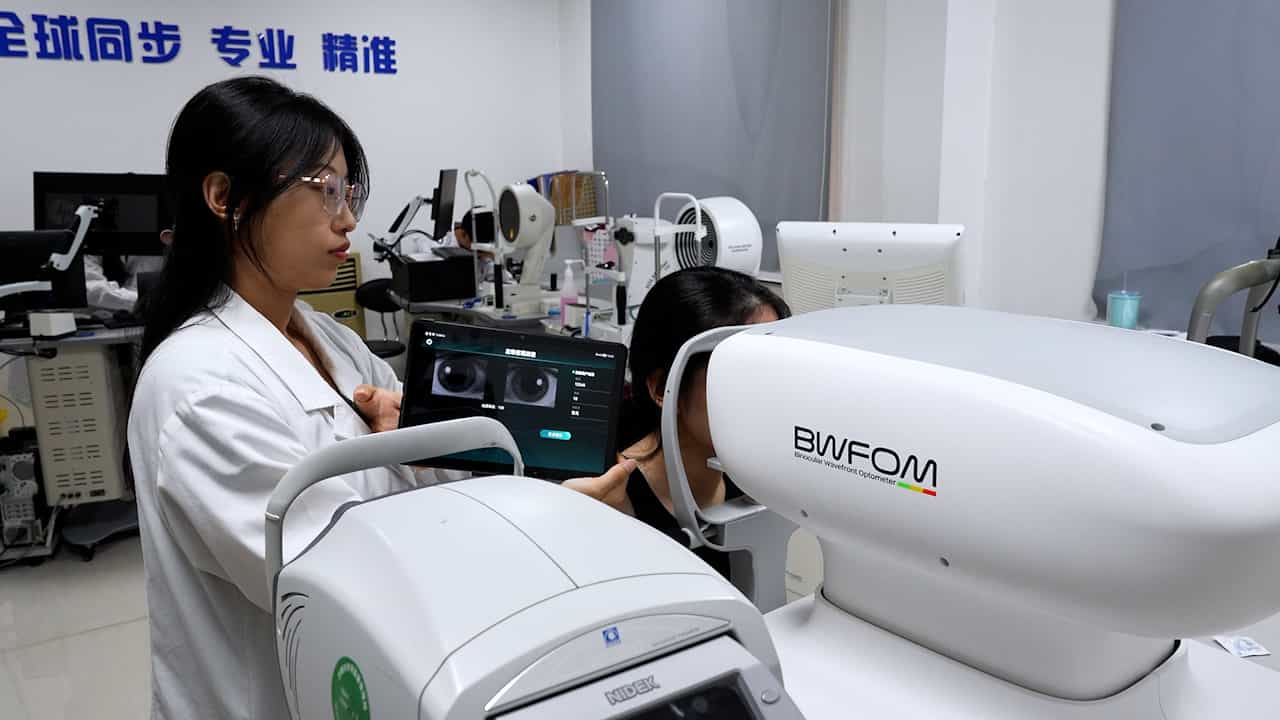

Comparison of Agreement and Accuracy using Binocular Wavefront Optometer with Autorefractor and Phoropter
Published on: September 16, 2025
Large Language Models for Selecting Intraocular Lens Power Calculation Formulas: A Comparative Study
Hao Chen1, Mingyu Qin1, Ruiling Zhu1
1Department of Ophthalmology, Shanghai Sixth People's Hospital Affiliated to Shanghai Jiao Tong University School of Medicine, Shanghai, China.

Purpose:
To evaluate refractive outcomes of large language model (LLM)-based selection of the optimal intraocular lens power calculator according to individual biometric parameters.
Methods:
Two hundred eight eyes undergoing routine cataract surgery were included. Ten leading LLMs (Gemini, Chat-GPT, Perplexity, Grok, DeepSeek, Kimi, Qwen, Doubao, ERNIE, and Hunyuan) were prompted to recommend "the single most appropriate formula" from Barrett Universal II (BUII), Cooke K6, EVO 2.0, Hill-RBF 3.0, Kane, and PEARL-DGS, based on axial length (AL), keratometry, anterior chamber depth, and lens thickness. Gemini was excluded because it consistently selected Kane. Precision (SD) and accuracy (absolute spherical equivalent prediction error [SEQ-PE]) were assessed with the Eyetemis Analysis Tool and compared with BUII and SRK/T, both overall and within AL subgroups.
Results:
Formula preferences varied markedly among LLMs. Overall, all LLMs and BUII demonstrated significantly greater precision than SRK/T, with Hunyuan, ChatGPT, and BUII showing highest precision and significantly improved accuracy compared to SRK/T (all P < .05). The leading percentages of eyes within the ±0.50 diopter (D) threshold were achieved by Perplexity (82.69%), ChatGPT (82.21%), Qwen (82.21%), and BUII (81.73%). Across AL subgroups, at least one LLM numerically outperformed BUII in both precision and accuracy; at the ±0.50 D threshold, certain models increased this percentage over BUII by approximately 3% when AL was ≤ 22 mm or ≥ 26 mm, and by 8% when 24.5 mm ≤ AL < 26 mm.
Conclusions:
Compared with BUII, current LLMs exhibit limited capacity to improve refractive outcomes by selecting the optimal formulas for routine practice; however, certain LLMs show promise as adjunctive tools for personalized selection tailored to specific ALs.
