Related Experiment Video
Updated: Oct 9, 2026

Frame-by-Frame Video Analysis of Idiosyncratic Reach-to-Grasp Movements in Humans
Published on: January 15, 2018
Zero-Shot Video Translation and Editing With Frame Spatial-Temporal Correspondence

Abstract:
The remarkable success in text-to-image diffusion models has motivated extensive investigation of their potential for video applications. Zero-shot techniques aim to adapt image diffusion models for videos without requiring further model training. Recent methods largely emphasize integrating inter-frame correspondence into attention mechanisms. However, the soft constraint applied to identify the valid features to attend is insufficient, which could lead to temporal inconsistency. In this paper, we present FRESCO, which integrates intra-frame correspondence with inter-frame correspondence to formulate a more robust spatial-temporal constraint. This enhancement ensures a consistent transformation of semantically similar content between frames. Our method goes beyond attention guidance to explicitly optimize features, achieving high spatial-temporal consistency with the input video, significantly enhancing the visual coherence of manipulated videos. We verify FRESCO adaptations on two zero-shot tasks of video-to-video translation and text-guided video editing. Comprehensive experiments demonstrate the effectiveness of our framework in generating high-quality, coherent videos, highlighting a significant advance over current zero-shot methods.
Related Concept Videos
 01:25
Relative Motion Analysis using Rotating Axes
However, to express the relative position of point B relative to point A, an additional frame of reference, denoted as x'y', is necessary. This additional frame not only translates but also rotates relative to the fixed frame, making it instrumental in...
 01:03
Inertial Frames of Reference
 01:27
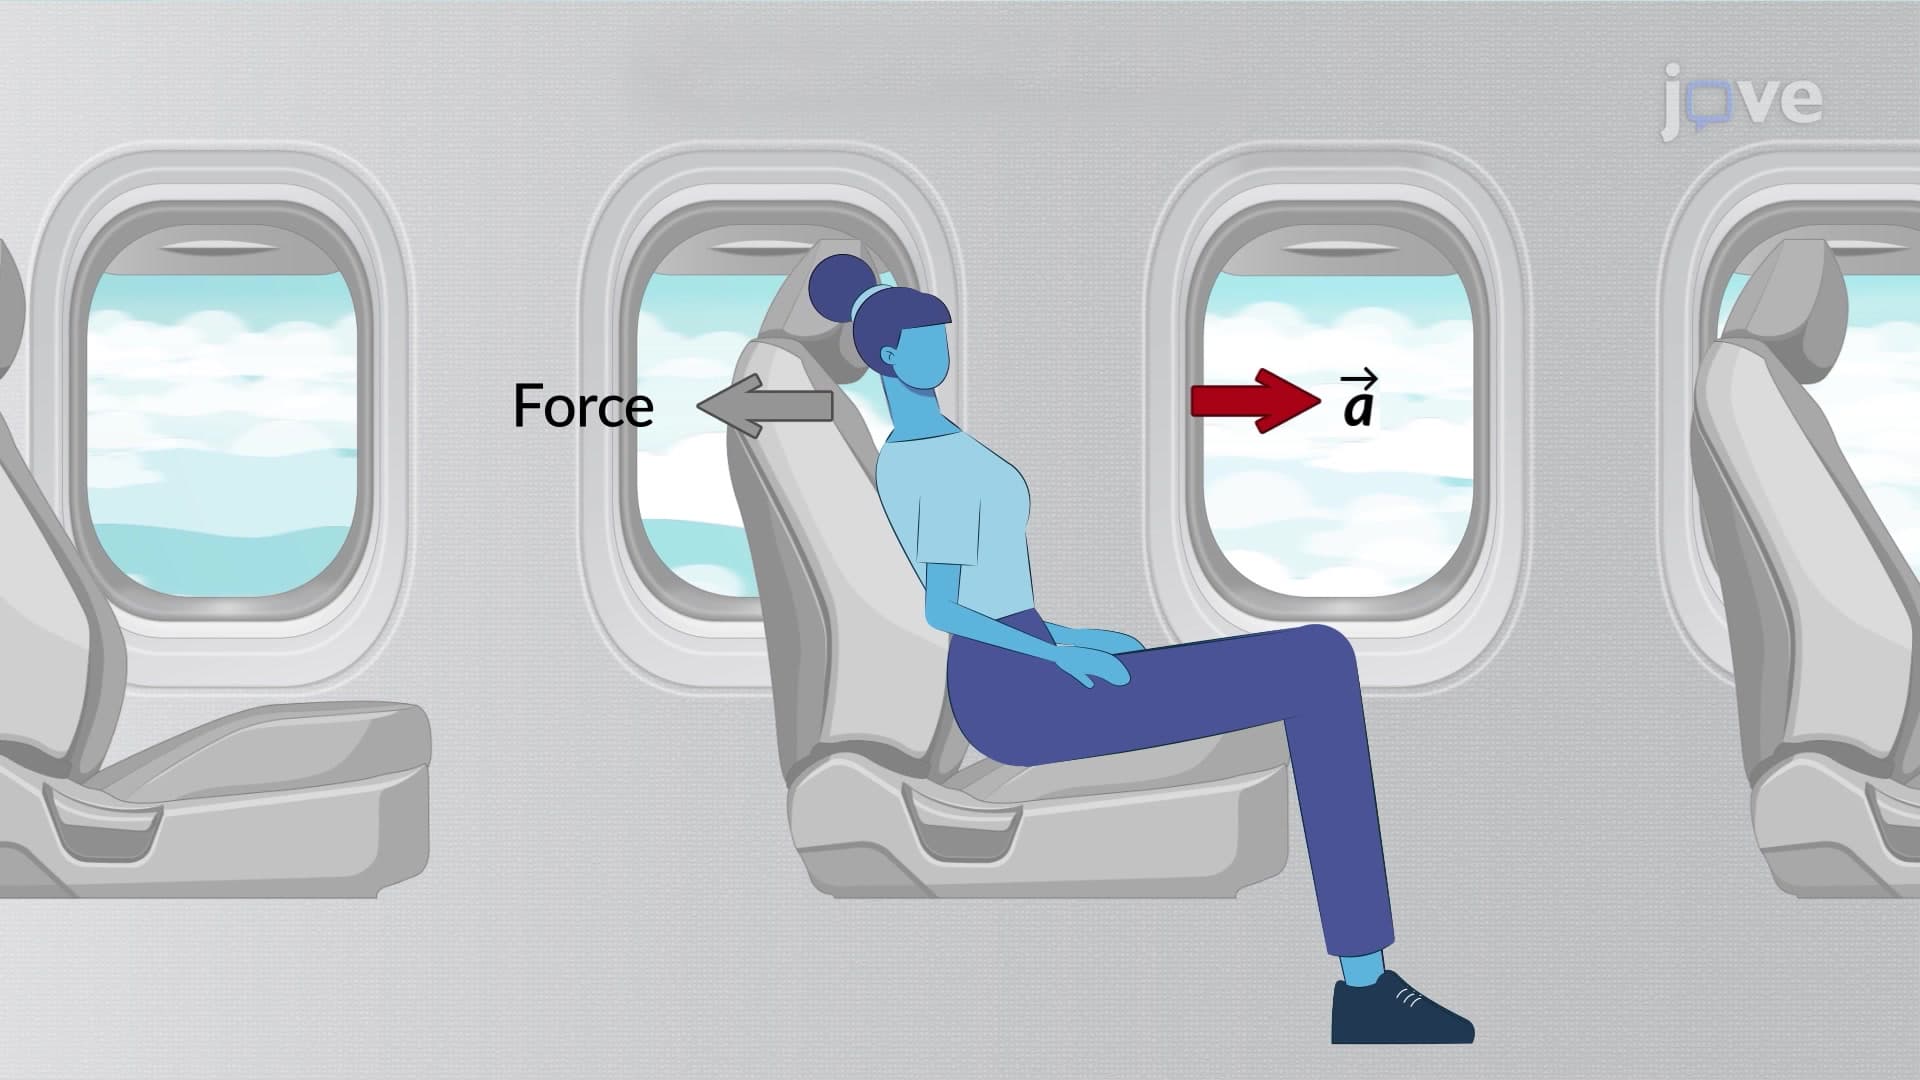
Non-inertial Frames of Reference
 01:31
Position and Displacement
01:31Position and Displacement
 01:00
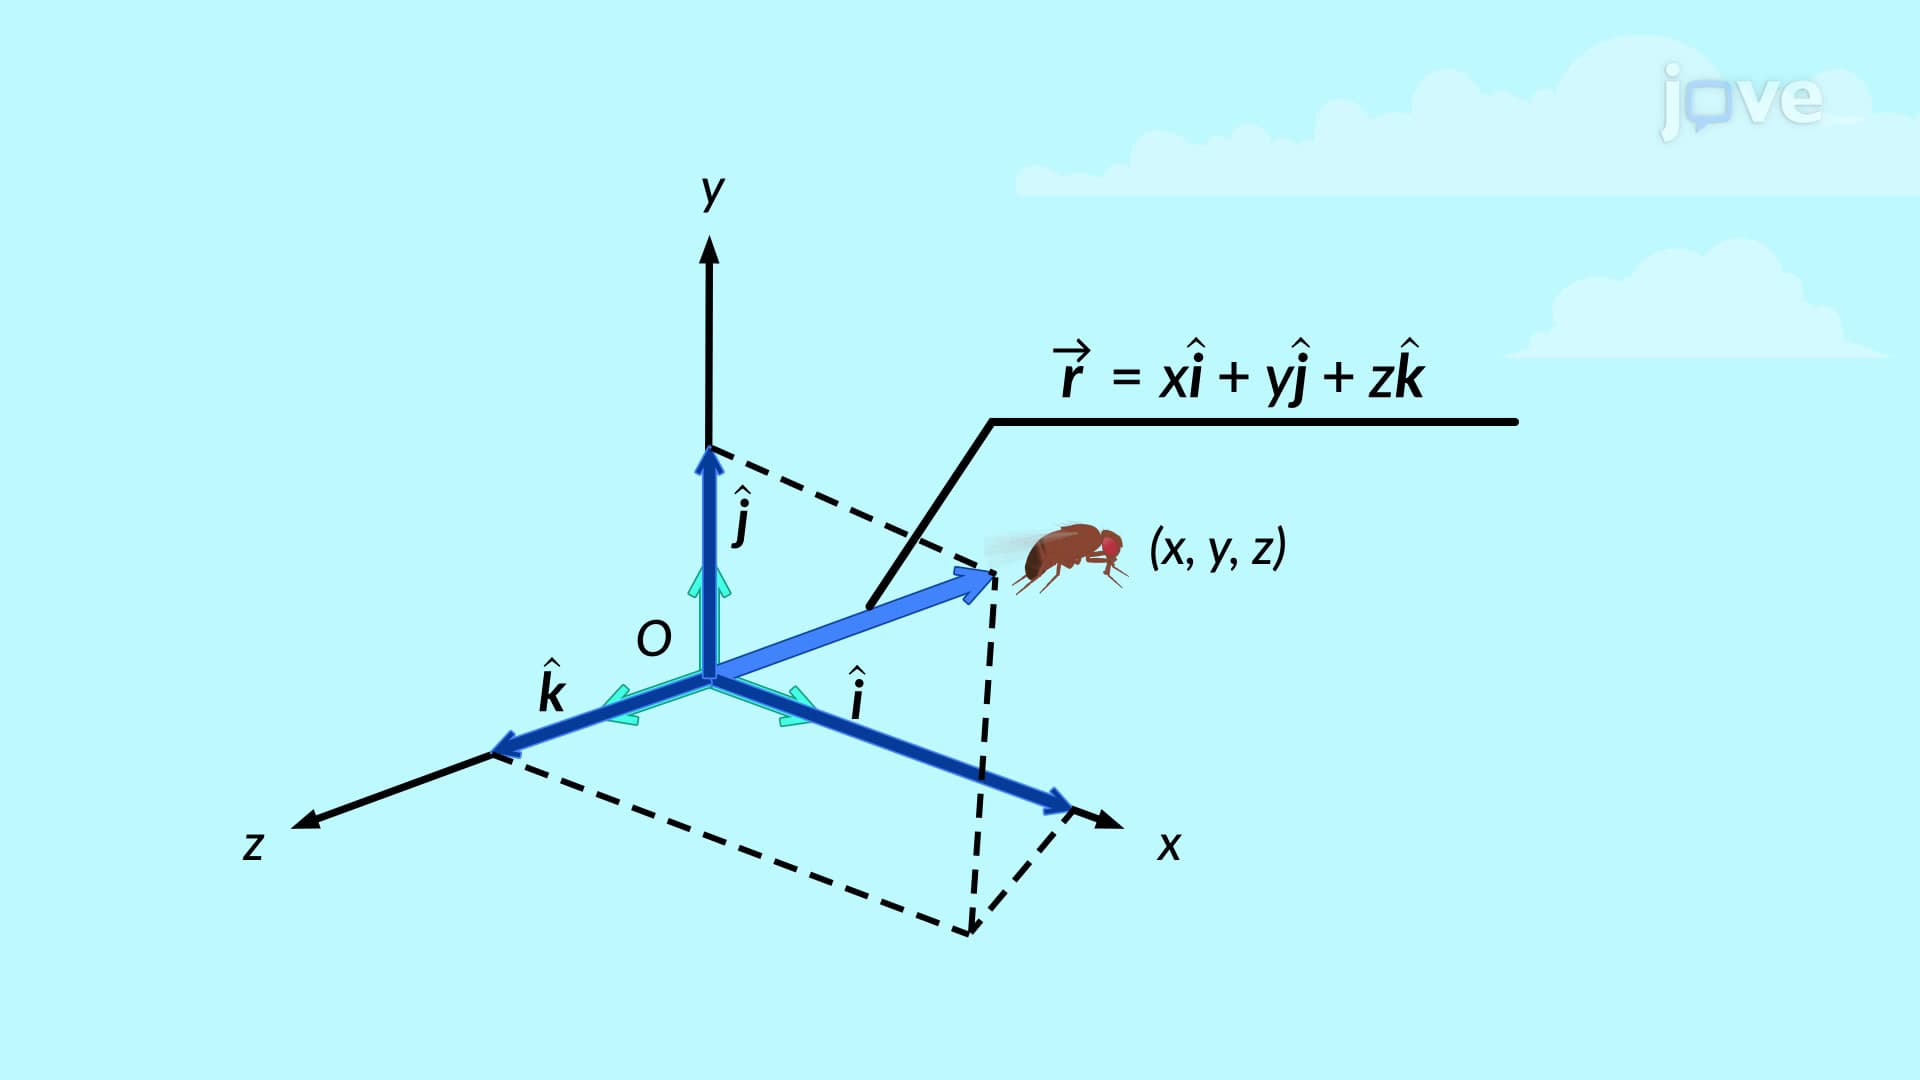
Position and Displacement Vectors
Further, several important kinds of...