Related Experiment Videos
Accurate stock movement prediction via centroid-based randomness smoothing
Yejun Soun1, Hosung Lee1, U Kang1
1Department of Computer Science and Engineering, Seoul National University, Seoul, Republic of Korea.

Abstract:
How can we identify stable patterns to accurately predict stock price movements amidst severe market noise? Predicting stock price movements is a crucial problem in financial data mining, and has attracted significant attention from researchers and financial institutions. Although there have been several works on learning patterns from quantitative data to predict stock prices, they encounter critical challenges from data uncertainty and model limitations. Data uncertainty arises in financial data because asset prices are determined by the market. Different participants hold distinct valuations for the same asset, which causes prices to fluctuate. This inherent randomness makes it difficult to identify consistent patterns in the data. Additionally, because of this inherent randomness, existing stock movement prediction models that repeatedly stack more recurrent layers end up propagating the randomness forward. It thus becomes more difficult to capture the complex patterns of stock prices. In this work, we propose Craft (Centroid-based Randomness Smoothing Approach for Stock Forecasting with Transformer Architecture), an accurate stock movement prediction model designed to extract clear patterns in stock data and perform refined forecasting through a Transformer-based architecture. By applying an effective randomness smoothing process, Craft uncovers meaningful and consistent patterns that facilitate accurate predictions. We evaluate Craft on fourteen test settings spanning six real-world datasets and three market regimes. Craft achieves the highest prediction accuracy in twelve of these settings and ranks the second in the other two. Craft also improves the annualized Sharpe ratio by up to 1.0 while reducing the relative maximum drawdown by up to 7.0% points over the best competitor.
Related Concept Videos
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
The...
 01:16
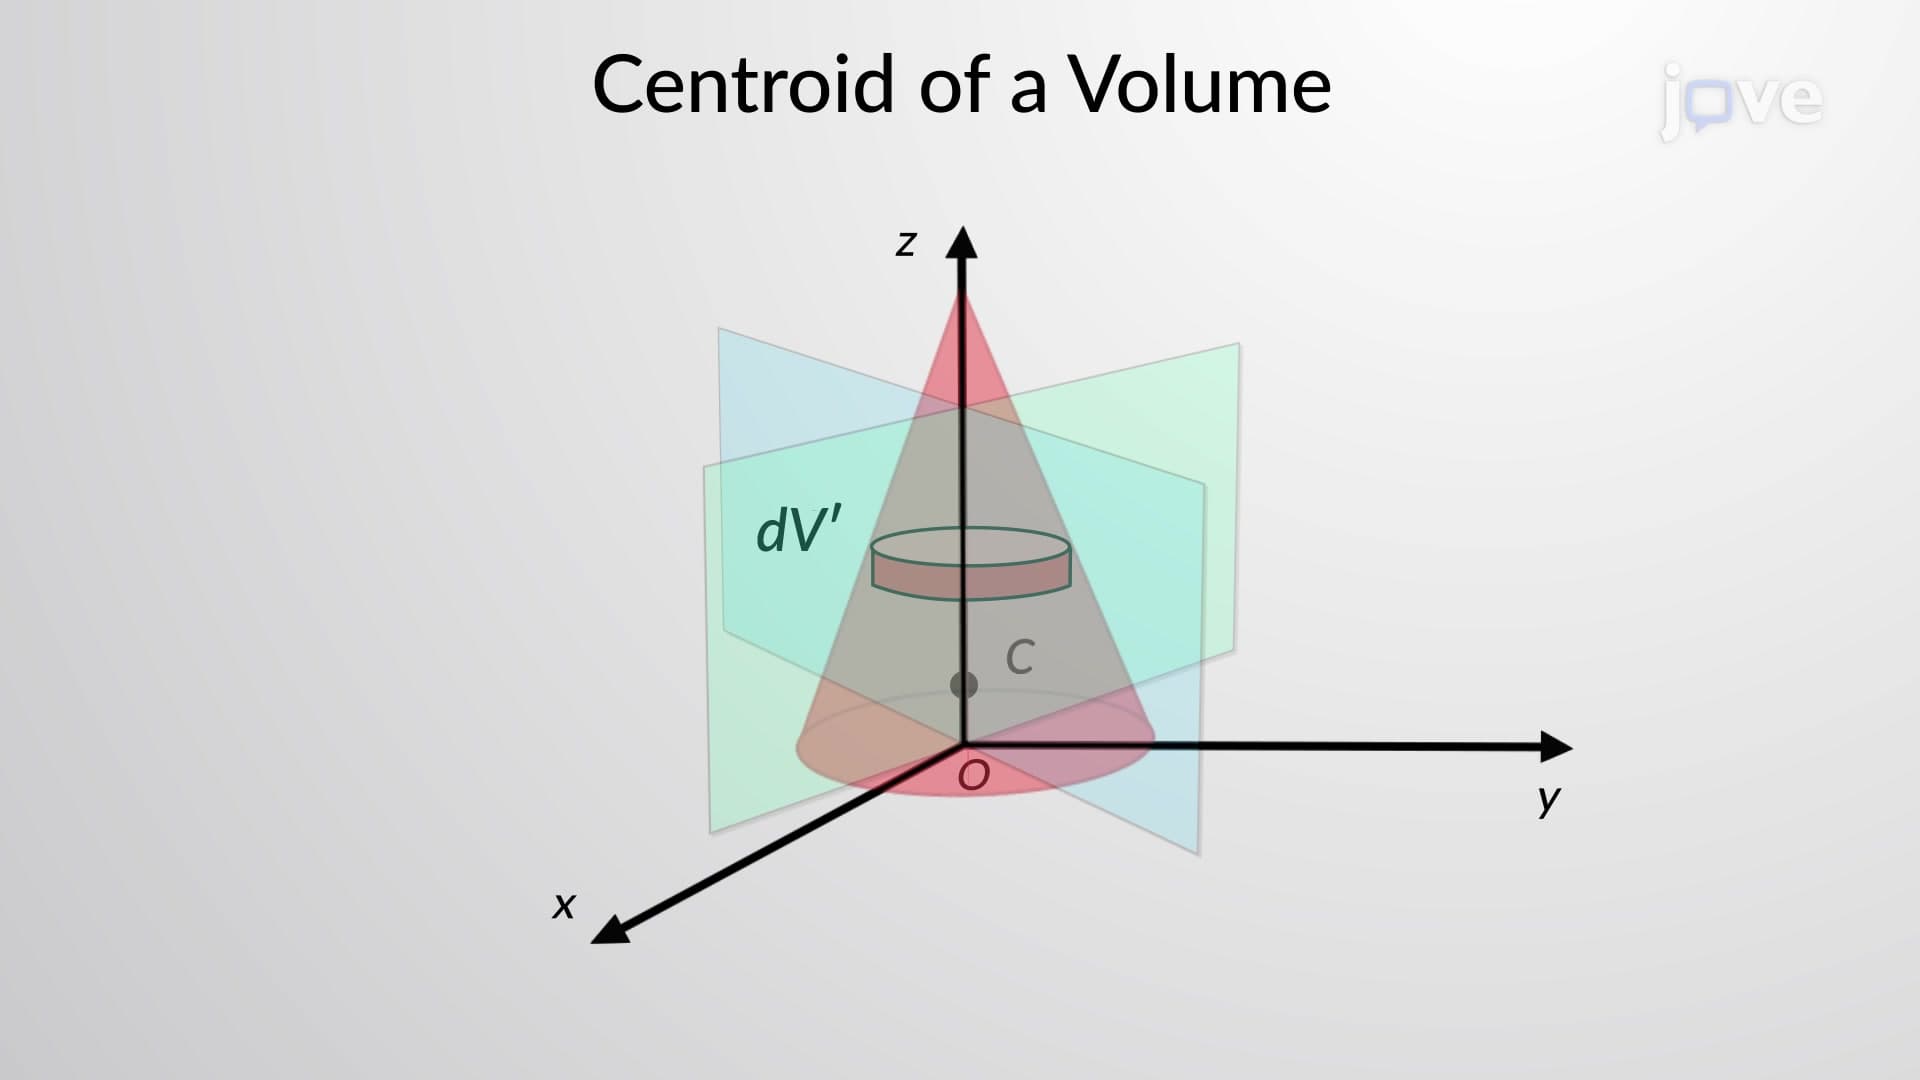
Centroid of a Body
For a homogeneous body with constant density, the centroid can usually be found using equations representing a balance of the moments of the body's volume. If the...
 01:13
Mean Absolute Deviation
Let us consider a dataset containing the number of unsold cupcakes in five shops: 10, 15, 8, 7, and 10. Initially, calculate the sample mean. Then calculate the deviation, or the difference, between each data value and the mean. Next, the absolute values of these deviations are added and divided by the sample size to...
 01:10
Central Tendency: Analysis
The mean is one such measure, calculated by totaling all values in a dataset and dividing by the number of values. For instance, the mean blood pressure reading (120, 130, 140, 150) would be 135. However, the mean can be affected by extreme values or outliers.
The median, another measure,...
 01:04
Random Error
 01:09
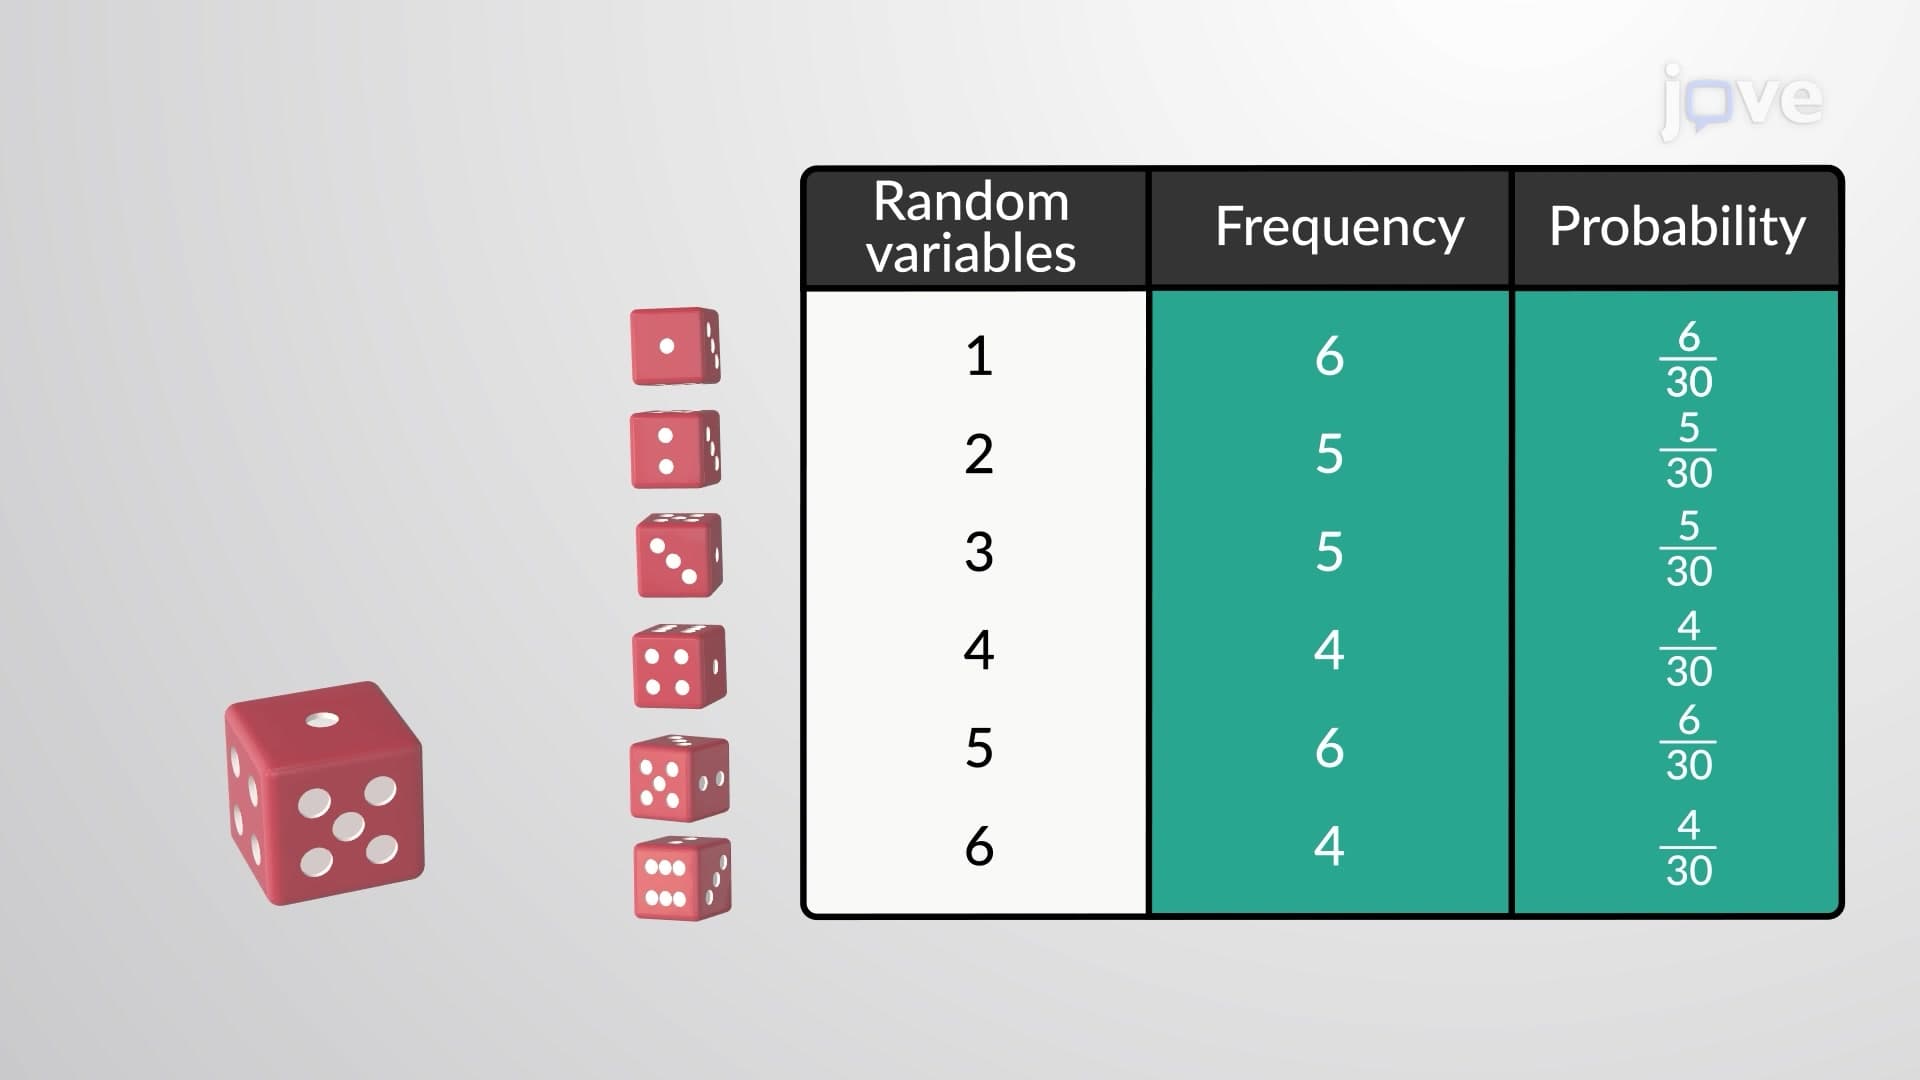
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...