Related Experiment Video
Updated: Oct 15, 2026
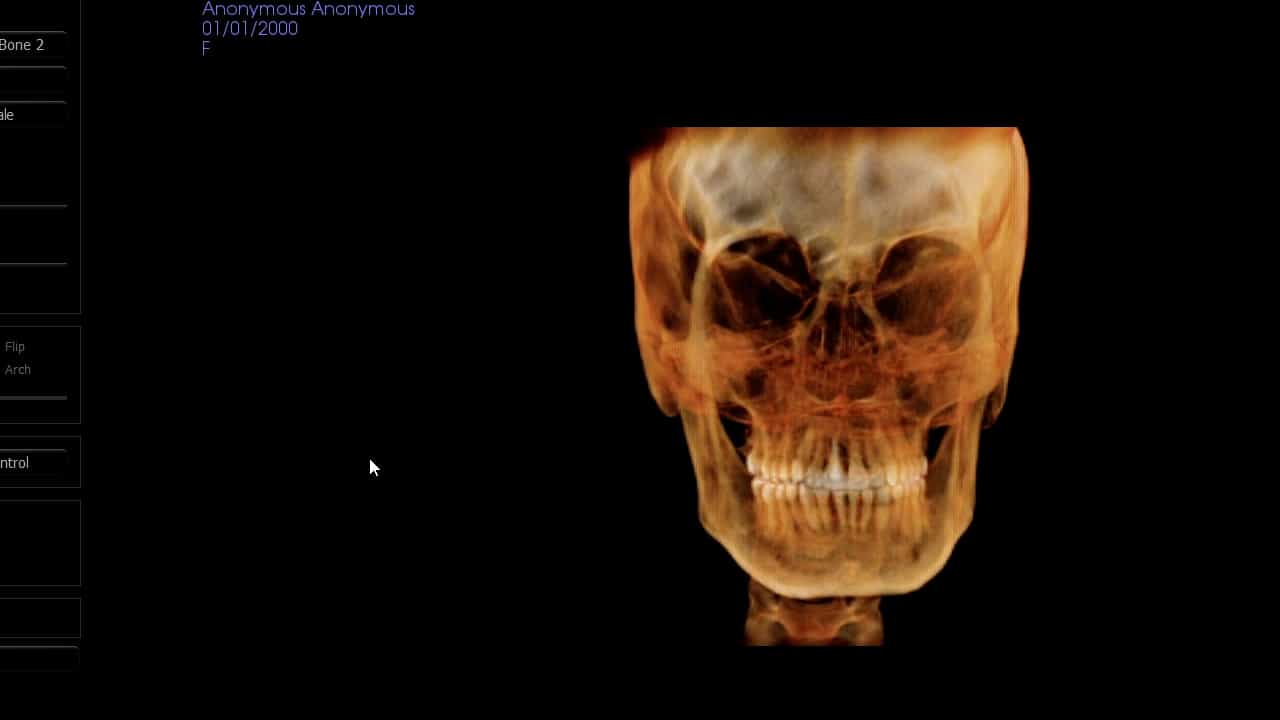
Three-Dimensional Cephalometric Landmark Annotation Demonstration on Human Cone Beam Computed Tomography Scans
Published on: September 8, 2023
Automated detection of patient positioning errors using mandibular region-focused deep learning analysis
Yasin Yasa1, Hamza Osman Ilhan2, Sevval Tugce Badik2
1Department of Oral & Maxillofacial Radiology, Ordu University, Ordu, Turkey; Department of Oral and Maxillofacial Medicine and Diagnostic Sciences, Case Western Reserve University School of Dental Medicine, Cleveland, OH, USA.

Objective:
Patient positioning errors in panoramic radiography are a critical issue that compromises diagnostic quality and necessitates retakes. The purpose of this study is to develop and validate a deep learning (DL)-based system for the automatic detection and multi-class classification of positioning errors using mandibular region extraction to enhance diagnostic quality. Furthermore, the study aims to evaluate the performance of hybrid models that combine traditional convolutional neural networks (CNNs) with vision transformer (ViT) architectures.
Methods:
In this retrospective study, 1,490 panoramic radiographs acquired between 2020 and 2023 were analyzed (691 error-free, 799 erroneous). Errors were classified into six sub-categories: head tilted downward, head tilted upward, biting the notch anteriorly, biting the notch posteriorly, head rotated laterally, and head tilted laterally. YOLOv10 and Mask R-CNN models were compared for mandibular region detection and extraction. For classification, the performance of five CNN architectures (ResNet18, ConvNeXt, EfficientNetV2-M, VGG19, DenseNet121), three ViTs (DeiT, BEiT, Swin), and a novel Hybrid model combining ConvNeXt and Swin Transformer were evaluated on both full images and isolated mandibular images. Model performances were analyzed using accuracy, precision, sensitivity, F1-score, and area under the receiver operating characteristic curve metrics with five fold cross-validation.
Results:
In mandibular region extraction, YOLOv10 demonstrated better performance compared to Mask R-CNN, achieving an mAP@0.5 score of 0.976. In the binary classification (erroneous/error-free) task, the Hybrid model trained on mandibular images achieved the highest performance with an accuracy of 73.02%, a precision of 0.7296, and an F1-score of 0.7280. For the 6-Class error-type classification, the Hybrid model also outperformed all other architectures with an accuracy of 56.91%. In full-image analyses, the Swin Transformer yielded competitive results (binary: 70.81%, multi-class: 56.51%).
Conclusions:
The proposed DL system demonstrates feasibility for the automated detection of positioning errors in panoramic radiography. The study proves that mandibular region-focused (ROI) analysis improves classification success compared to full-image analysis and that the hybrid use of CNN and Transformer architectures is more effective than single models in distinguishing complex imaging errors. This system holds promise for standardizing quality control processes in clinical workflows.