Related Experiment Video
Updated: Oct 15, 2026
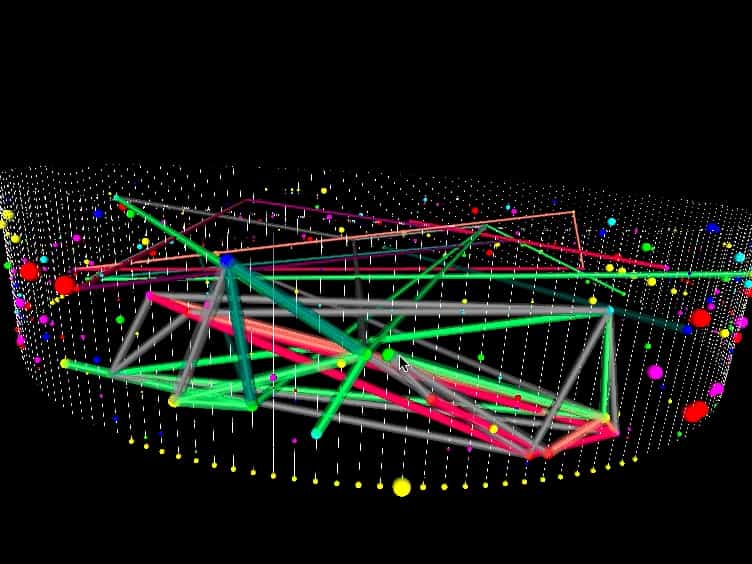
Optimization of Synthetic Proteins: Identification of Interpositional Dependencies Indicating Structurally and/or Functionally Linked Residues
Published on: July 14, 2015
Functional alignment of protein language models via reinforcement learning
Nathaniel Blalock1,2, Srinath Seshadri2, Kensuke Nakamura2,3
1Department of Chemical and Biological Engineering, University of Wisconsin-Madison, Madison, WI, USA.

Abstract:
Protein language models (pLMs) enable generative design of novel protein sequences but remain fundamentally misaligned with protein engineering goals, as they lack explicit understanding of function and often fail to improve properties beyond those found in nature. We introduce Reinforcement Learning from eXperimental Feedback (RLXF), a general framework that aligns protein language models with experimentally measured functional objectives, drawing inspiration from the methods used to align large language models like ChatGPT. Applied across five diverse protein families, RLXF improves generation of high-functioning variants beyond pre-trained baselines. We demonstrate this with CreiLOV, an oxygen-independent fluorescent protein, where RLXF-aligned models generate sequences with significantly enhanced fluorescence, including the most fluorescent CreiLOV variants reported to date. Our results indicate that RLXF-aligned models effectively integrate the evolutionary knowledge encoded in pre-trained pLMs with experimental observations, improving the success rate of generated sequences and enabling the discovery of synergistic mutation combinations that are difficult to identify through zero-shot or evolutionary approaches. RLXF provides a scalable and accessible approach to steer generative models toward desired biochemical properties, enabling function-driven protein design beyond the limits of natural evolution.
Related Concept Videos
 01:27
Associative Learning
Classical conditioning, also known...
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:58
Cooperative Allosteric Transitions
 01:12
Observational Learning
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...