Related Experiment Video
Updated: Oct 19, 2026
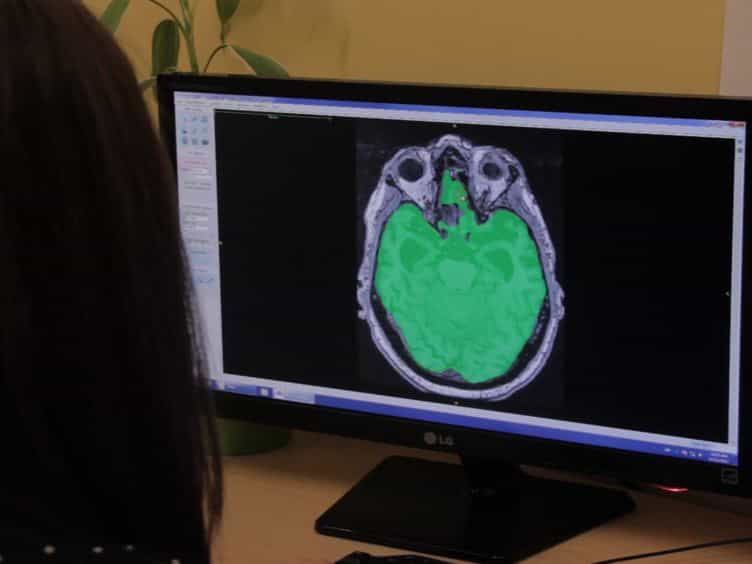
Lesion Explorer: A Video-guided, Standardized Protocol for Accurate and Reliable MRI-derived Volumetrics in Alzheimer's Disease and Normal Elderly
Published on: April 14, 2014
MEMOIR-VLM-a multimodal vision-language model for Alzheimer's disease classification and question answering
Sohail Haresh Gidwani1, Tamoghna Chattopadhyay1, Sophia I Thomopoulos1
1Imaging Genetics Center, Mark and Mary Stevens Neuroimaging and Informatics Institute, Keck School of Medicine, University of Southern California, Marina del Rey, CA, United States.

Introduction:
Alzheimer's disease (AD) affects an estimated 55 million people worldwide and is projected to nearly double by 2050, creating a need for scalable, non-invasive AI systems that can classify disease stage, support multimodal clinical reasoning, and interact in natural language. Most deep learning work on AD focuses on single-modality classification without natural-language interaction and typically assumes complete input data.
Methods:
We present MEMOIR-VLM (Multimodal Encoder with Missing-modality and Open-ended Inference for Retrieval), a modular two-stage vision-language framework trained and evaluated on 2,363 ADNI subjects. The first stage is a missing-modality-aware encoder that fuses T1-weighted MRI and DTI fractional anisotropy maps with structured clinical scores via cross-attention fusion with stochastic modality dropout, allowing a single set of weights to operate on any of the seven non-empty modality subsets without imputation. After CLIP/InfoNCE contrastive pretraining, the encoder is fine-tuned for multi-task prediction of 3-way diagnosis, binary diagnosis, CDR-SB, age, and sex. The second stage extends the frozen encoder into a retrieval-augmented generation pipeline for case-based reasoning and open-ended visual question answering.
Results:
On held-out ADNI test data, with CDR-SB excluded from the inputs to remove a cognitive-score leak, the encoder achieved 91.3% balanced accuracy for CN vs. dementia and 68.2% balanced accuracy for 3-class diagnosis (macro-F1 = 0.681); age was predicted with a 5.96-year MAE. When the diagnosis field was withheld from retrieved captions, no evaluated LLM exceeded a retrieval-only k-NN majority vote (0.673), which itself closely matched the encoder's 3-class accuracy (0.682). The RAG-VQA layer showed strong text fidelity (BERTScore = 0.894; SBERT cosine similarity = 0.811). Zero-shot external validation on OASIS-3 (1,048 subjects, no diffusion data) retained 78.7% balanced accuracy for CN vs. impaired (AUC = 0.889) using identical ADNI-trained weights with the DTI branch masked.
Discussion:
MEMOIR-VLM combines missing-modality-aware multimodal encoding, multi-task clinical prediction, and retrieval-grounded natural-language reasoning within a single modular framework. The results support using the encoder, optionally with k-NN voting, as the diagnostic component and the RAG-VQA layer as an interpretable natural-language interface that surfaces comparable cases and readable clinical summaries. The external validation results further demonstrate the practical value of the missing-modality mechanism when an imaging modality is unavailable.
Related Concept Videos
 01:29
Alzheimer Disease l: Introduction
 01:26
Alzheimer's Disease: Overview
The clinical diagnosis of AD hinges on the presence of memory and other cognitive impairments. Biomarkers, such as changes in Aβ and tau...
 01:22
Dementia l: Introduction
 01:23
Alzheimer Disease ll: Pathophysiology