Related Experiment Video
Updated: Oct 19, 2026
Application of Granger Causality Analysis of the Directed Functional Connection in Alzheimer's Disease and Mild Cognitive Impairment
Published on: August 7, 2017
It's a wrap: deriving distinct discoveries with FDR control after a GWAS analysis
Benjamin B Chu1, Zihuai He1,2,3, Chiara Sabatti1,4
1Department of Biomedical Data Science, Stanford School of Medicine, Stanford, CA 94304, USA.

Motivation:
The standard analysis pipeline for genome-wide association studies (GWAS) is based on marginal tests of association. These are computationally convenient and portable, but the discoveries are not immediately interpretable and require post-processing such as "clumping" and "fine mapping." An interesting alternative is provided by conditional independence hypotheses: their rejections lead to distinct signals across the genome, accounting for measured confounders and pointing to separate causal pathways. Recent work has shown how summary statistics resulting from the standard marginal GWAS can be used as input to test conditional independence hypotheses while controlling the false discovery rate (FDR). We previously developed a pipeline tailored to European genomes.
Results:
Here we introduce and release new software (solveblock) extending this capability to a much richer collection of studies. Given a set of genotyped samples, or a reference dataset, the new pipeline efficiently estimates the high-dimensional correlation matrices that describe dependencies across the genome, making rather common sparsity assumptions. Taking this sample-specific estimate as input, the software identifies groups of genetic variants that are highly correlated and uses them to define an appropriate resolution for conditional independence hypotheses. Finally, we compute the distribution for the exchangeable negative controls necessary to test these hypotheses. Simulations based on five UK Biobank sub-populations, illustrate the method's FDR control. The analysis of 26 phenotypes of varying polygenicity in British individuals, results in additional discoveries, compared to standard marginal association testing.
Availability And Implementation:
Our code, precompiled software, and processed files for these five sub-populations are openly shared.
Related Concept Videos
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:14
Identifying Statistically Significant Differences: The F-Test
 01:11
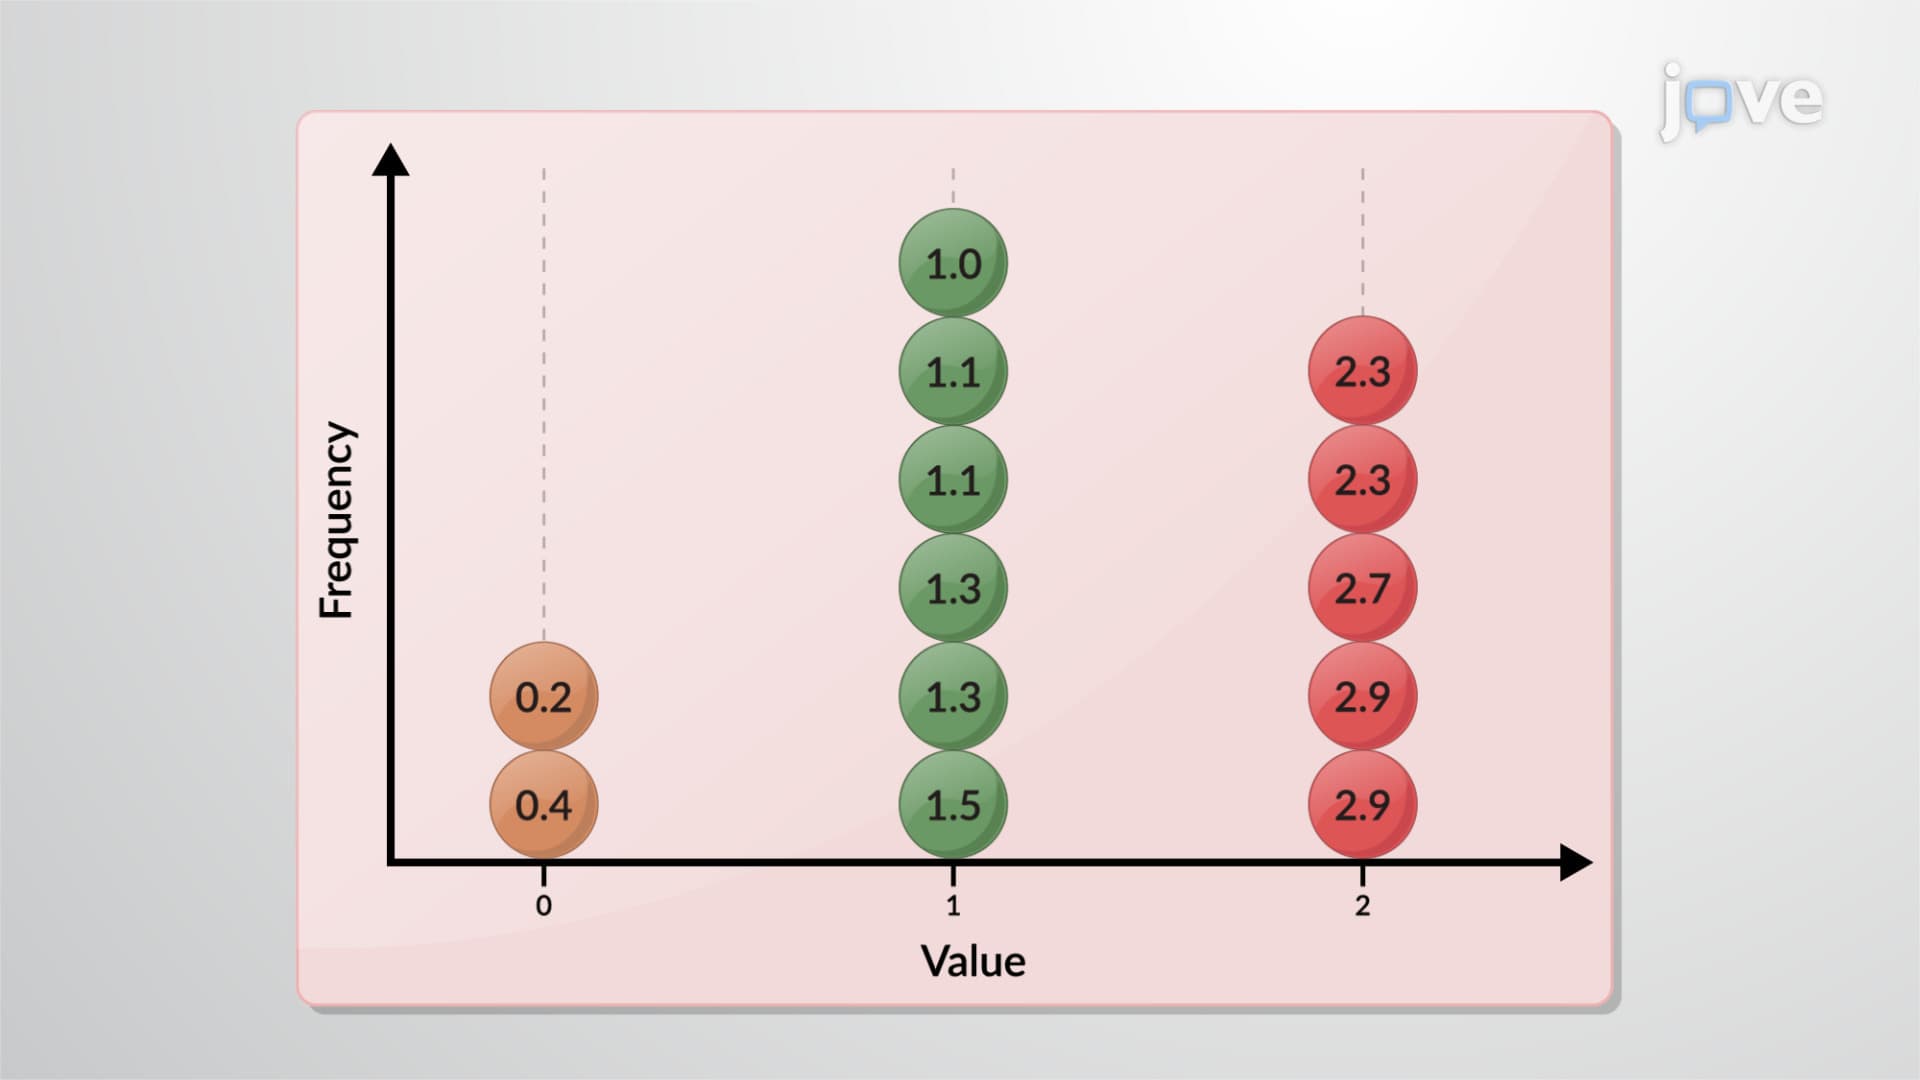
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:14
Statistical Analysis System (SAS)
Applications: SAS finds applications in numerous fields, including healthcare for clinical trial analysis, finance for risk assessment, marketing for customer data analysis, and...