Related Experiment Video
Updated: Oct 20, 2026
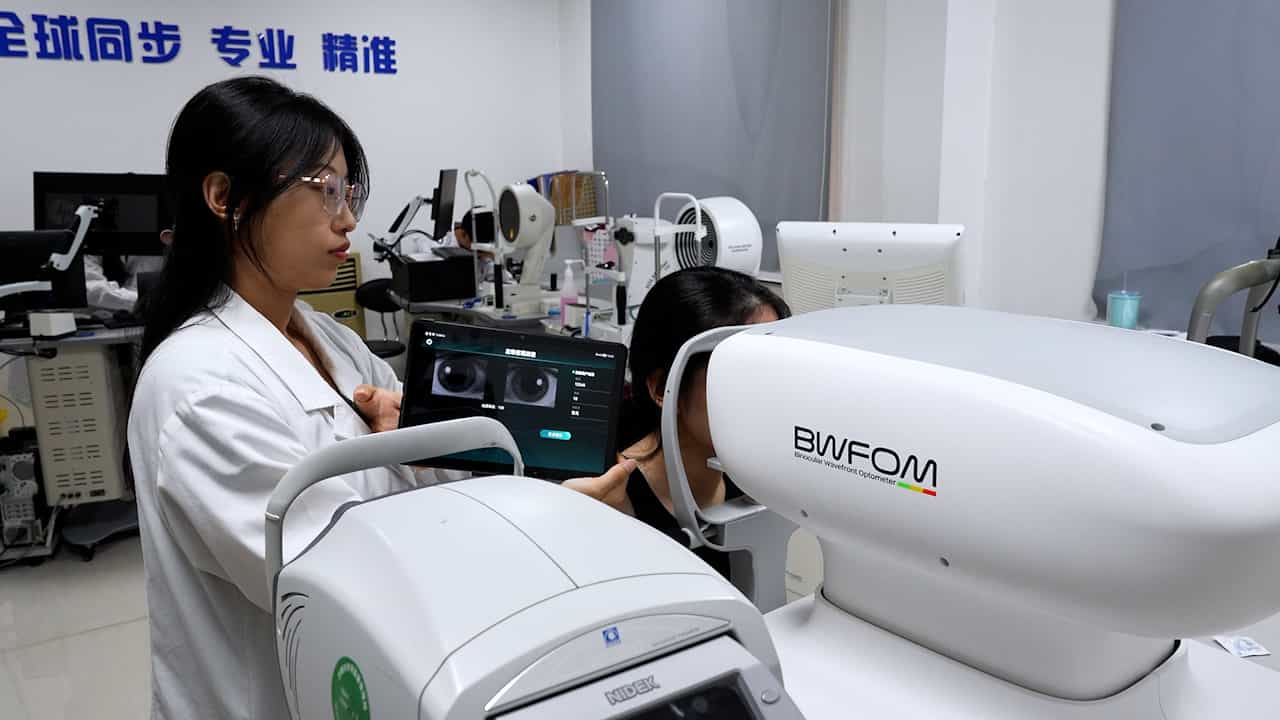
Comparison of Agreement and Accuracy using Binocular Wavefront Optometer with Autorefractor and Phoropter
Published on: September 16, 2025
Evaluator-Masked Assessment of 4 Consumer-Facing Large Language Models on Expert Anterior Segment Ophthalmology
Soonwon Yang1, Hyoji Han1, Hyun Soo Lee1
1Department of Ophthalmology, Eunpyeong St. Mary's Hospital, College of Medicine, The Catholic University of Korea, Seoul, Republic of Korea.

Objective:
To compare expert-rated quality and safety of responses from four contemporary large language models (LLMs)-ChatGPT, Gemini, Claude, and Grok-on expert-level anterior segment ophthalmology questions.
Design:
Cross-sectional, masked, randomized-display-order, multievaluator comparative study.
Participants:
Eleven fellowship-trained cornea and anterior segment subspecialists.
Methods:
Forty-five expert-level questions spanning six anterior segment domains were administered to each LLM under zero-shot conditions in a single prespecified session (January 19, 2026), with memory, browsing, and retrieval disabled. Responses were masked to model identity and independently rated on five 5-point Likert metrics (expert-rated accuracy, completeness/clinical utility, clarity/readability, overall safety, and potential for harm). No specialist-authored reference answer key was used; all metrics index expert-rated perception rather than verified clinical correctness.
Main Outcome Measures:
Median [interquartile range], mean ± standard deviation, favorable-rating proportion (≤2) with 95% bootstrap confidence interval, Friedman omnibus with Kendall's W, and Bonferroni-adjusted pairwise Wilcoxon tests with rank-biserial correlation. Prespecified sensitivity analyses included length-adjusted mixed models and a masking-integrity diagnostic; post hoc analyses added question-level severe-safety and style-restricted comparisons.
Results:
All 9900 ratings (45 questions × 4 LLMs × 5 metrics × 11 evaluators) were complete. Differences were significant for all three quality metrics (Friedman P < 0.001; Kendall's W = 0.44-0.54); Claude and Grok were each rated more favorably than ChatGPT and Gemini (all adjusted P < 0.001; |r_rb| = 0.73-0.98). No statistically significant between-model difference was detected in mean safety scores. Post hoc, more questions elicited ≥ 1 severe overall-safety rating for Claude (35.6%) and Grok (33.3%) than for ChatGPT (6.7%) or Gemini (11.1%) (Cochran Q = 23.4, P < 0.001), persisting when two-evaluator concurrence was required. Ordinal Krippendorff's α was 0.021-0.168; the 11-evaluator mean used as the primary analytic unit showed moderate reliability (intraclass correlation coefficient [ICC(2,k)] = 0.58-0.69 for quality metrics).
Conclusions:
Claude and Grok received more favorable expert-rated quality than ChatGPT and Gemini. Post hoc, a larger severe-safety-rating tail was identified for these two models despite no significant difference in mean safety; this signal is hypothesis-generating. The findings reflect expert preference, not validated clinical correctness, at one time point.
Financial Disclosures:
The authors have no proprietary or commercial interest in any materials discussed in this article.