Related Experiment Video
Updated: Oct 20, 2026
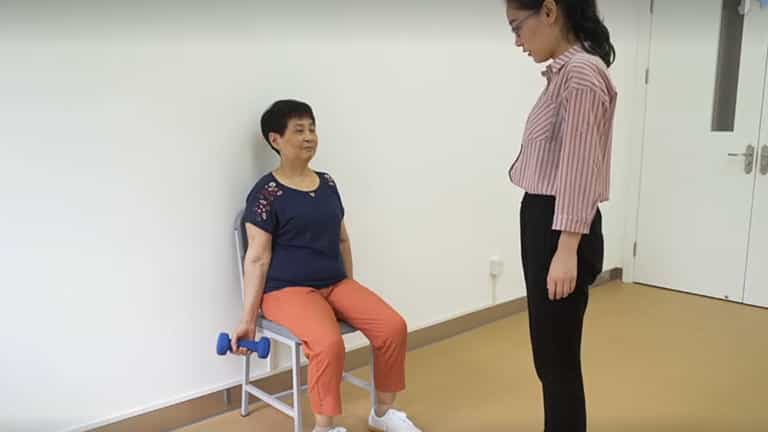
Home-Based Prescribed Pulmonary Exercise in Patients with Stable Chronic Obstructive Pulmonary Disease
Published on: August 24, 2019
Evaluating COPD care assistance: a comparative study of ChatGPT-3.5, ChatGPT-4.0, and ERNIE bot performance
Zhongshang Dai1,2,3,4, Zihang Zeng5,6,7,8,4, Zijie Zhan9
1Department of Infectious Diseases, The Second Xiangya Hospital, Changsha, China.

Background:
Large language model (LLM) chatbots are increasingly used to provide health information, yet their reliability in addressing chronic obstructive pulmonary disease (COPD) care questions in the Chinese context remains unclear. To evaluate and compare the performance of three publicly available LLM chatbots - ChatGPT-3.5, ChatGPT-4.0 (OpenAI), and ERNIE Bot (Baidu) - in answering chronic obstructive pulmonary disease (COPD) care questions in China.
Methods:
We performed a cross-sectional comparative evaluation of three publicly available LLM chatbots (ChatGPT-3.5, ChatGPT-4.0, and ERNIE Bot). We developed 40 COPD care questions spanning 7 prespecified domains relevant to patient education and self-management. All questions were submitted in Chinese in independent new chat sessions to minimise context carryover. Three consultant-level respiratory physicians independently rated each response for accuracy (1 = poor, 2 = borderline, 3 = good). We summarised accuracy as the sum of three ratings (range 3-9) and derived a majority-vote accuracy category. For responses rated 'good' by majority vote, physicians additionally rated comprehensiveness on a five-point scale. Information quality was further assessed using a modified DISCERN framework and the Patient Education Materials Assessment Tool (PEMAT) understandability and actionability domains.
Results:
Most responses were rated as 'good' for accuracy across chatbots. ERNIE Bot achieved higher total accuracy scores than ChatGPT-3.5 and ChatGPT-4.0, and a higher proportion of 'good' ratings in this Chinese-language evaluation. However, comprehensiveness scores for 'good' responses were low across all systems (mean ~ 1.4-2.0/5), and PEMAT actionability was limited, indicating that few responses included concrete, patient-executable steps.
Conclusions:
Our findings suggest that LLM chatbots may support basic COPD patient education in Chinese settings, but current responses often lack sufficient comprehensiveness and actionable guidance. These tools should not be used as standalone clinical advice and require appropriate safeguards and clinician oversight.
