Related Experiment Video
Updated: Oct 27, 2026
Using Phylogenetic Analysis to Investigate Eukaryotic Gene Origin
Published on: August 14, 2018
Preprocessing missing data and partitions for phylogenetic analysis under dynamic homology, with application to
Daniel Yudi Miyahara Nakamura1,2, Taran Grant1, Ward C Wheeler2
1Instituto de Biociências, Universidade de São Paulo, São Paulo, Brazil.

Abstract:
In dynamic homology, data must usually be preprocessed to distinguish sequencing artefacts (missing data) from insertion-deletion events, but empirical studies using POY/PhyG have employed manual preprocessing. Here, we compare different procedures for handling missing data for dynamic homology, present Python scripts to automate these procedures, and evaluate their performance using 60 simulated and 4 empirical datasets (including Sanger, phylogenomic and historical DNA sequences). We clarify that coding missing data as gaps or unknown nucleotides/amino acids is theoretically and methodologically inappropriate. In contrast, isolating missing data via partitioning or coding it as any observed state or no state ("?", the maximally polymorphic state; N + gap for nucleotides, X + gap for amino acids) is defensible but involves trade-offs. Partitioning can decrease time complexity but weakens homology testing by isolating potentially homologous nucleotides in different partitions. Conversely, question marks enable unconstrained homology testing but increase time complexity. To balance these trade-offs, we propose heuristic strategies to select optimal partitioning. Our methods reduced time complexity in large simulated datasets and improved tree costs in all empirical datasets, highlighting the importance of properly identifying missing data in dynamic homology analysis.
More Related Videos
Related Concept Videos
 01:28
Microbial Phylogeny
 02:54
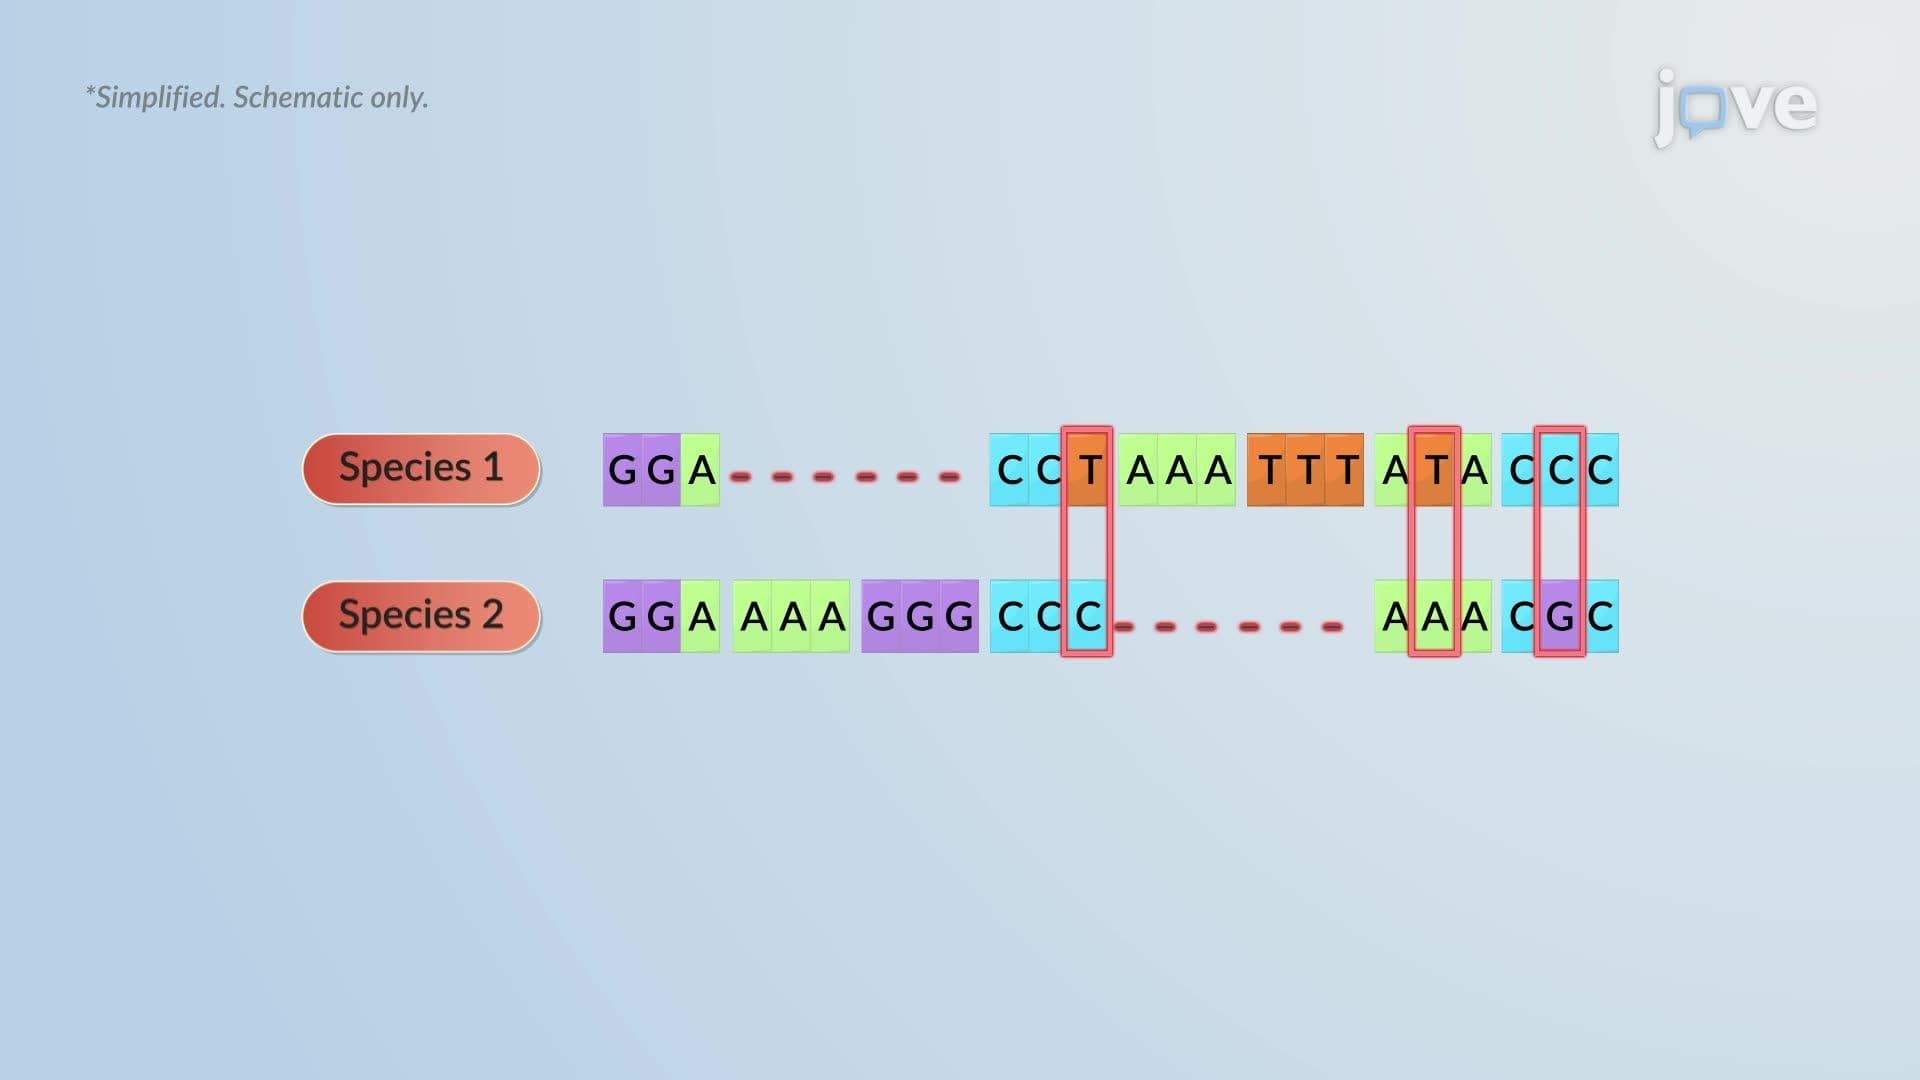
Evolutionary Relationships through Genome Comparisons