Related Experiment Video
Updated: Oct 28, 2026
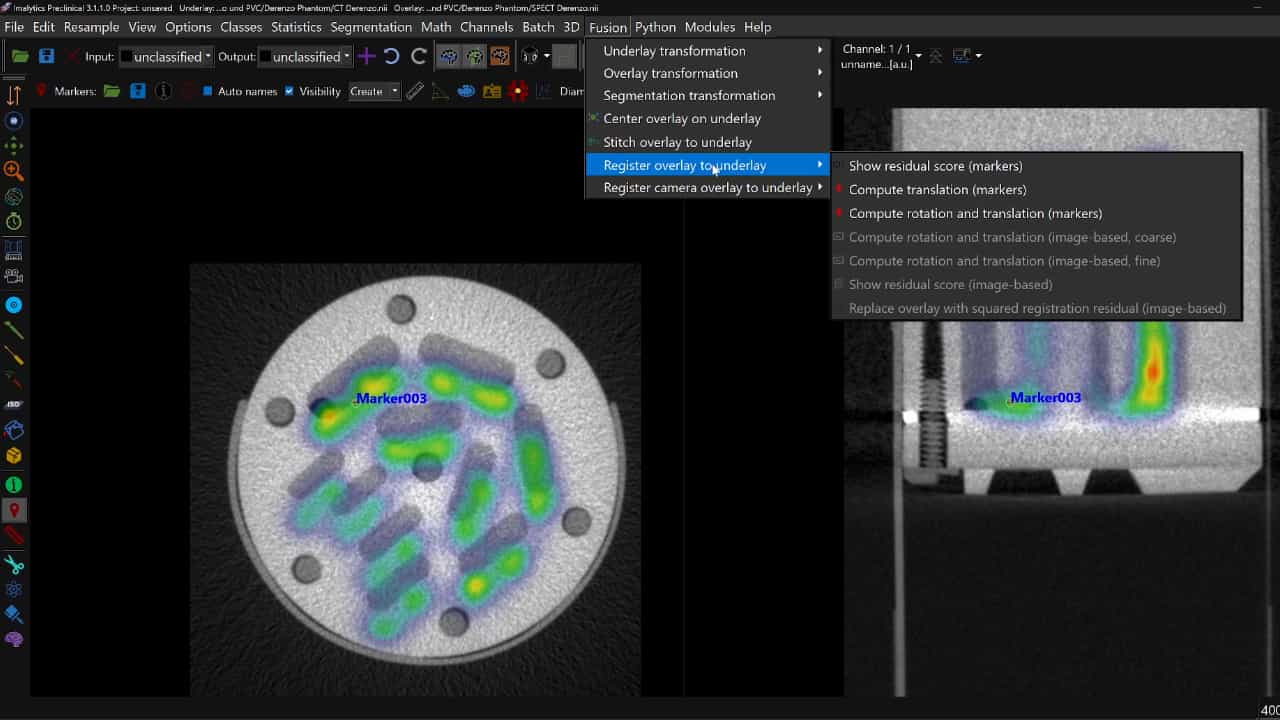
Multimodal Cross-Device and Marker-Free Co-Registration of Preclinical Imaging Modalities
Published on: October 27, 2023
Masked Position Modeling as a Pre-Training Strategy for Foundational Deformable Image Registration Models

Abstract:
The core objective of deformable image registration (DIR), estimating a displacement vector field that aligns two images, is fundamentally the same across imaging modalities and anatomical regions. Although this shared objective should imply the use of foundation models, most deep learning approaches for DIR operate within narrow domain-specific settings. Vision Transformers (ViTs) are the predominant choice for foundation models in many image processing tasks due to their excellent generalization capabilities and robustness to domain shifts. However, their use remains largely underexplored for DIR, which we attribute to a lack of suitable pre-training schemes. To address this need, we introduce MPM-Reg, a transferable, modality-agnostic training paradigm based on masked position modeling (MPM), enabling the use of fully transformer-based models as foundation models for image registration. Unlike conventional masked data modeling, which predicts the content of masked image patches, MPM masks the positional information and predicts the spatial relationship between image patches. Initially, we employ MPM on single images, which naturally aligns self-supervised pre-training of ViTs with the downstream registration task. Subsequently, we extend MPM to predict the positions of target patches within source images, re-formulating DIR through the lens of MPM. Experiments across eleven diverse datasets demonstrate MPM-Reg's competitive performance compared to state-of-the-art baselines. Crucially, MPM-Reg benefits from heterogeneous multi-domain data, which degrades the performance of existing methods, paving the way for scalable foundation models for DIR.