Related Experiment Video
Updated: Oct 28, 2026
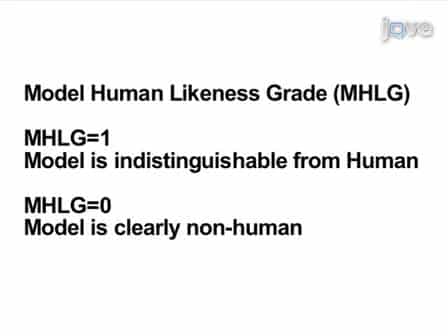
One Dimensional Turing-Like Handshake Test for Motor Intelligence
Published on: December 15, 2010
When It Comes to Benchmarks, Humans Are the Only Way
Adam Rodman1,2, Laura Zwaan3, Andrew Olson4,5
1Department of Medicine, Beth Israel Deaconess Medical Center, Boston.

Abstract:
AbstractImproved performance of large language models (LLMs) on traditional reasoning assessments has led to benchmark saturation. This has spurred efforts to develop new benchmarks, including synthetic computational simulations of clinical practice involving multiple AI agents. We argue that it is crucial to ground such efforts in extensive human validation. We conclude by providing four recommendations for researchers to better evaluate LLMs for clinical practice.
Related Concept Videos
 01:29
Measures of Intelligence
Validity refers to how well a test measures what it claims to measure. An intelligence test should accurately assess intelligence rather than another characteristic, like anxiety. Criterion validity is one way to evaluate this; it...
 01:23
Toxicity Testing in Animals
 02:43
Mouse Models of Cancer Study
The development of transgenic, knockout, and knock-in mice has led to an exponential increase in their use as model organisms in research,...
 01:52
Regression Toward the Mean
 02:07
Blind Procedures
 01:22
Case Studies