Related Experiment Videos
Text-Guided Feature Completion in the CLIP Embedding Space for Occlusion-Robust Facial Expression Recognition
1Department of Applied Artificial Intelligence, Hanyang University, 55, Hanyangdaehak-ro, Ansan-si 15588, Republic of Korea.

Abstract:
Camera-based affective sensing degrades sharply when the face is partially occluded by hands, masks, eyeglasses or headwear. Existing occlusion-robust facial expression recognition (FER) methods either discard the information carried by occluded regions through attention re-weighting, hallucinate it back at the pixel level, or restore it in a purely visual latent space; none of them can consult an external semantic description of what the hidden region ought to look like. We propose TeCoRe, a text-conditioned completion-and-recognition framework that restores occluded patch tokens directly inside the joint vision-language embedding space of a frozen CLIP encoder. A lightweight visibility gate estimates a per-patch occlusion probability; a two-layer transformer decoder reconstructs the occluded tokens using class-level textual emotion embeddings, produced by the frozen CLIP text encoder, as both cross-attention memory and an alignment target; and a gated blend passes clean tokens through unchanged so that completion cannot corrupt visible evidence. TeCoRe is trained as supervised FER using the ground-truth emotion labels for classification and text alignment, together with an auxiliary self-supervised reconstruction objective. Because the occlusion masks are synthesised during training, the pre-occlusion CLIP tokens of the same image provide the reconstruction target without requiring additional manual annotation. The CLIP backbone is completely frozen-no low-rank adapters, no landmarks, no segmentation priors-and only about 27 M head and decoder parameters are trained. On the standard RAN occlusion and pose subsets, TeCoRe reaches 91.42% on Occlusion-RAF-DB, 84.79% on Occlusion-FERPlus, and 62.42% on Occlusion-AffectNet. It achieves the highest accuracy in our comparison on Occlusion-RAF-DB and on the RAF-DB and FERPlus pose subsets, while remaining competitive but not leading on the FERPlus and AffectNet occlusion subsets. The ablation and control studies are reported as three-seed means so that the small differences between variants are not read off a single initialisation. A backbone-generality control shows positive mean gains from the proposed modules across all three evaluated frozen CLIP configurations, with the largest gain observed in the main ViT-L/14@336 setting. These results indicate that performing occluded-token completion in a joint vision-language space, with class-level text embeddings providing shared conditioning to the completion process, is an effective and parameter-efficient route to occlusion-robust FER.
Related Concept Videos
 01:24
Facial Feedback Hypothesis
 01:14
Muscles for Facial Expressions
 00:56
Extraction: Advanced Methods
 01:09
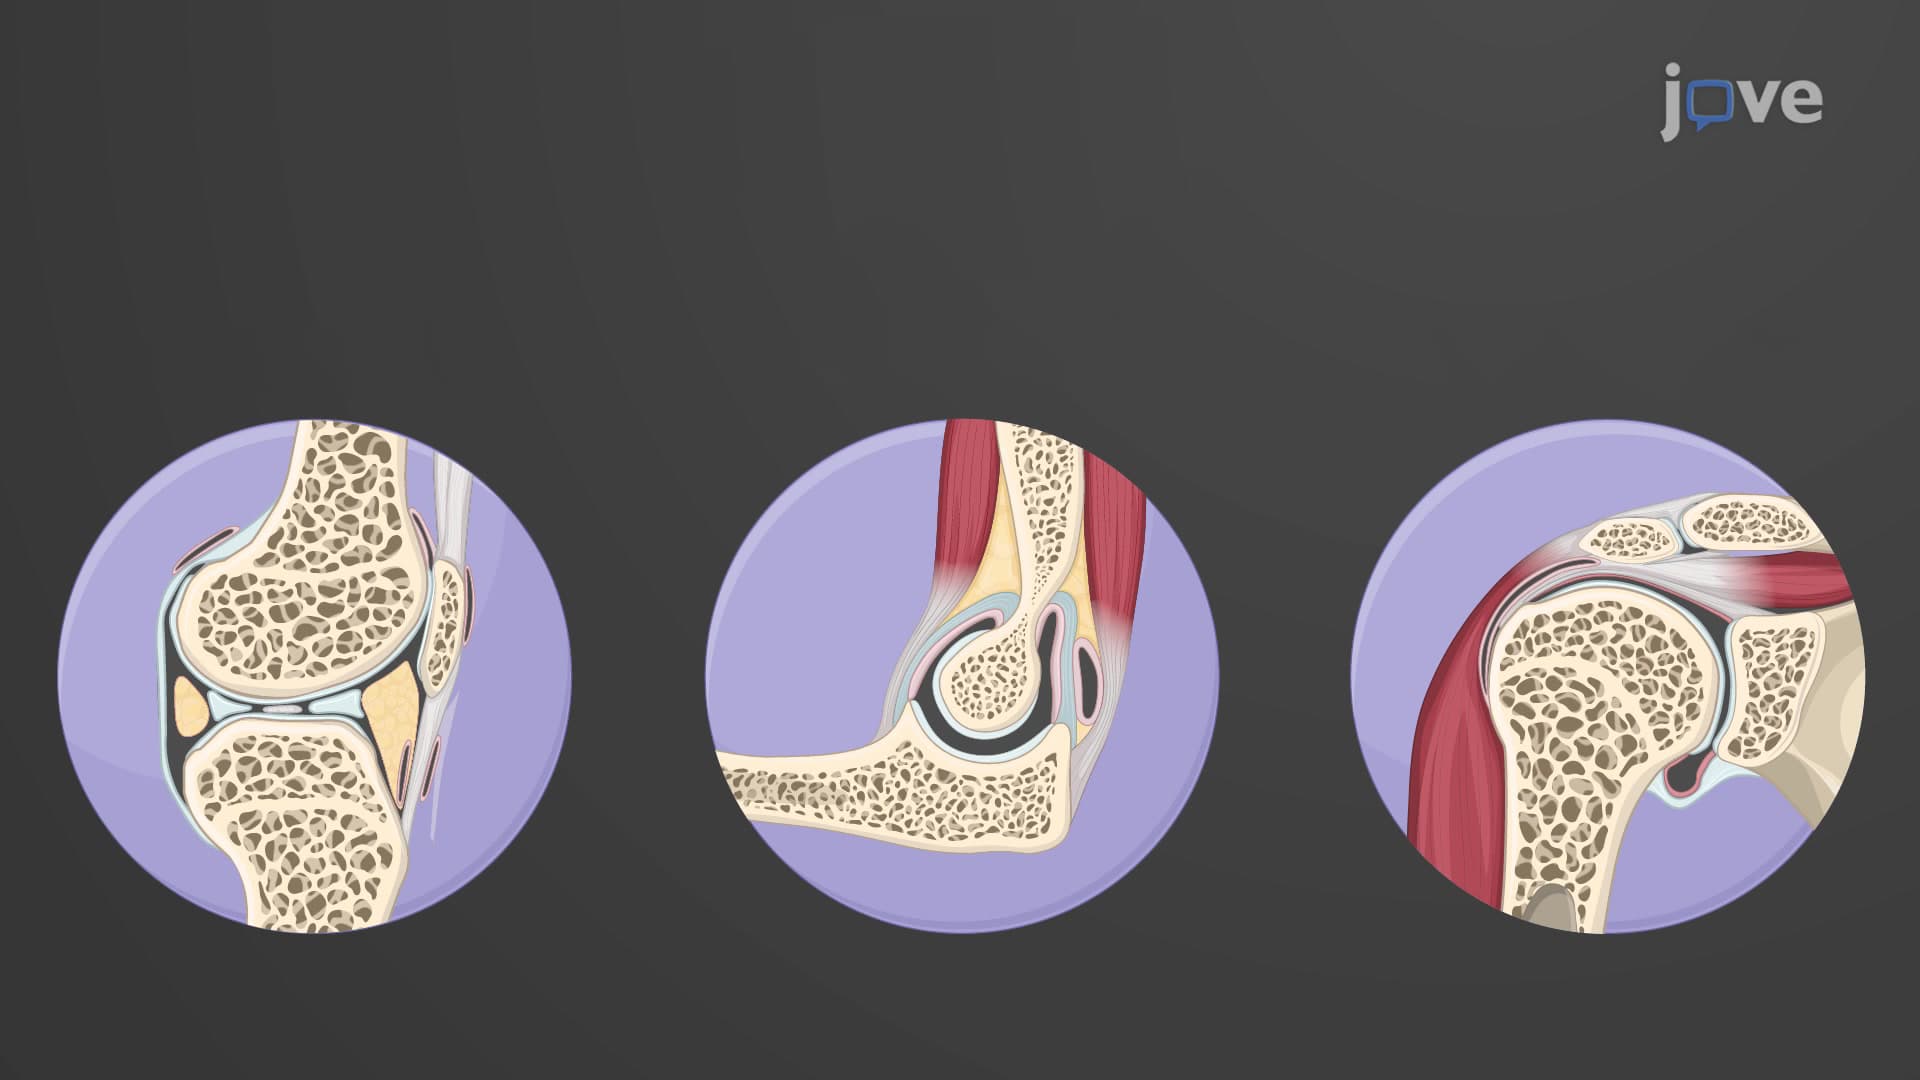
Functional Classification of Joints
The functional classification of joints is determined by the amount of mobility between the adjacent bones. Joints are functionally classified as a synarthrosis or immobile joint, an amphiarthrosis or slightly moveable joint, or as a diarthrosis, a freely moveable joint. Fibrous and cartilaginous joints can be functionally classified as either synarthroses or amphiarthroses, whereas all synovial joints are classified as diarthroses.
Synarthrosis
An immobile...
 01:24
Prosopagnosia
 01:22
Force Classification
Contact and non-contact forces are two of the most widely used categories of forces. As the name suggests, contact forces require physical contact between two objects to act upon each other. Examples of contact forces include frictional,...