Related Experiment Video
Updated: Oct 29, 2026
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Clustering Graphs Using Minimum Factorization Distance

Abstract:
Clustering graphs into different groups is a challenging problem due to the difficulty in quantifying the similarity or distance between graphs, especially when the graphs are large. In this work, we propose a novel approach by treating the adjacency matrices of two graphs as kernel matrices derived from some unknown indefinite kernel function applied to two discrete distributions. Based on this view, we define a measure called MMFD to quantify the dissimilarity between graphs via the distance between their underlying distributions. We prove that MMFD is a pseudo-metric. Although the initial formulation of MMFD appears complex, we demonstrate that it admits a computationally simple closed-form solution. To enhance efficiency in large-scale clustering tasks, we further propose MMFD-KM, a method with linear time and space complexity relative to the number of graphs. Additionally, we introduce a generalized version named MFD and its variant MFD$_{\rm{OT}}$, with theoretical guarantees, which more effectively leverage factor information from adjacency matrices. Based on MFD, an efficient graph clustering algorithm called MFD-KD is established. Experiments on synthetic graphs visually confirm the effectiveness of our methods in graph comparison. Results on 18 real-world datasets show that our approaches significantly outperform competing methods in clustering performance across three evaluation metrics, while also reducing computational time.
Related Concept Videos
 01:22
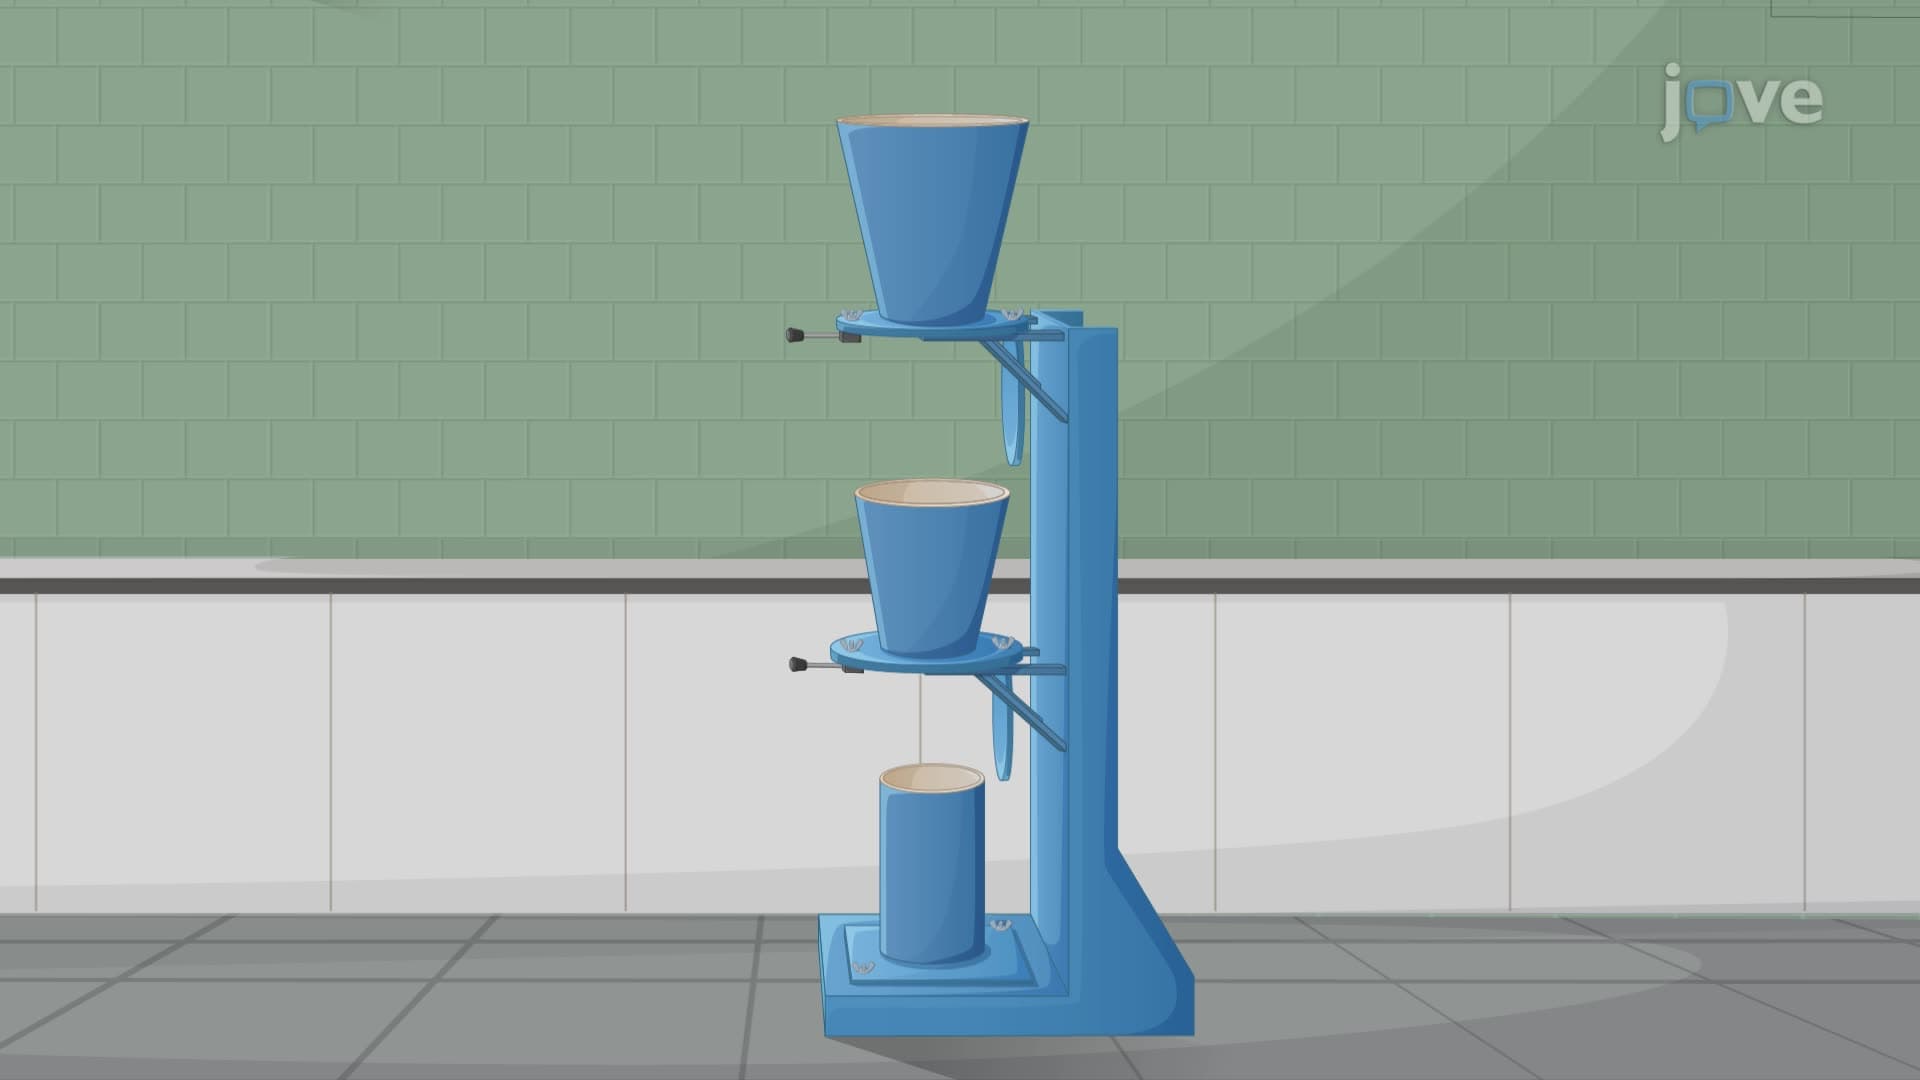
Compacting Factor test
The procedure begins by placing concrete into the upper hopper without any compaction. Once filled, the bottom door of this hopper is opened,...
 01:29
Distance Problem
 01:27
Graphs of Two-Variable Functions
 01:20
The Distance Formula
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:30
Graphs of Equations in Two Variables