Related Experiment Video
Updated: Oct 29, 2026
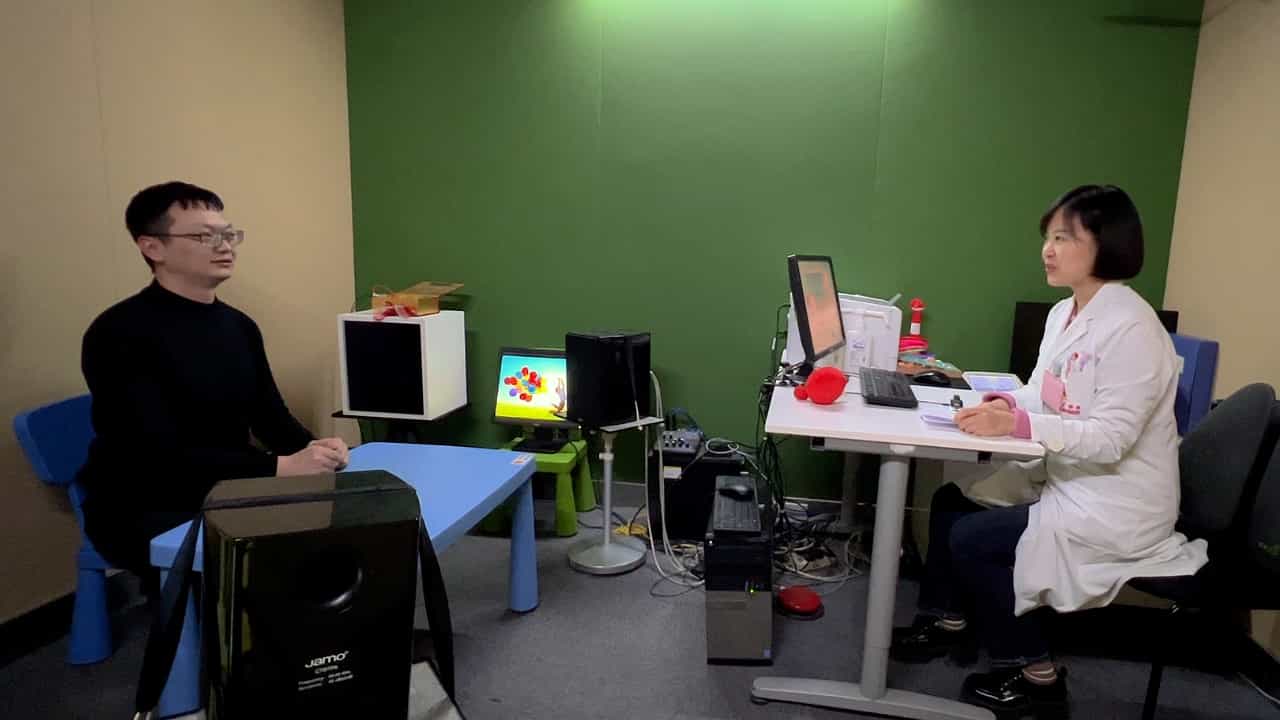
Systematic Hearing Performance Evaluation Process for Adolescents with Cochlear Implantation at Early Ages
Published on: March 24, 2023
Version-Specific Performance of ChatGPT in Audiogram Interpretation: Comparison of ChatGPT-4.0 and ChatGPT-5.1
Emel Tahir1, Ceren Karaçaylı2,3, Emre Dünder4
1Department of Otolaryngology, Faculty of Medicine, Ondokuz Mayıs University, Samsun, Türkiye.

Objective:
Large language models (LLMs) are increasingly explored for clinical decision support, yet how successive versions of the same model compare on diagnostic tasks remains unclear. This study aimed to quantify version-specific changes in diagnostic performance by directly comparing ChatGPT-4.0 and ChatGPT-5.1 on standardized pure-tone audiogram interpretation.
Study Design:
Comparative diagnostic performance study.
Setting:
Controlled experimental study using audiograms generated with simulation software.
Methods:
One hundred audiograms, including 20 with intentional masking errors, were generated using AudSim Flex® software and submitted to both model versions through a standardized 7-step diagnostic prompt based on ASHA criteria. Two board-certified otolaryngologists with audiological expertise independently scored each response on a 5-point Likert scale, yielding 1400 evaluations per model. Inter-rater agreement was assessed using quadratic weighted Cohen's kappa, and model comparisons were performed with the Wilcoxon signed-rank test.
Results:
Inter-rater reliability was acceptable overall (κ = 0.74-0.78), though agreement was lower for degree-of-loss classification with ChatGPT-5.1 (κ = 0.44). ChatGPT-5.1 scored significantly higher than ChatGPT-4.0 on 6 of 7 questions (P < .001), with effect sizes ranging from 0.53 to 0.94. The largest improvement appeared in degree-of-hearing-loss classification (median difference, +1.0 point). Bone conduction threshold identification was the only item without a significant between-version difference (P = .121). Both models performed poorly on audiograms containing masking errors.
Conclusion:
ChatGPT-5.1 demonstrated meaningful improvements over ChatGPT-4.0 in audiogram interpretation, particularly in higher-order diagnostic reasoning tasks. However, both versions struggled with clinically flawed input data. These findings underscore the need for version-specific benchmarking and expert oversight when integrating LLMs into audiological practice.