Leveraging Semantic Priors for Robust Multi-Exposure Image Registration and Fusion
Related Experiment Video
Updated: Oct 31, 2026
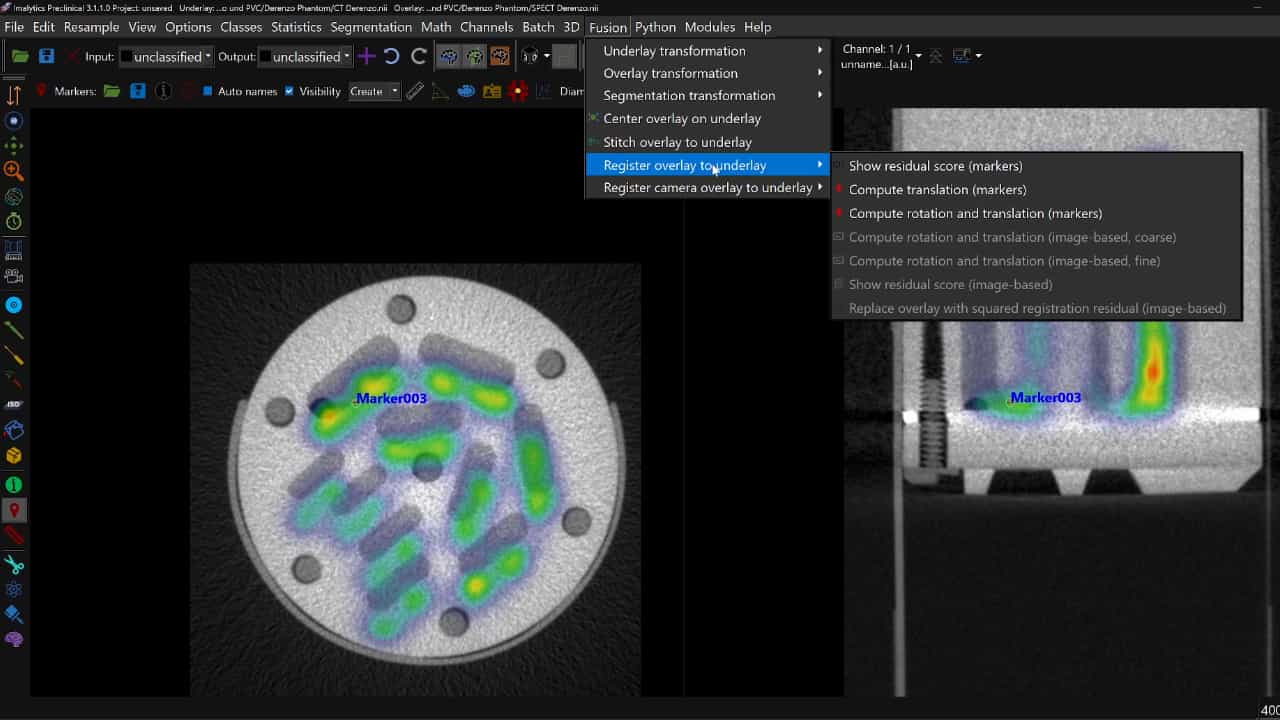
Multimodal Cross-Device and Marker-Free Co-Registration of Preclinical Imaging Modalities
Published on: October 27, 2023

Abstract:
Multi-exposure image fusion (MEF) aims to combine a sequence of differently exposed images into a single high-quality photograph. However, spatial misalignment caused by camera shake or object motion often leads to severe ghosting artifacts in the fused image. Existing methods struggle with large displacements and complex motions due to their reliance on low-level features that are sensitive to illumination variations. To address these challenges, we propose SPRFusion, a unified framework that leverages semantic priors from large pretrained vision models-specifically, the Segment Anything Model (SAM) and Contrastive Language-Image Pretraining (CLIP)-to optimize image registration and fusion jointly. Our method introduces a pixel-semantic feature fusion (PSFF) module that integrates local cues with global semantic understanding for robust optical flow estimation. In the fusion stage, we employ a Mamba-based backbone, jointly guided by a pretrained semantic embedding-based global-local contrastive loss implemented with CLIP and a SAM perceptual loss, leading to improved semantic consistency and perceptual fidelity. Extensive qualitative and quantitative experiments on static and dynamic scenes demonstrate that SPRFusion outperforms state-of-the-art methods in both registration accuracy and fusion quality. Code is available at https://github.com/hqj9994ever/SPRFusion.