Clinical quality of large language model responses to thyroid surgery questions: an expert comparative evaluation
Related Experiment Video
Updated: Nov 1, 2026
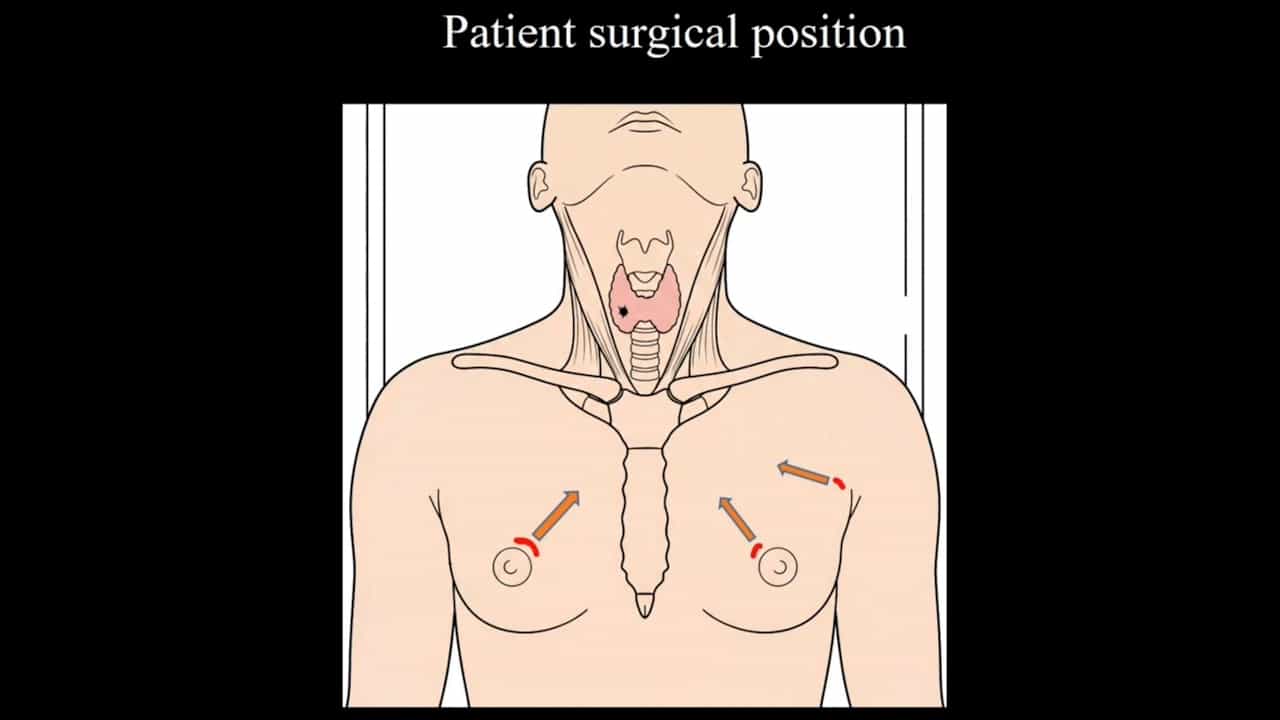
A Novel Contralateral Axillo-Bilateral-Breast Approach for Endoscopic Thyroid Surgery
Published on: July 28, 2026
Francesco Brucchi1,2, Alberto Balduzzi3, Daqi Zhang4
1Division of General Surgery, Istituto di Ricovero e Cura a Carattere Scientifico (IRCCS) Istituto Auxologico Italiano, Milan, Italy. Francesco.brucchi@unimi.it.

Background:
Large language models (LLMs) are increasingly used for medical information, but their reliability in thyroid surgery remains uncertain.
Methods:
Responses from ChatGPT, Google Gemini, Microsoft Copilot, and a blinded human expert comparator were evaluated across 18 thyroid surgery-related clinical questions. Five experienced thyroid surgeons independently rated all responses using a 5-point Likert scale reflecting overall clinical quality. Inter-rater reliability was assessed using intraclass correlation coefficients (ICCs), and differences between LLMs were analyzed with non-parametric repeated-measures tests; each LLM was compared descriptively with the human comparator.
Results:
Inter-rater agreement ranged from fair to moderate-good (ICC 0.36-0.66). All LLMs achieved high clinical quality scores (median 5), with means slightly below the human comparator (4.47-4.66 vs 4.80). No significant differences were detected among LLMs (Friedman test, p = 0.095), although a marked ceiling effect and question-level variability were observed.
Conclusions:
LLMs may support patient-facing thyroid surgery information, but specialist oversight remains essential.