Heteroscedastic nearest shrunken centroid classification: methods and applications to high-dimensional data
Related Experiment Video
Updated: Nov 3, 2026
Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Mohammad Omar Sahtout1, Haiyan Wang2
1Endpoint Consulting, LLC, Tucson, Arizona, 85742, USA.

Abstract:
Despite of recent advances in machine learning methods with huge training data, classification of high-dimensional, low-sample-size (HDLSS) data remains challenging because limited sample sizes increase the risk of overfitting and hinder reliable parameter estimation. The nearest shrunken centroid classifier, also known as Prediction Analysis of Microarrays (PAM), combines centroid-based discrimination with feature selection through thresholding. However, its homoscedasticity assumption may limit classification performance when feature variances differ across classes, as commonly observed in gene expression data. We propose a heteroscedastic extension of the nearest shrunken centroid framework that incorporates class-specific variances into both the test statistic and discriminant function. The proposed method retains the simplicity and interpretability of the original classifier while accommodating variance heterogeneity. By integrating the framework with soft, hard, and order thresholding strategies, we develop three new classifiers. We evaluate their performance through comprehensive simulation studies and applications to multiple multiclass cancer gene expression datasets. The results show that accounting for heteroscedasticity substantially improves classification accuracy, particularly with hard and order thresholding, while maintaining competitive feature sparsity. These findings highlight the importance of modeling variance heterogeneity in high-dimensional classification and provide practical tools for improved cancer subtype prediction.
Related Concept Videos
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance, comparing...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:15
Chebyshev's Theorem to Interpret Standard Deviation
 01:06
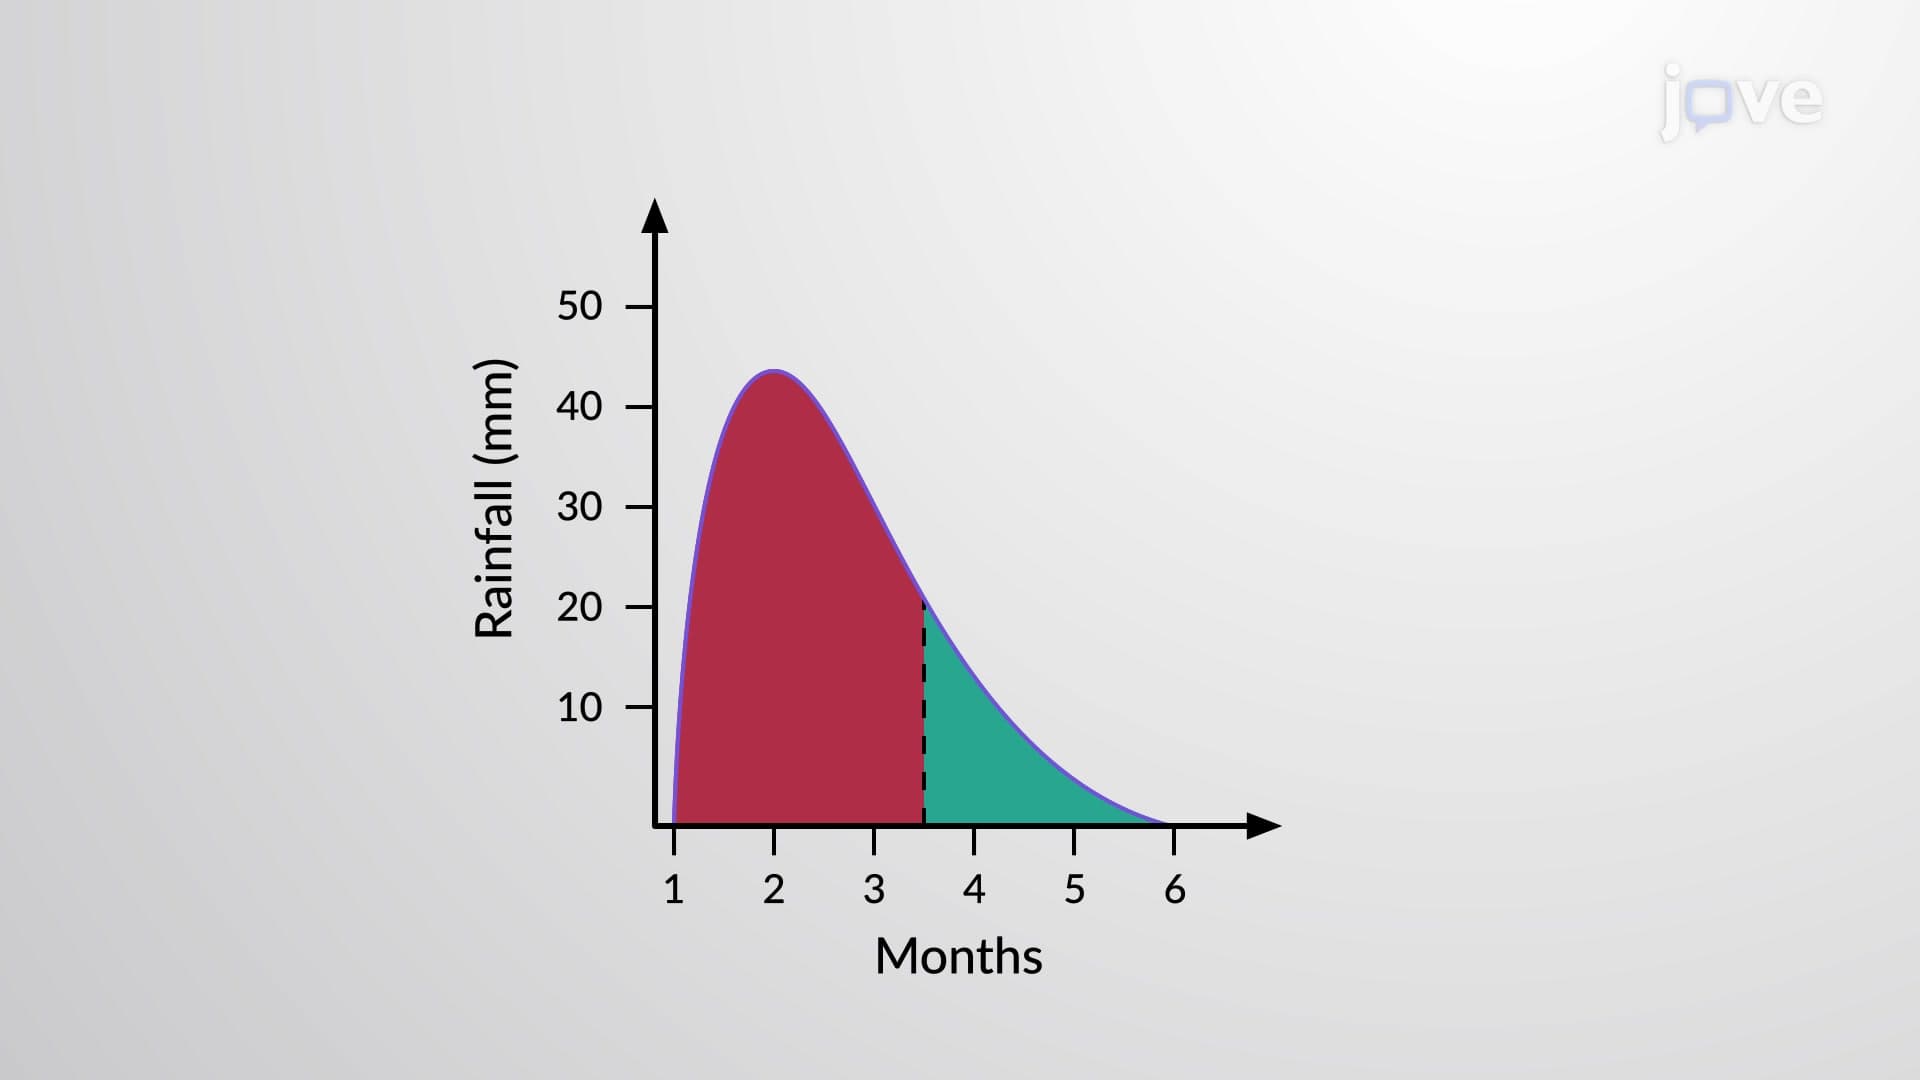
Skewness
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency are...
 01:19
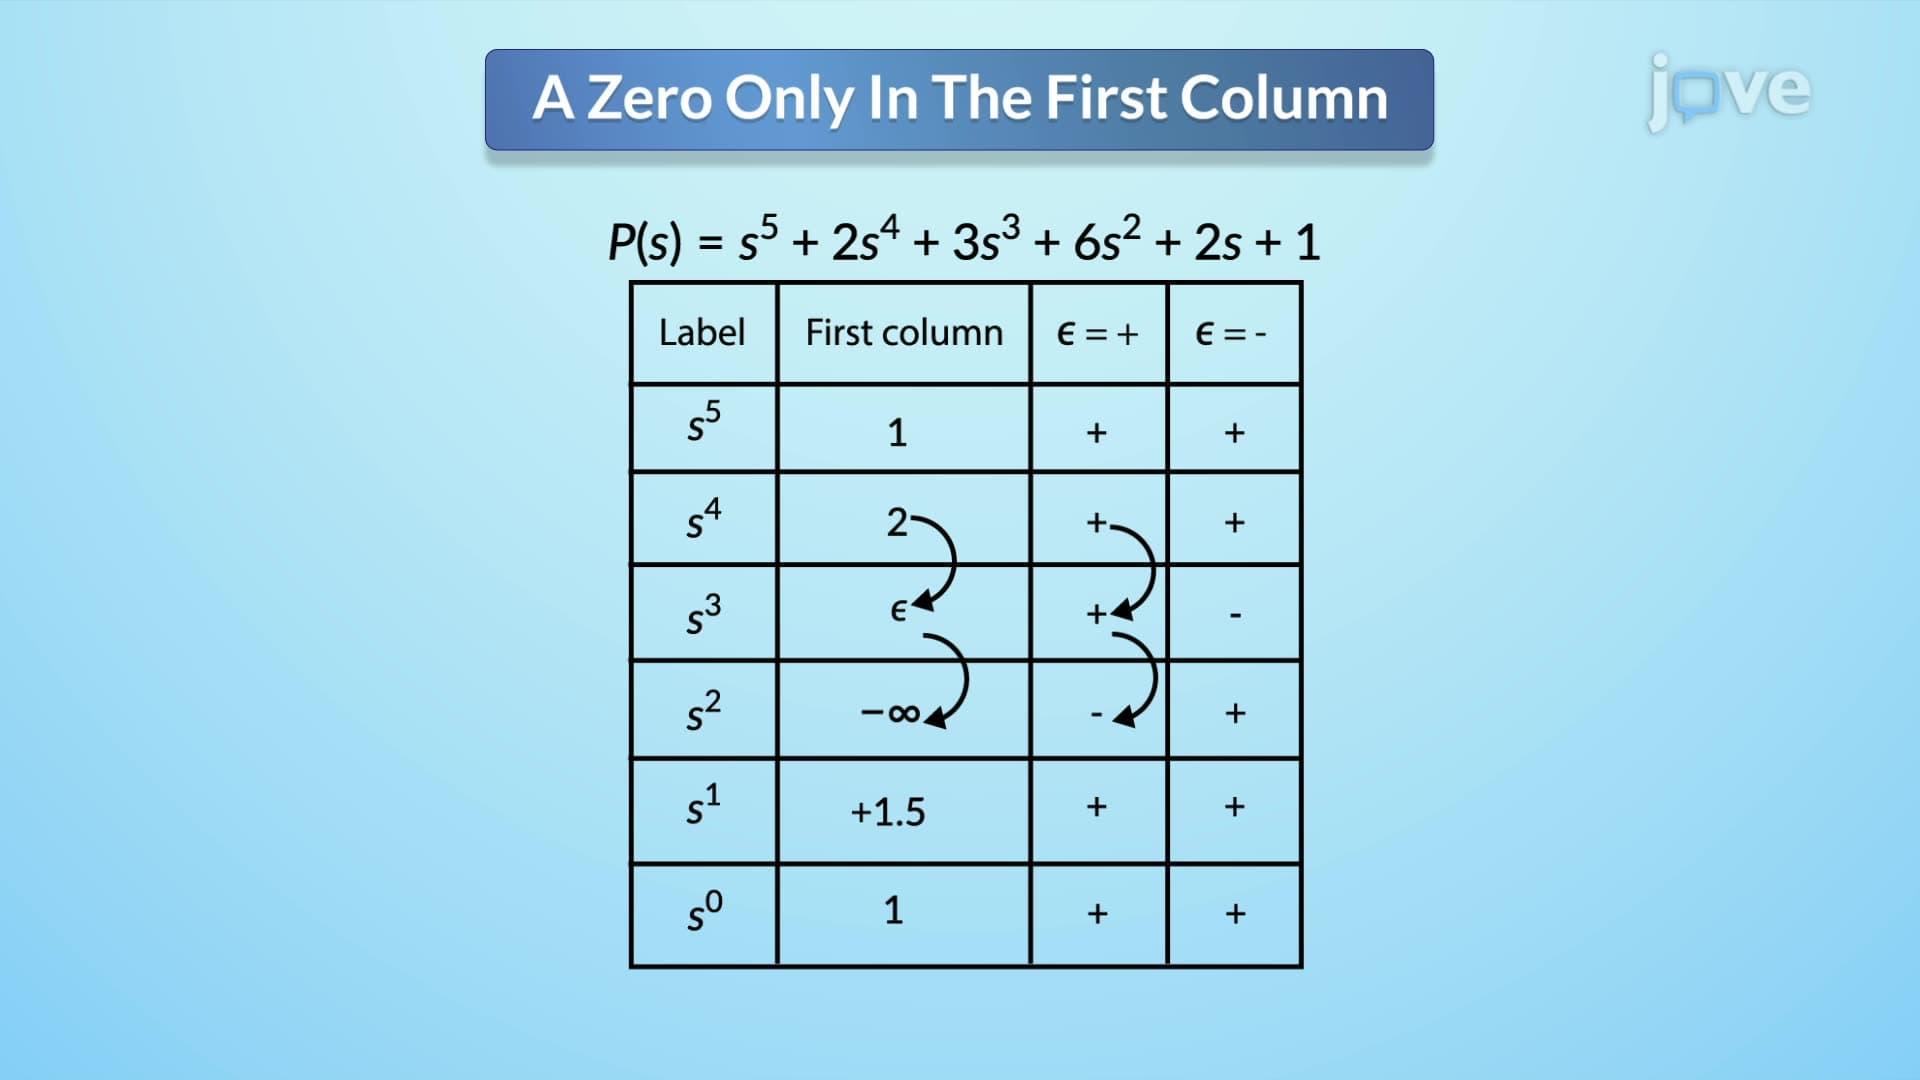
Routh-Hurwitz Criterion II
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first column of the Routh...