EvoSeq-ML: Advancing Data-Centric Machine Learning with Evolutionary-Informed Protein Sequence Representation and Generation
Related Experiment Video
Updated: Nov 4, 2026
An Integrated Approach for Microprotein Identification and Sequence Analysis
Published on: July 12, 2022
Mehrsa Mardikoraem1,2, Nathaniel Pascual1,2, Joelle N Eaves1,2
1Department of Chemical Engineering and Materials Science, Michigan State University, 428 S. Shaw Lane, East Lansing, MI 48824, United States.

Abstract:
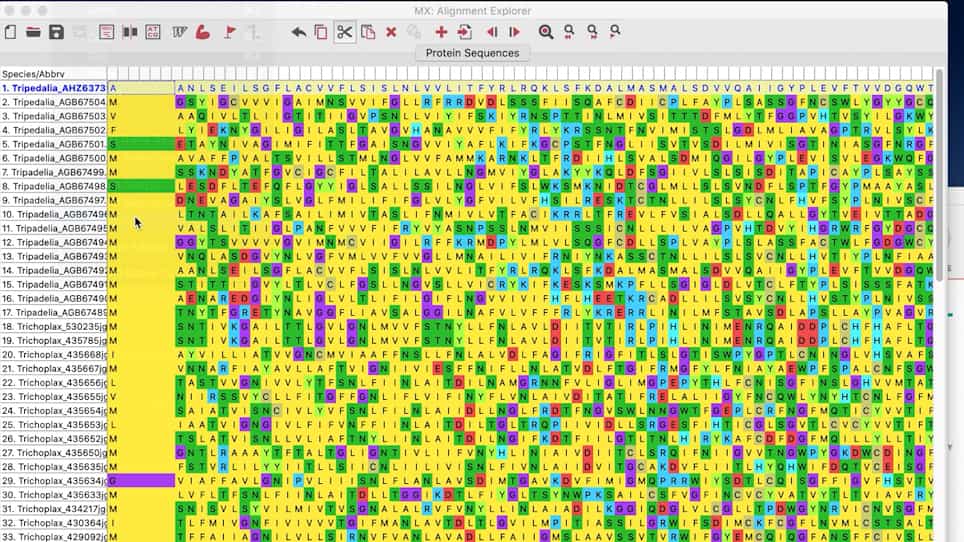
From protein structure prediction to novel protein generation, challenging protein engineering tasks have been made possible by advancements in machine learning (ML). While largely driven by ML architecture refinements, these advancements in ML-based protein engineering campaigns have left the impact of data curation underexplored. In light of the growing wealth of labeled sequence data, data-centric advances (e.g. prioritizing improvements in ML protein engineering tools through the curation of high-quality, domain-specific training data) are increasingly preferred over model-centric advancements. Implementing datasets that accurately reflect biological complexity and diversity has been shown to improve the efficiency of training protein engineering ML tools. Here, we evaluate an ancestral sequence reconstruction (ASR)-informed data augmentation strategy for training generative and representation-learning models in protein engineering. Using ethylene-forming enzyme (EFE) as a model system, we show that variational autoencoder models trained on ancestral and near-ancestral sequence datasets generate variants with improved predicted and experimentally measured thermostability relative to variants generated from modern-sequence training data. All experimentally tested ancestral and ML-generated EFEs produced detectable ethylene, although ML-generated variants showed reduced activity relative to wild-type EFE, indicating that the approach more strongly captured stability-associated features than catalytic optimization. We further evaluated ASR-enriched sequence sets for fine-tuning ESM2 representations in endolysin and lysozyme C stability-classification tasks, where ancestral representations were competitive with modern-sequence fine-tuning in selected settings. Overall, this work supports ASR-informed data augmentation as a promising strategy for stability-oriented protein sequence generation and motivates future work to couple ancestral sequence diversity with explicit functional selection.
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 01:08
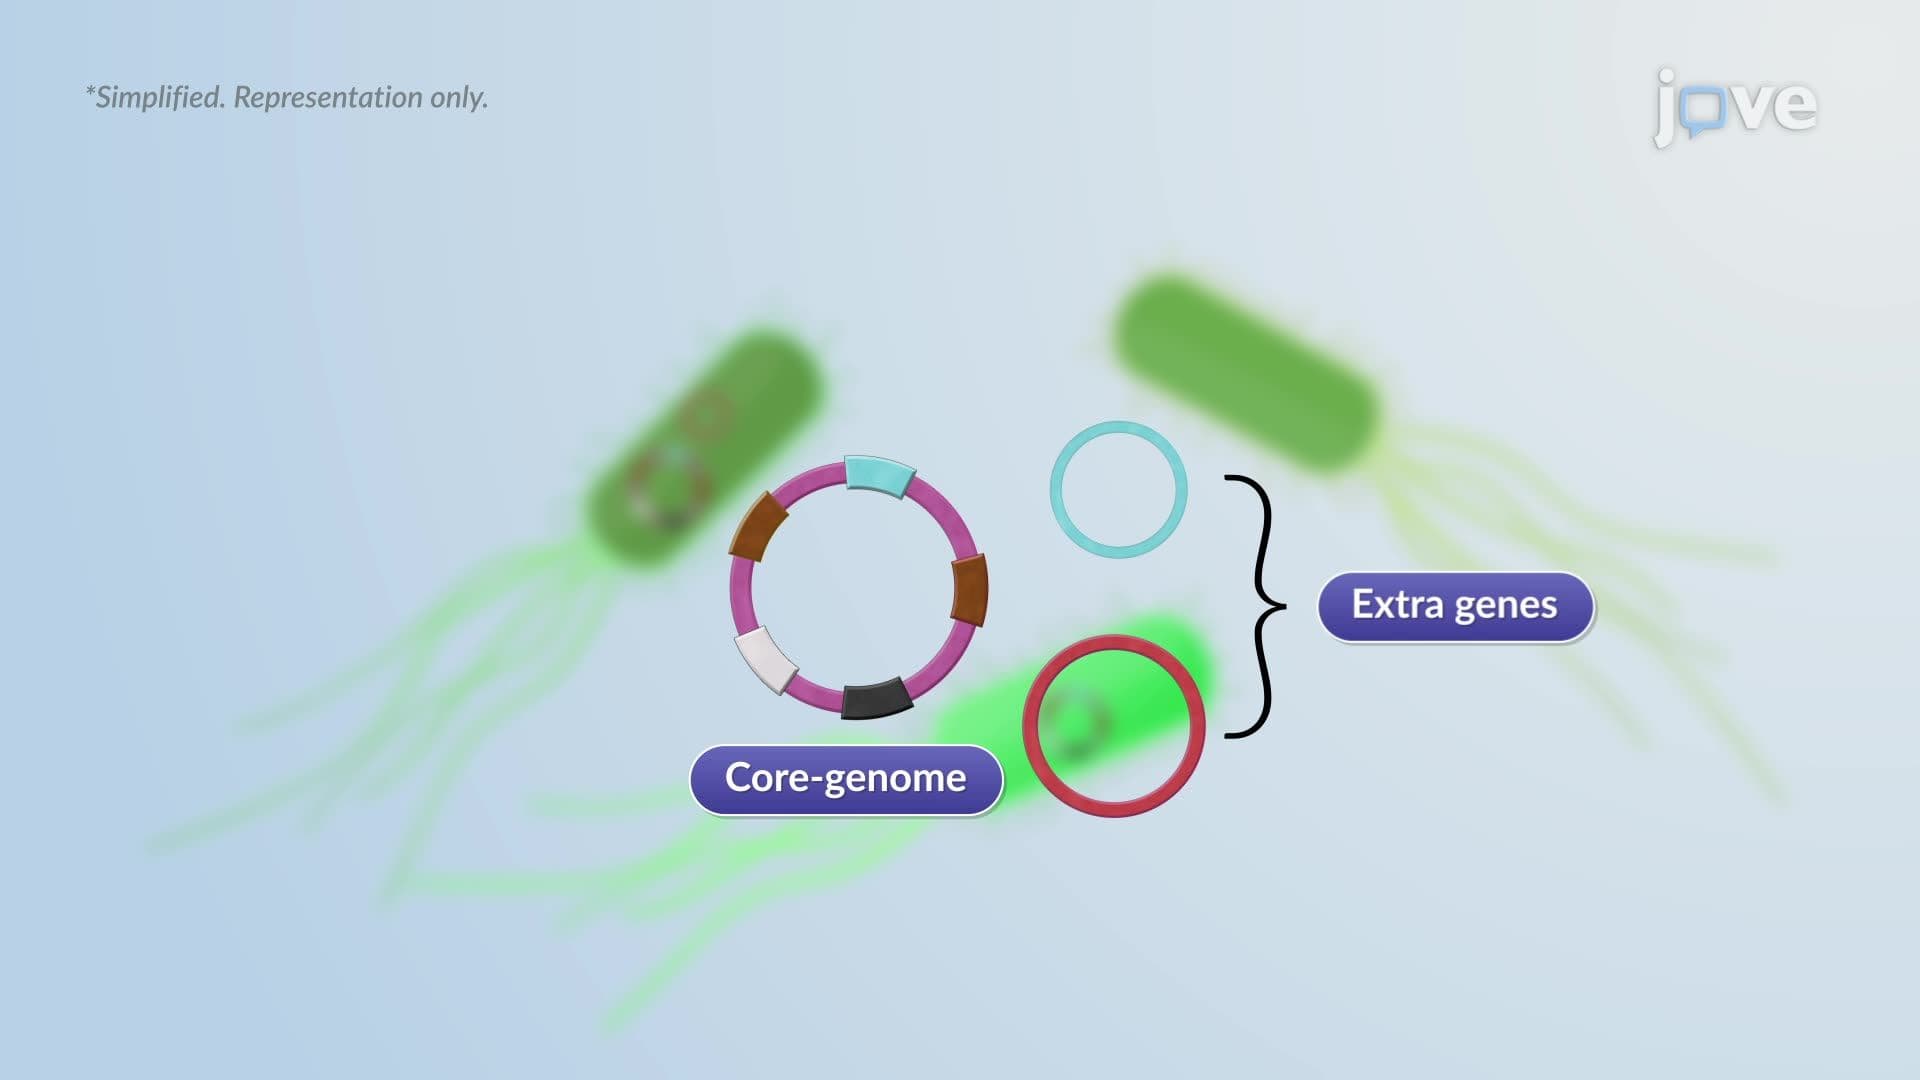
Evolution of Microbial Genome
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 02:05
Gene Evolution - Fast or Slow?
In contrast, regions which code...
02:05Gene Evolution - Fast or Slow?
In contrast, regions which code...
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features.