Distribution of combined p-values for baseline variables in a consecutive sample of randomized controlled trials
Related Experiment Video
Updated: Nov 9, 2026

Inverse Probability of Treatment Weighting (Propensity Score) using the Military Health System Data Repository and National Death Index
Published on: January 8, 2020
Rebecka Klang1, Louise Olsson2
1Centre for Assessment of Medical Technology in Örebro (Camtö), Faculty of Medicine and Health, Örebro University, Örebro, Sweden. rebecka.klang@oru.se.

Background:
Combined p-values derived from summary statistics of baseline variables in randomized controlled trials (RCTs) are expected to follow a uniform distribution. Extreme values indicate similarity or dissimilarity across randomized groups. To date, investigations have been limited to a small number of clinical fields; here, we assess the distribution of combined p-values in a consecutive sample of RCTs.
Methods:
Based on a PubMed search between February 1 and 18, 2022, 568 RCTs were included. Baseline variables were analysed using Carlisle's method, yielding one combined p-value per RCT. A threshold of combined p-values of p ≤ 0.05 or p ≥ 0.95 was applied. Differences in combined p-value distributions between subgroups were assessed using the two-sample Anderson-Darling (AD) test.
Results:
26.2% (149/568) of the included RCTs had combined p-values of p ≤ 0.05 or p ≥ 0.95, compared with the 10% expected by chance. Of these, 104 RCTs (18.3%) were found in the upper extreme tail of p ≥ 0.95 and 45 RCTs (7.9%) in the lower extreme tail of p ≤ 0.05. Smaller RCTs (N ≤ 100) had more extreme combined p-values than larger RCTs (N > 100) (AD test p = 0.001). RCTs with > 7 baseline variables had more extreme combined p-values than those with ≤ 7 variables (AD test p = 0.004). A sensitivity analysis showed that 20.6% of RCTs still had extreme combined p-values after controlling for reporting errors related to SE and SD. Another sensitivity analysis showed that some extreme results could be explained by assuming high correlations between baseline variables within an RCT.
Conclusion:
A substantially higher proportion of RCTs in a consecutive sample exhibited extreme similarities or dissimilarities in baseline characteristics across groups than expected by chance (26.2% vs 10%), indicating problems with randomisation. Further investigation into the causes and implications of implausible baseline distributions in RCTs is warranted.
Registered:
2023-03-20 at https://www.researchweb.org/fourol/project/280487.
Related Concept Videos
 01:13
Randomized Experiments
Simple randomization
Simple...
 01:23
Types of Biopharmaceutical Studies: Controlled and Non-Controlled Approaches
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast, controlled...
 01:10
Bonferroni Test
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
 01:24
Testing a Claim about Population Proportion
There are two methods of testing a claim about a population proportion: (1) Using the sample proportion from the data where a binomial distribution is approximated to the normal distribution and (2) Using the binomial probabilities calculated from the data.
The first method uses normal distribution as an approximation to the binomial distribution. The requirements are as follows: sample size is large...
 01:20
Bioequivalence Experimental Study Designs: Completely Randomized and Randomized Block Designs
 01:10
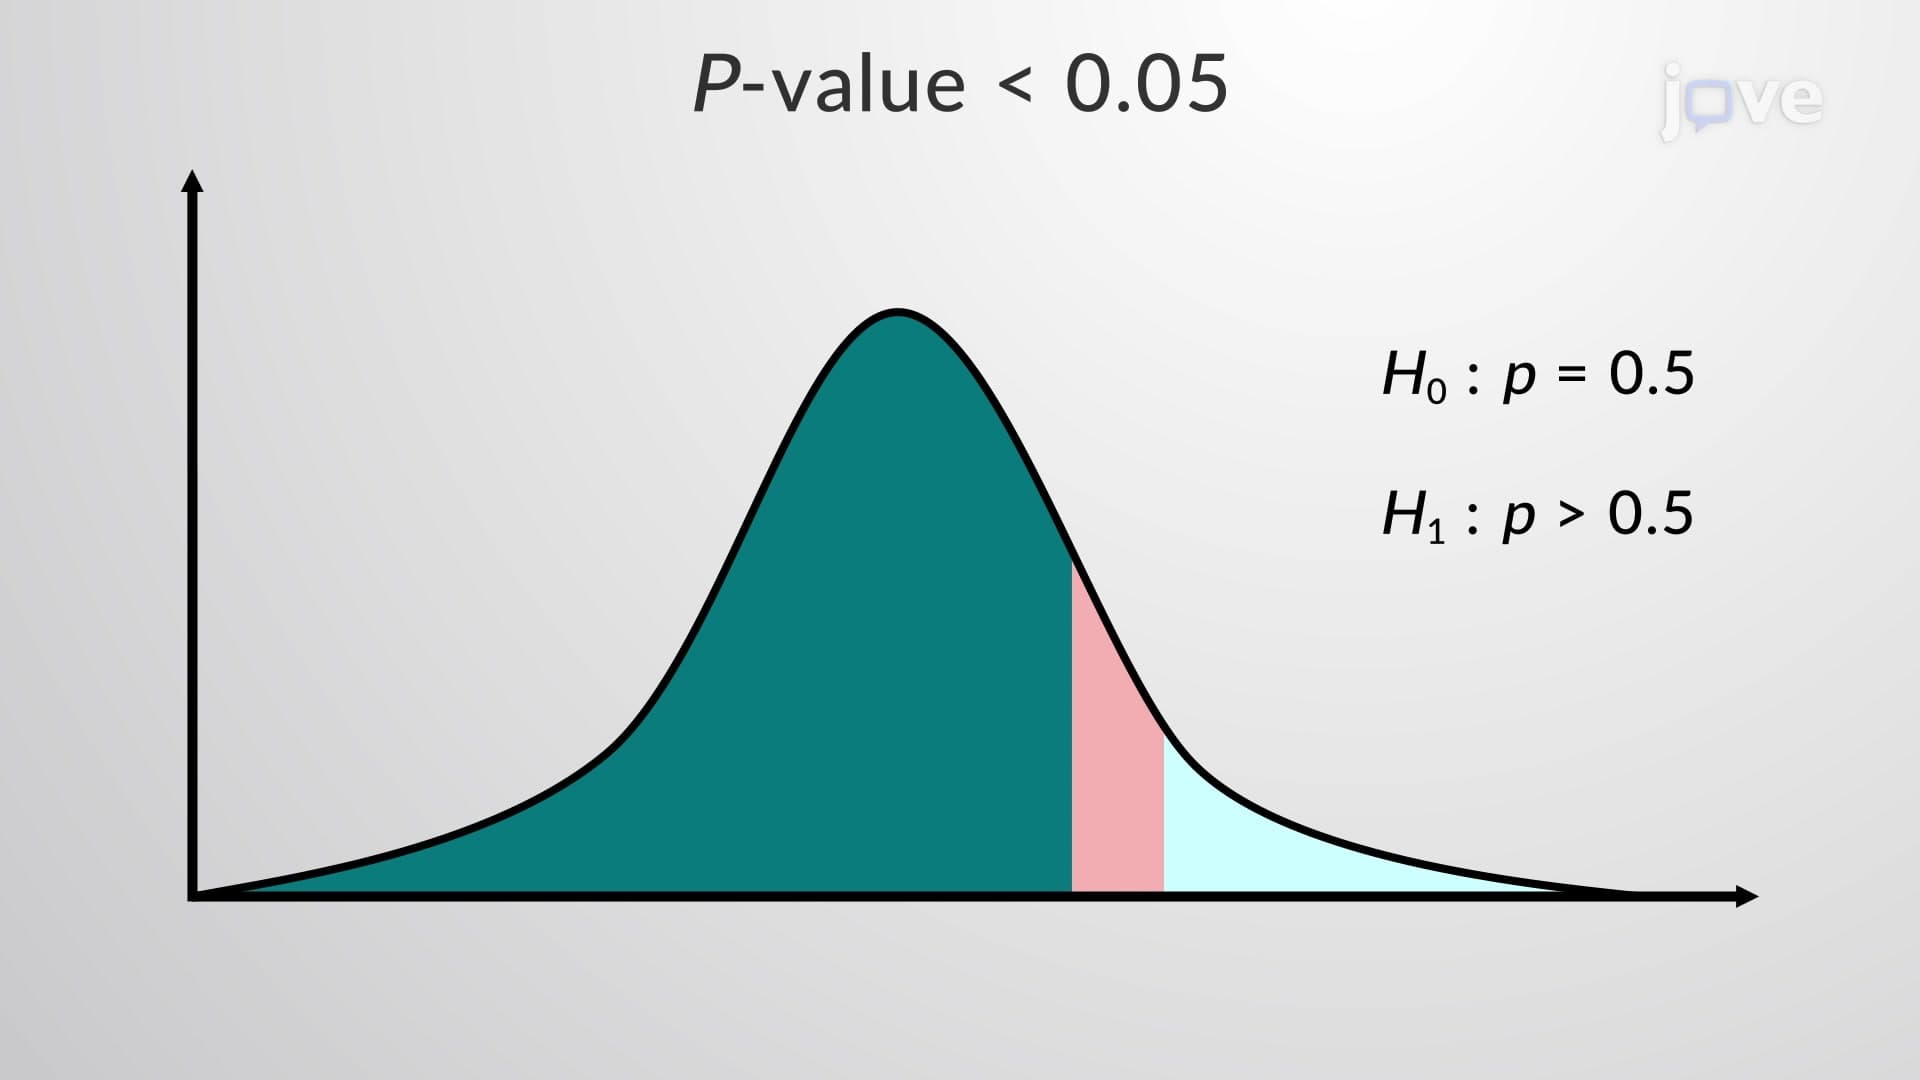
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more unlikely...