Benchmarking freely accessible large language models for pediatric epilepsy care: a prospective mixed-methods study
Related Experiment Video
Updated: Nov 9, 2026
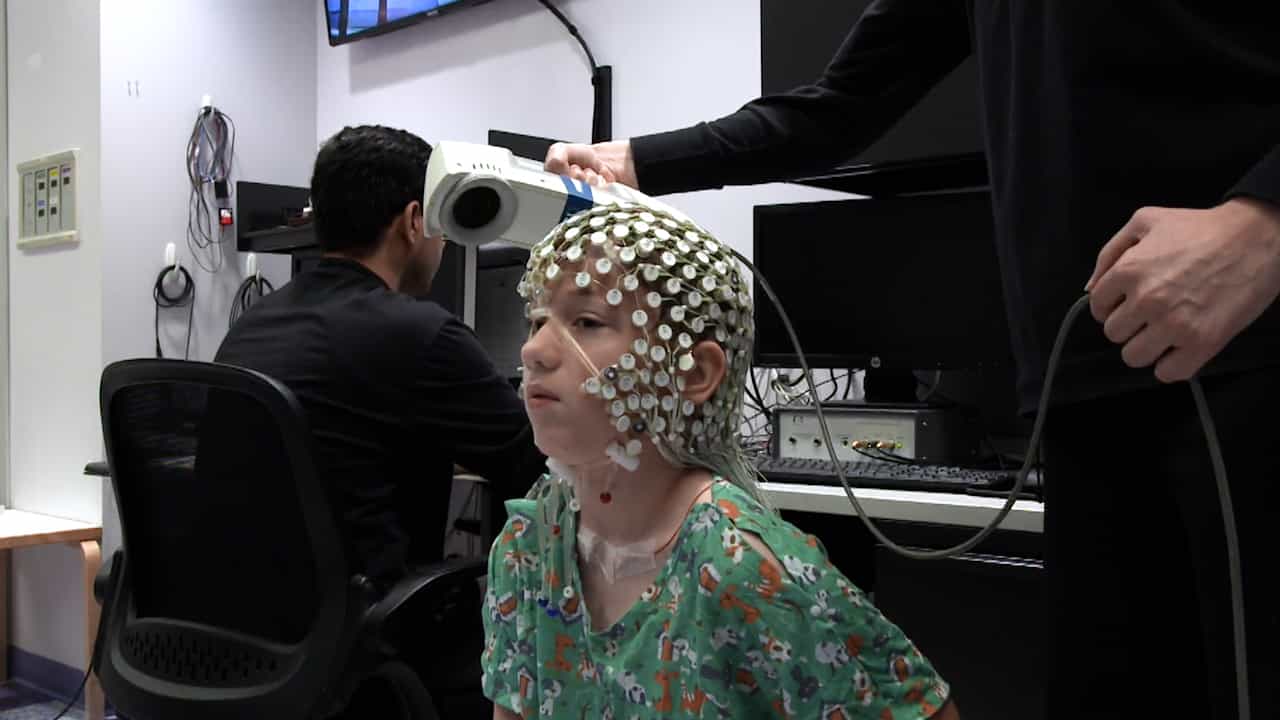
Electromagnetic Source Imaging in Presurgical Evaluation of Children with Drug-Resistant Epilepsy
Published on: September 20, 2024
Osama Muthaffar1, Anas Alyazidi2
1Pediatric Neurology Section, Department of Pediatrics, Faculty of Medicine, King Abdulaziz University, Jeddah, Saudi Arabia.

Background:
Large language models (LLMs) may support patient education and clinical documentation, but their accuracy, safety, and usability in pediatric epilepsy remain insufficiently characterized. This study aimed to compare four freely accessible LLMs using standardized pediatric epilepsy scenarios and to evaluate the top-performing model that met the prespecified safety criterion in a supervised clinician workflow assessment.
Methods:
We conducted a prospective, two-phase mixed-methods study at the University Hospital at King Abdulaziz University in Jeddah. In phase 1, four freely accessible LLMs (ChatGPT, Gemini, DeepSeek, and Perplexity) were evaluated using 10 standardized pediatric epilepsy scenarios. Outputs were assessed by pediatric neurologists across factual accuracy, comprehensiveness and relevance, safety, clinical appropriateness, readability and caregiver tailoring, and transparency and sources. Critical safety flags were recorded separately. In phase 2, the model with the highest observed composite score among systems meeting the prespecified safety criterion underwent a supervised clinician workflow assessment using the System Usability Scale (SUS), a caregiver-facing educational-material assessment, and semi-structured interviews.
Results:
Forty LLM responses were evaluated. Observed composite scores differed significantly across the four model-specific rater groups (P<0.001); however, because each model was evaluated exclusively by a single rater, the observed differences cannot be attributed to model effects independently of evaluator-specific scoring tendencies. DeepSeek and Gemini generated no critical safety flags, whereas ChatGPT had flags in 3/10 responses (30%) and Perplexity in 8/10 (80%). DeepSeek had the highest observed composite score (4.94/5), compared with 4.42/5 for Gemini, 3.59/5 for ChatGPT, and 2.05/5 for Perplexity, and was therefore selected for phase 2. Clinician approval for caregiver use was higher for responses without safety flags than for flagged responses (82.8% vs. 9.1%).
Conclusions:
In this specialty-specific benchmark, the evaluated LLMs showed substantial differences in observed accuracy and safety, with DeepSeek achieving the highest observed composite score and no critical safety flags. However, the single-rater-per-model design, small sample, model updates, and limited workflow assessment preclude definitive conclusions about comparative model superiority. These findings support specialty-specific evaluation of LLMs that prioritizes safety and clinical accuracy alongside usability. Larger, independently rated, multi-center studies with repeated model sampling and objective workflow and patient-centered outcomes are needed before routine clinical implementation can be considered.