Gaze-controlled segmentation improves object recognition accuracy in simulated phosphene vision
Related Experiment Video
Updated: Nov 12, 2026
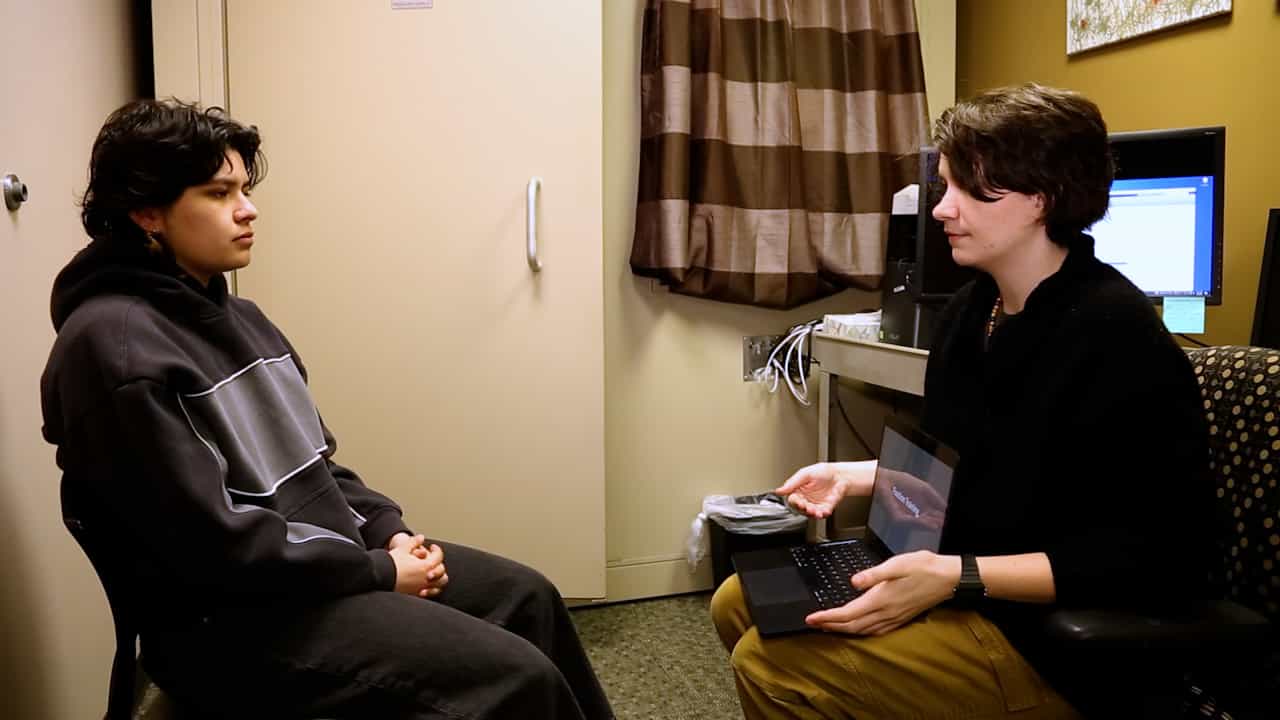
A Gaze-Contingent Display Framework for Perceptual Learning Research with Simulated Central Vision Loss
Published on: April 11, 2025
Eleftherios Papadopoulos1, Umut Güçlü2, Yağmur Güçlüturk3
1Radboud University Donders Institute for Brain Cognition and Behaviour, Thomas van Aquinostraat 4, Nijmegen, 6500 GL, Netherlands.

Objective:
Visual neuroprosthetics offer a promising solution, providing a simplified visual sense through devices comprising cameras, computers, and implanted electrodes. A central challenge is deciding what to convey with the few phosphenes available. We asked whether letting the user's gaze select the object that is conveyed in full, rather than extracting edges across the whole scene, improves object recognition in simulated phosphene vision. Approach. We developed Gaze-Controlled Segmentation (GCS), in which the point of gaze prompts the Segment Anything Model and the selected object is rendered as a filled region over the scene's edges at reduced intensity. In a simulated phosphene-vision environment, eight participants performed an object search-and-localization task under GCS, edge detection, and normal-vision conditions. Both phosphene conditions were rendered gaze-contingently, and the data were analysed with Bayesian mixed-effects models with participants and images as crossed random effects. Main results. Relative to edge detection, GCS produced a modest but credible improvement in identification accuracy on target-present trials (+9.4 percentage points, 95% highest-density interval [+4.3, +14.2]). Gaze reached the target about as often under both methods, consistent with an advantage at the identification stage. GCS trials tended to be slower (+2.7 s, [-0.8, +6.6]), a difference that was not credible, and in exploratory analyses the advantage was largest for cylindrical objects and absent for round ones. Stated preferences leaned toward GCS on most usability criteria, although with eight participants these tendencies are individually consistent with chance. Significance. The comparison is between the integrated GCS representation and edge rendering, and does not isolate the contribution of the segmentation itself. These findings illustrate the potential of gaze-driven, interactive scene representation for neuroprosthetic vision, while underscoring that the gain is modest, task-dependent, and established so far only in simulated phosphene vision with sighted observers, using phosphenes larger than current implants would produce. .

Related Concept Videos
 01:15
Depth Perception and Spatial Vision
 01:20
Parallel Processing
 01:26
Visual System
Once through the pupil, the light passes through the lens, a...