Audio large language models align with human neural responses during spoken-language comprehension
Related Experiment Video
Updated: Nov 12, 2026
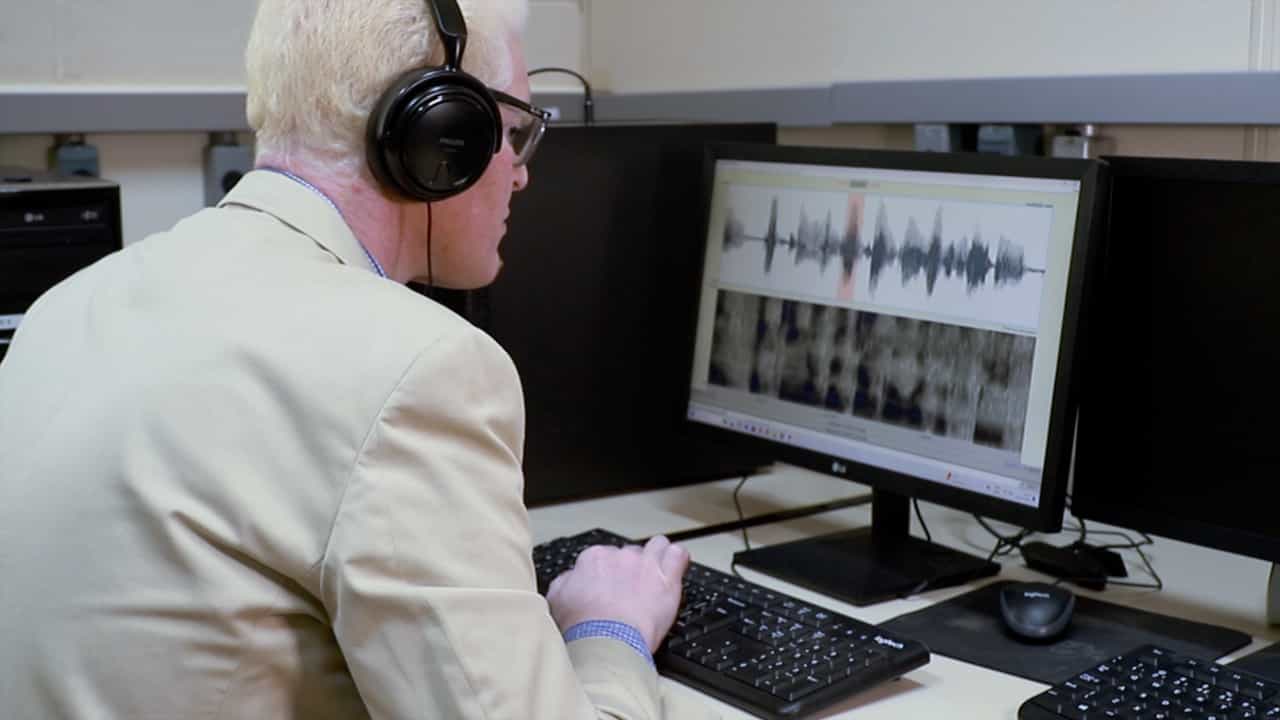
Foreign Accent and Forensic Speaker Identification in Voice Lineups: The Influence of Acoustic Features Based on Prosody
Published on: September 27, 2024
Shiyao Zhu1, Ao Chen2, Yanlu Xie1
1School of Information Science and Technology, Beijing Language and Culture University, 15 Xueyuan Road, Haidian District, Beijing 100083, China; Key Laboratory of the Cognitive Science of Language (Ministry of Education), Beijing Language and Culture University, 15 Xueyuan Road, Haidian District, Beijing 100083, China.

Abstract:
Audio large language models (audio LLMs) process continuous speech directly and transform it into progressively more abstract representations, providing a useful computational point of comparison with human spoken-language comprehension. Previous studies have reported model-brain correspondence for pretrained speech models and text-based language models, but it remains unclear which internal representations of audio LLMs are most closely associated with neural responses during online listening. We compared EEG responses from 41 native Mandarin listeners with internal representations from Qwen2-Audio, Qwen2.5-Omni, and Kimi-Audio in a Mandarin auditory semantic-violation paradigm that controlled sentence structure and event boundaries. We extracted speech-related and word-level semantic-update representations and quantified their incremental contributions to held-out EEG prediction beyond lower-level controls. Audio LLM representations improved EEG prediction beyond the acoustic envelope, phoneme onsets, and word onsets (Δr = 0.012, corrected P = 0.028). Prediction-score partitioning indicated that semantic violation primarily increased the overlap in EEG-predictive information between speech-related and semantic-update representations, rather than the unique contribution of either representation class. This pattern was relatively stable in Qwen2-Audio and Qwen2.5-Omni and directionally consistent, although statistically weaker, in Kimi-Audio. These findings provide component-level evidence that audio-conditioned model representations correspond to human neural responses during spoken-language comprehension, without implying mechanistic equivalence.
Related Concept Videos
 01:10
Higher Mental Functions of the Brain: Language
Language formation and comprehension take place in the dominant hemisphere. The dominant hemisphere is responsible for understanding the meaning of spoken, written, or sign language, as well as the ability to communicate. For most people, the left hemisphere is the dominant one. The right hemisphere, then, gives tone and emotional context to the...
 01:20
Perceiving Language Sounds and Structure During Infancy
 01:31
Hearing
 01:17
Auditory Perception
 01:21
Perceiving Loudness, Pitch, and Location
Place theory, or place coding, suggests that different pitches are heard because various sound waves activate specific locations along the cochlea's basilar membrane. The brain determines the pitch of a sound by identifying...
 01:29
Hearing During Infancy and Toddlerhood