Related Experiment Video
Updated: Aug 18, 2026

A Protocol for Comprehensive Assessment of Bulbar Dysfunction in Amyotrophic Lateral Sclerosis (ALS)
Published on: February 21, 2011
Speech synthesis by glottal excited linear prediction
1Department of Electrical Engineering, University of Florida, Gainesville 32611-2024.

Abstract:
This paper describes a linear predictive (LP) speech synthesis procedure that resynthesizes speech using a 6th-order polynomial waveform to model the glottal excitation. The coefficients of the polynomial model form a vector that represents the glottal excitation waveform for one pitch period. A glottal excitation code book with 32 entries for voiced excitation is designed and trained using two sentences spoken by different speakers. The purpose for using this approach is to demonstrate that quantization of the glottal excitation waveform does not significantly degrade the quality of speech synthesized with a glottal excitation linear predictive (GELP) synthesizer. This implementation of the LP synthesizer is patterned after both a pitch-excited LP speech synthesizer and a code excited linear predictive (CELP) speech coder. In addition to the glottal excitation codebook, we use a stochastic codebook with 256 entries for unvoiced noise excitation. Analysis techniques are described for constructing both codebooks. The GELP synthesizer, which resynthesizes speech with high quality, provides the speech scientist a simple speech synthesis procedure that uses established analysis techniques, that is able to reproduce all speed sounds, and yet also has an excitation model waveform that is related to the derivative of the glottal flow and the integral of the residue. It is conjectured that the glottal excitation codebook approach could provide a mechanism for quantitatively comparing the differences in glottal excitation codebooks for male and female speakers and for speakers with vocal disorders and for speakers with different voice types such as breathy and vocal fry voices. Conceivably, one could also convert the voice of a speaker with one voice type, e.g., breathy, to the voice of a speaker with another voice type, e.g., vocal fry, by synthesizing speech using the vocal tract LP parameters for the speaker with the breathy voice excited by the glottal excitation codebook trained for vocal fry.
Related Concept Videos
 01:21
Larynx
Anatomy of the Larynx
The larynx consists of various components, including cartilage, muscles, and vocal cords. Its structure includes three large unpaired cartilages—the thyroid, cricoid, and epiglottis—and three smaller paired cartilages—the arytenoids, corniculates, and...
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear.
 01:21
Linear Approximation in Time Domain
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length, the...
 01:26
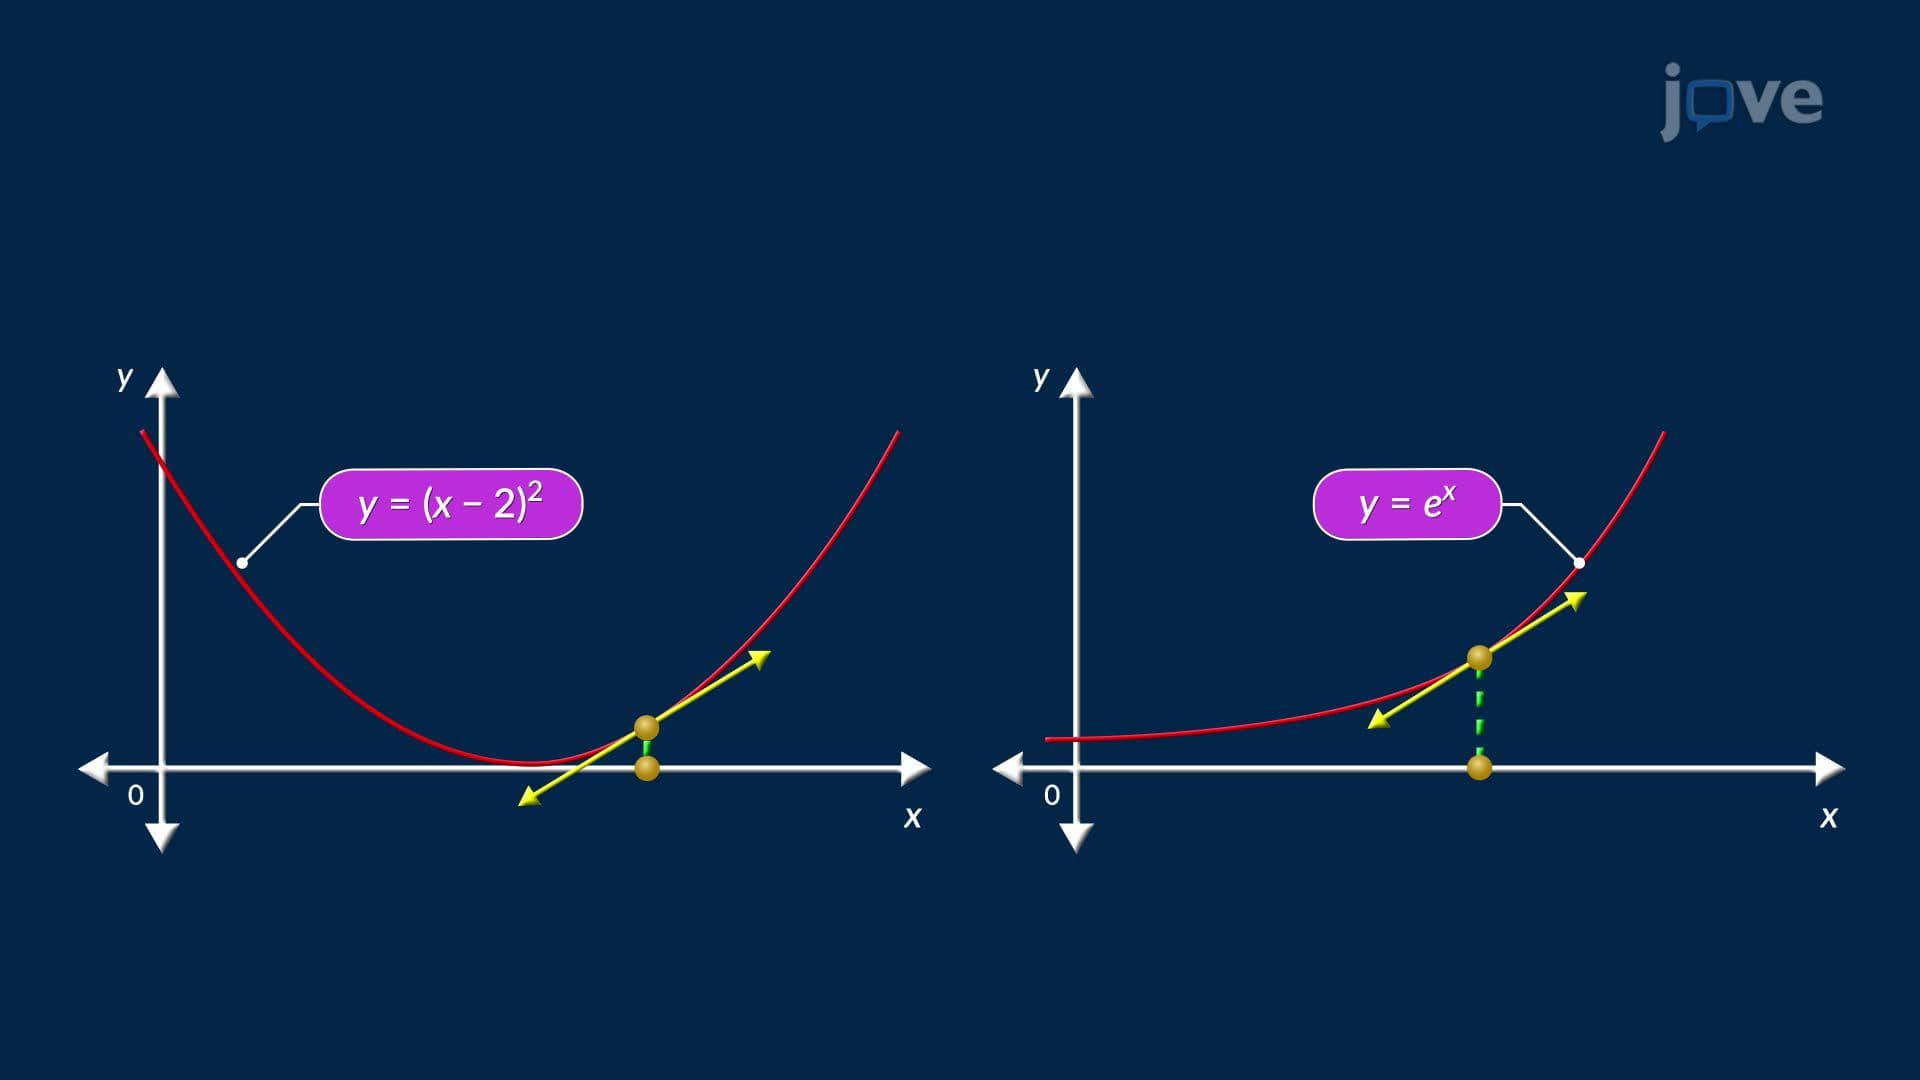
Linearization and Approximation
 01:29
Application of Linearization and Approximation
 01:23
Linear Approximations