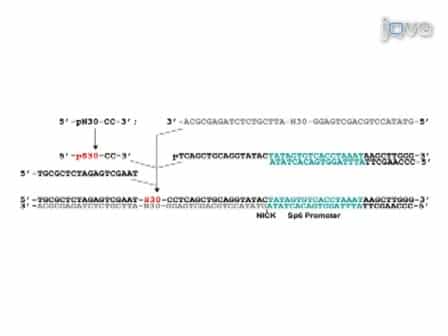
Selection of new biologically active molecules from random nucleotide sequences
Related Experiment Video
Updated: Nov 8, 2026
Biosensor-based High Throughput Biopanning and Bioinformatics Analysis Strategy for the Global Validation of Drug-protein Interactions
Published on: December 1, 2020
D K Dube1, M E Black, K M Munir
1Joseph Gottstein Memorial Cancer Research Laboratory, Department of Pathology, University of Washington, Seattle 98195.

Abstract:
Genetic diversity can be achieved in vitro by inserting random nucleotide (nt) sequences into cloned genes. In the case of enzymes, subsequent genetic complementation can be used to select for new mutants that exhibit different substrate specificities, altered catalytic activities, or altered temperature sensitivities. Using this technique, one can also analyze the contribution of different amino acid residues to the structure and function of enzyme. Selecting biologically active DNA sequences from large random populations provides a new method for identifying nt sequences with unique functions. Analogous random sequence selection techniques have been applied to determine the consensus sequence of the Escherichia coli promoters, DNA and RNA sequences that bind specific protein(s), DNA regulatory sequences, ribozyme(s) and ligand-specific RNA(s). In this manuscript, we will consider recent data obtained in our laboratory as a result of inserting random sequences into the putative nucleoside-binding site of herpes simplex virus type 1 (HSV-1) thymidine kinase (TK). We have obtained over 2000 new mutant HSV-1 TKs, some of which are stable at higher temperatures or have altered substrate specificity and/or catalytic rates when compared to those of the wild-type enzyme.