Related Experiment Video
Updated: Aug 15, 2026

Assessment of Immunologically Relevant Dynamic Tertiary Structural Features of the HIV-1 V3 Loop Crown R2 Sequence by ab initio Folding
Published on: September 16, 2010
Characterization of a DNA binding domain in the C-terminus of HIV-1 integrase by deletion mutagenesis
A M Woerner1, C J Marcus-Sekura
1Division of Viral Products, FDA, Bethesda, MD 20892.

Abstract:
The integrase (IN) protein of human immunodeficiency virus type 1 (HIV-1) catalyzes site-specific cleavage of 2 bases from the viral long terminal repeat (LTR) sequence yet it binds DNA with little DNA sequence specificity. We have previously demonstrated that the C-terminal half of IN (amino acids 154-288) possesses a DNA binding domain. In order to further characterize this region, a series of clones expressing truncated forms of IN as N-terminal fusion proteins in E.coli were constructed and analyzed by Southwestern blotting. Proteins containing amino acids 1-263, 1-248 and 170-288 retained the ability to bind DNA, whereas a protein containing amino acids 1-180 showed no detectable DNA binding. This defines a DNA binding domain contained within amino acids 180-248. This region contains an arrangement of 9 lysine and arginine residues each separated by 2-4 amino acids (KxxxKxxxKxxxxRxxxRxxRxxxxKxxxKxxxK), spanning amino acids 211-244, which is conserved in all HIV-1 isolates. A clone expressing full-length IN with a C-terminal fusion of 16 amino acids was able to bind DNA comparably to a cloned protein with a free C-terminus, and an IN-specific monoclonal antibody which recognizes an epitope contained within amino acids 264-279 was unable to block DNA binding, supporting the evidence that a region necessary for binding lies upstream of amino acid 264.
Related Concept Videos
 02:26
Conservation of Protein Domains Over Different Proteins
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:49
Conserved Binding Sites
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 01:19
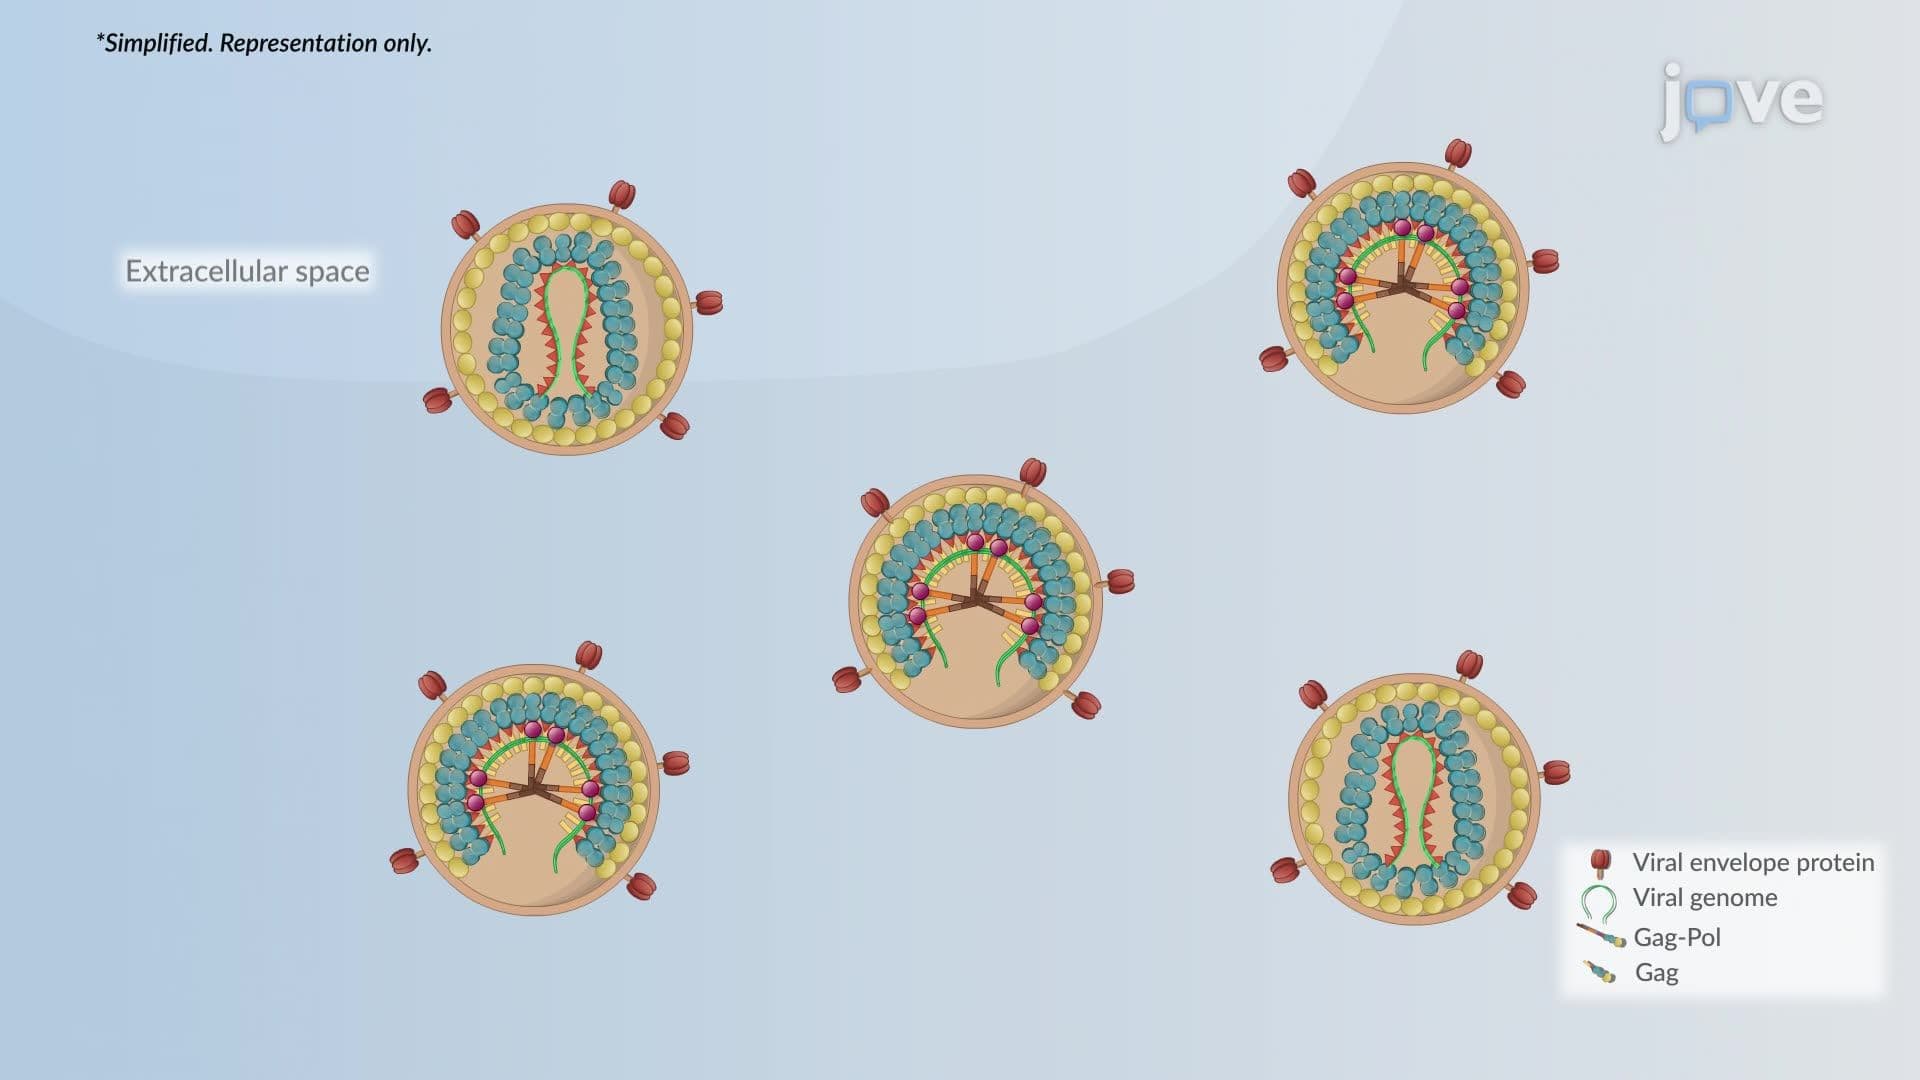
Inhibitors of Virion Maturation and Assembly