Related Experiment Video
Updated: Oct 1, 2026
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
On the covariance between parameter estimates in models of twin data
1Department of Medical and Molecular Genetics, Indiana University School of Medicine, Indianapolis 46202-5251.

Abstract:
We study the covariance between estimates of additive genetic variance and either dominance genetic variance or common environmental variance in likelihood-based twin analyses. The central tools used in these investigations are the asymptotic covariances of variance component estimates, which we present for several commonly used twin models. We first illustrate the use of the asymptotic covariance terms for determining the optimal ratio of monozygotic to dizygotic group sample sizes for a twin study. We then focus attention on the asymptotic correlations between estimates of additive genetic variance, and either dominance genetic variance or common environmental variance, and their use in understanding when parameters are efficiently estimable from twin data. The results of this investigation are confirmed by simulation studies, and highlight inherent limitations of the twin model, in the sense that having only twin data limits the ability to detect individual variance components. Finally, remarks on possible alternative statistical methods are given, and results are presented to illustrate the improvements in efficiency that are possible with additional family data. In particular, the results provide insight into the limitations of inference from twin data.

Related Concept Videos
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such as the mean,...
 01:26
Distributions to Estimate Population Parameter
 01:15
One-Way ANOVA: Equal Sample Sizes
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
 01:19
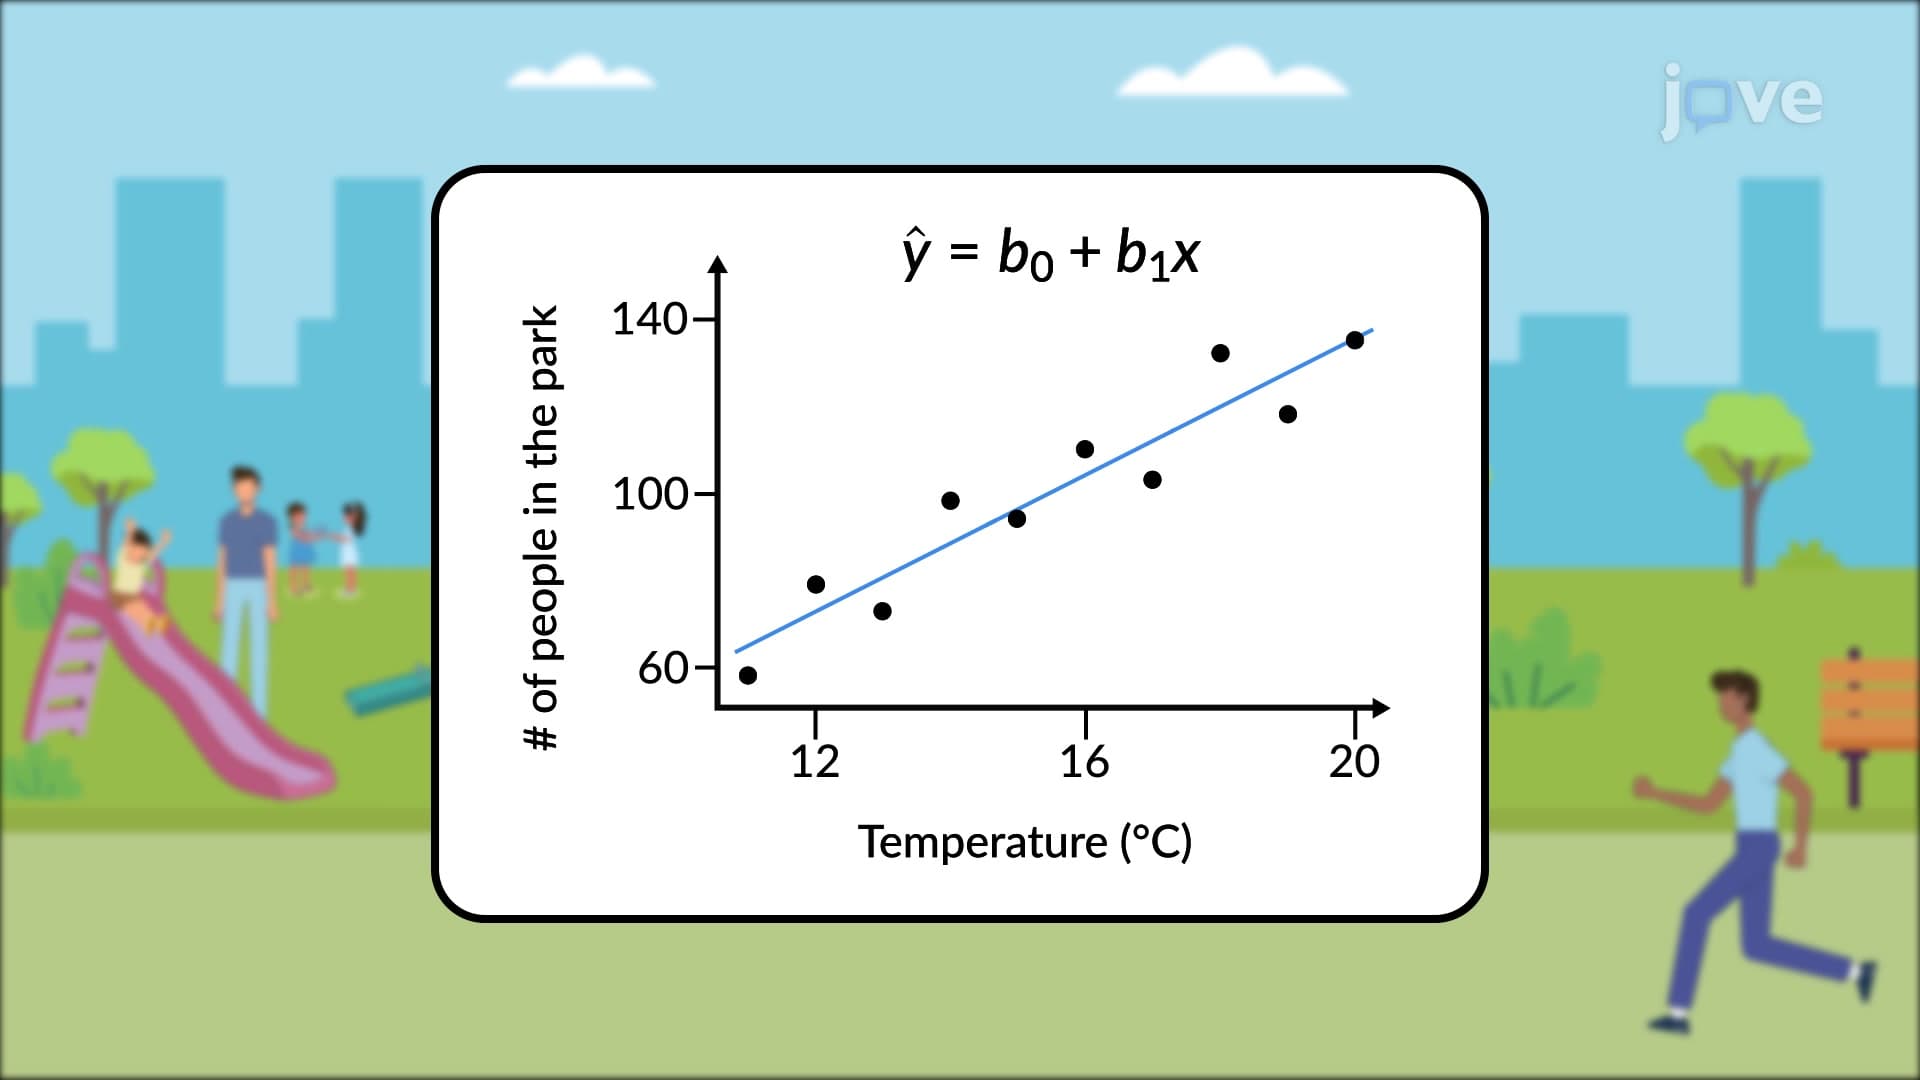
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:23
Correlation of Experimental Data
For example, a spherical particle moving through a viscous fluid experiences drag. Dimensional analysis shows that the drag force depends on the particle's diameter, velocity, and...