Bias in slope estimates for the linear errors in variables model by the variance ratio method
Related Experiment Video
Updated: Nov 3, 2026

Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
1Department of Environmental Health, University of Washington, Seattle 98195-4790, USA.

Abstract:
Slope estimates for linear measurement error (errors in variables) models based on assumed knowledge of the ratio of measurement error variances are biased if the underlying linear relationship is anything other than a completely deterministic, law-like relationship. This paper describes an eight-parameter linear measurement error model of general applicability that includes an optional "errors in equations" term (Malinvaud, E., 1980, Statistical Methods of Econometrics) that allows the explicit characterization of the asymptotic bias of such slope estimates when the assumption of a law-like relationship does not hold. This bias may be large, underscoring the importance of recognizing the potential influence of errors in equations in measurement error models.
Related Concept Videos
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:15
One-Way ANOVA: Equal Sample Sizes
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
 01:29
Bias in Epidemiological Studies
 01:15
Systematic Error: Methodological and Sampling Errors
Sampling errors originate from improper sampling methods or the wrong sample population. These errors can be minimized by refining the sampling strategy. Defective instruments or faulty calibrations are the sources of instrumental...
 01:11
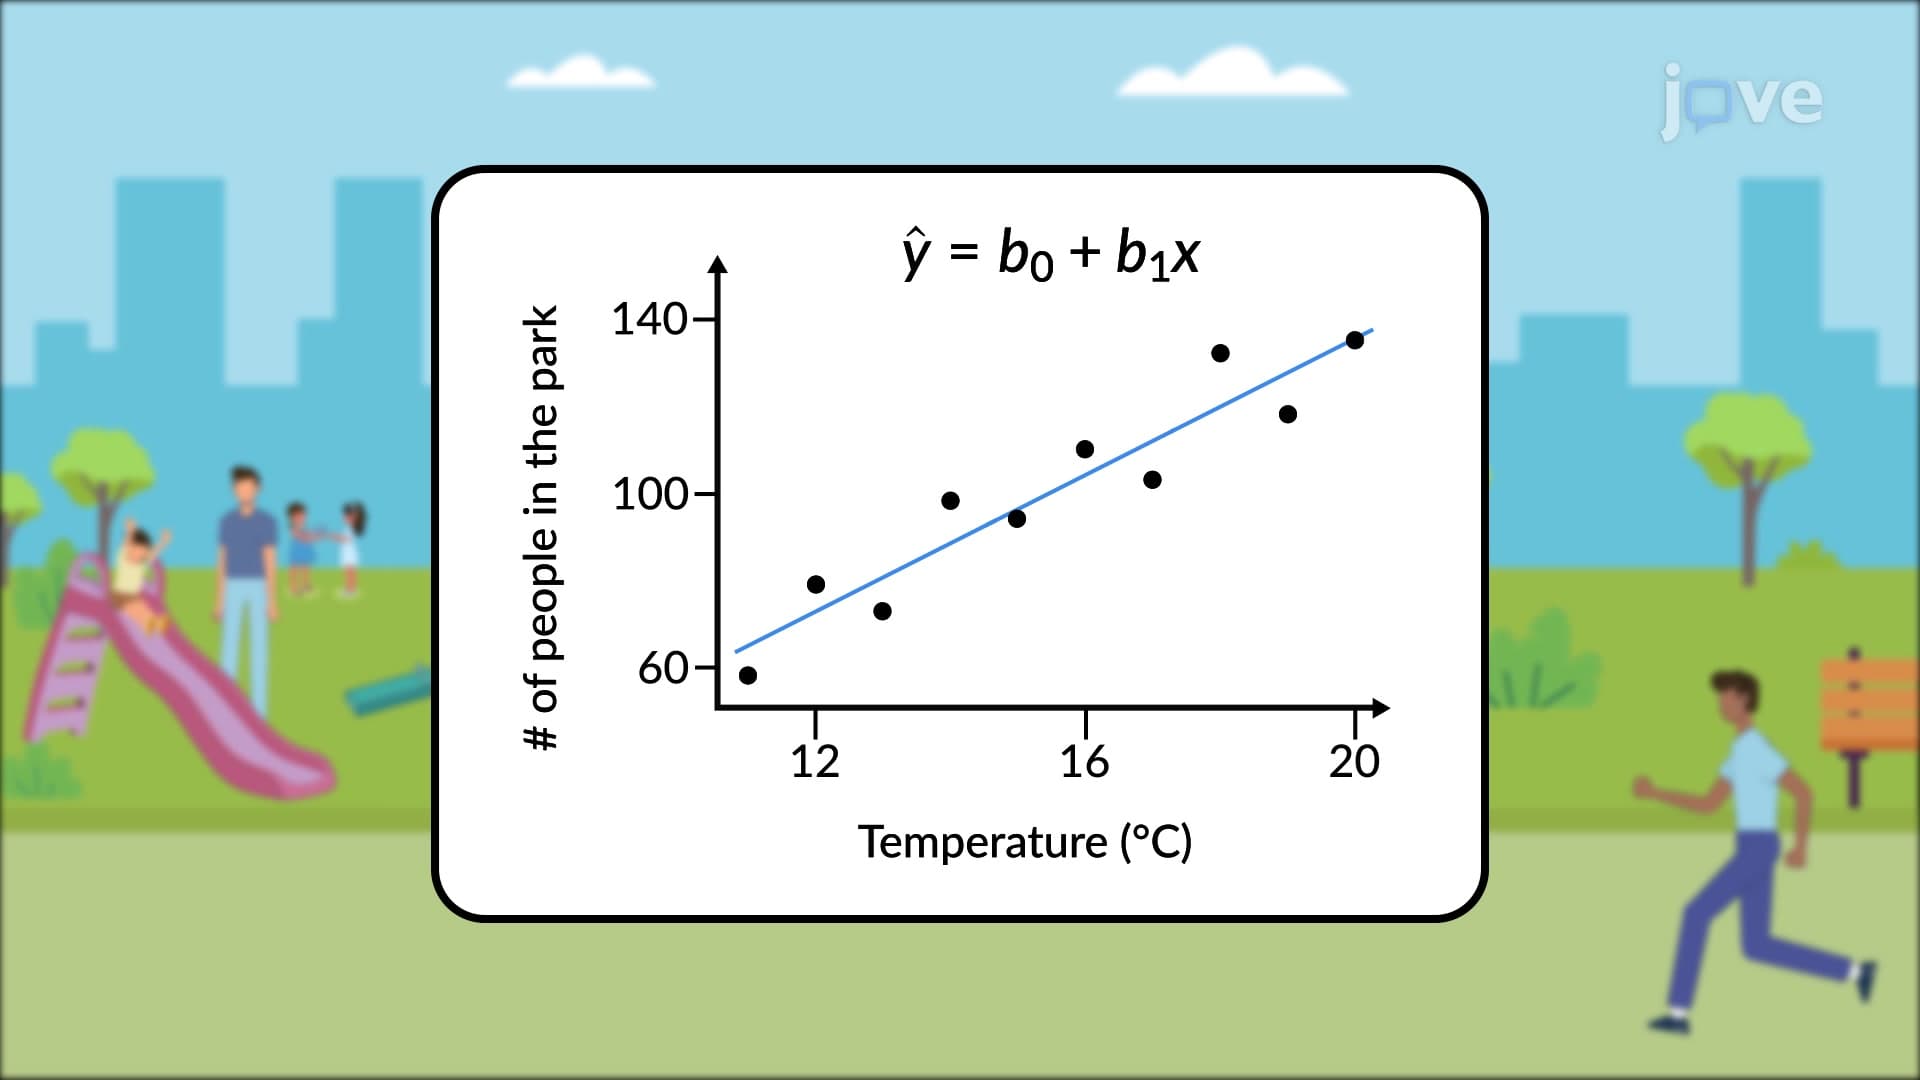
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as: