Between- and within-cluster covariate effects in the analysis of clustered data
Related Experiment Video
Updated: Oct 29, 2026
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
1Department of Epidemiology and Biostatistics, University of California, San Francisco 94143-0560, USA. john@biostat.ucsf.edu

Abstract:
Standard methods for the regression analysis of clustered data postulate models relating covariates to the response without regard to between- and within-cluster covariate effects. Implicit in these analyses is the assumption that these effects are identical. Example data show that this is frequently not the case and that analyses that ignore differential between- and within-cluster covariate effects can be misleading. Consideration of between- and within-cluster effects also helps to explain observed and theoretical differences between mixture model analyses and those based on conditional likelihood methods. In particular, we show that conditional likelihood methods estimate purely within-cluster covariate effects, whereas mixture model approaches estimate a weighted average of between- and within-cluster covariate effects.
Related Concept Videos
 01:17
Two-Way ANOVA
The two-way ANOVA analysis initially begins by stating the null hypothesis that there is an interaction effect between the two factors of a dataset. This effect can be visualized using line segments formed by joining the means for...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:20
Comparing the Survival Analysis of Two or More Groups
 01:18
One-Way ANOVA
 01:15
One-Way ANOVA: Unequal Sample Sizes
 01:12
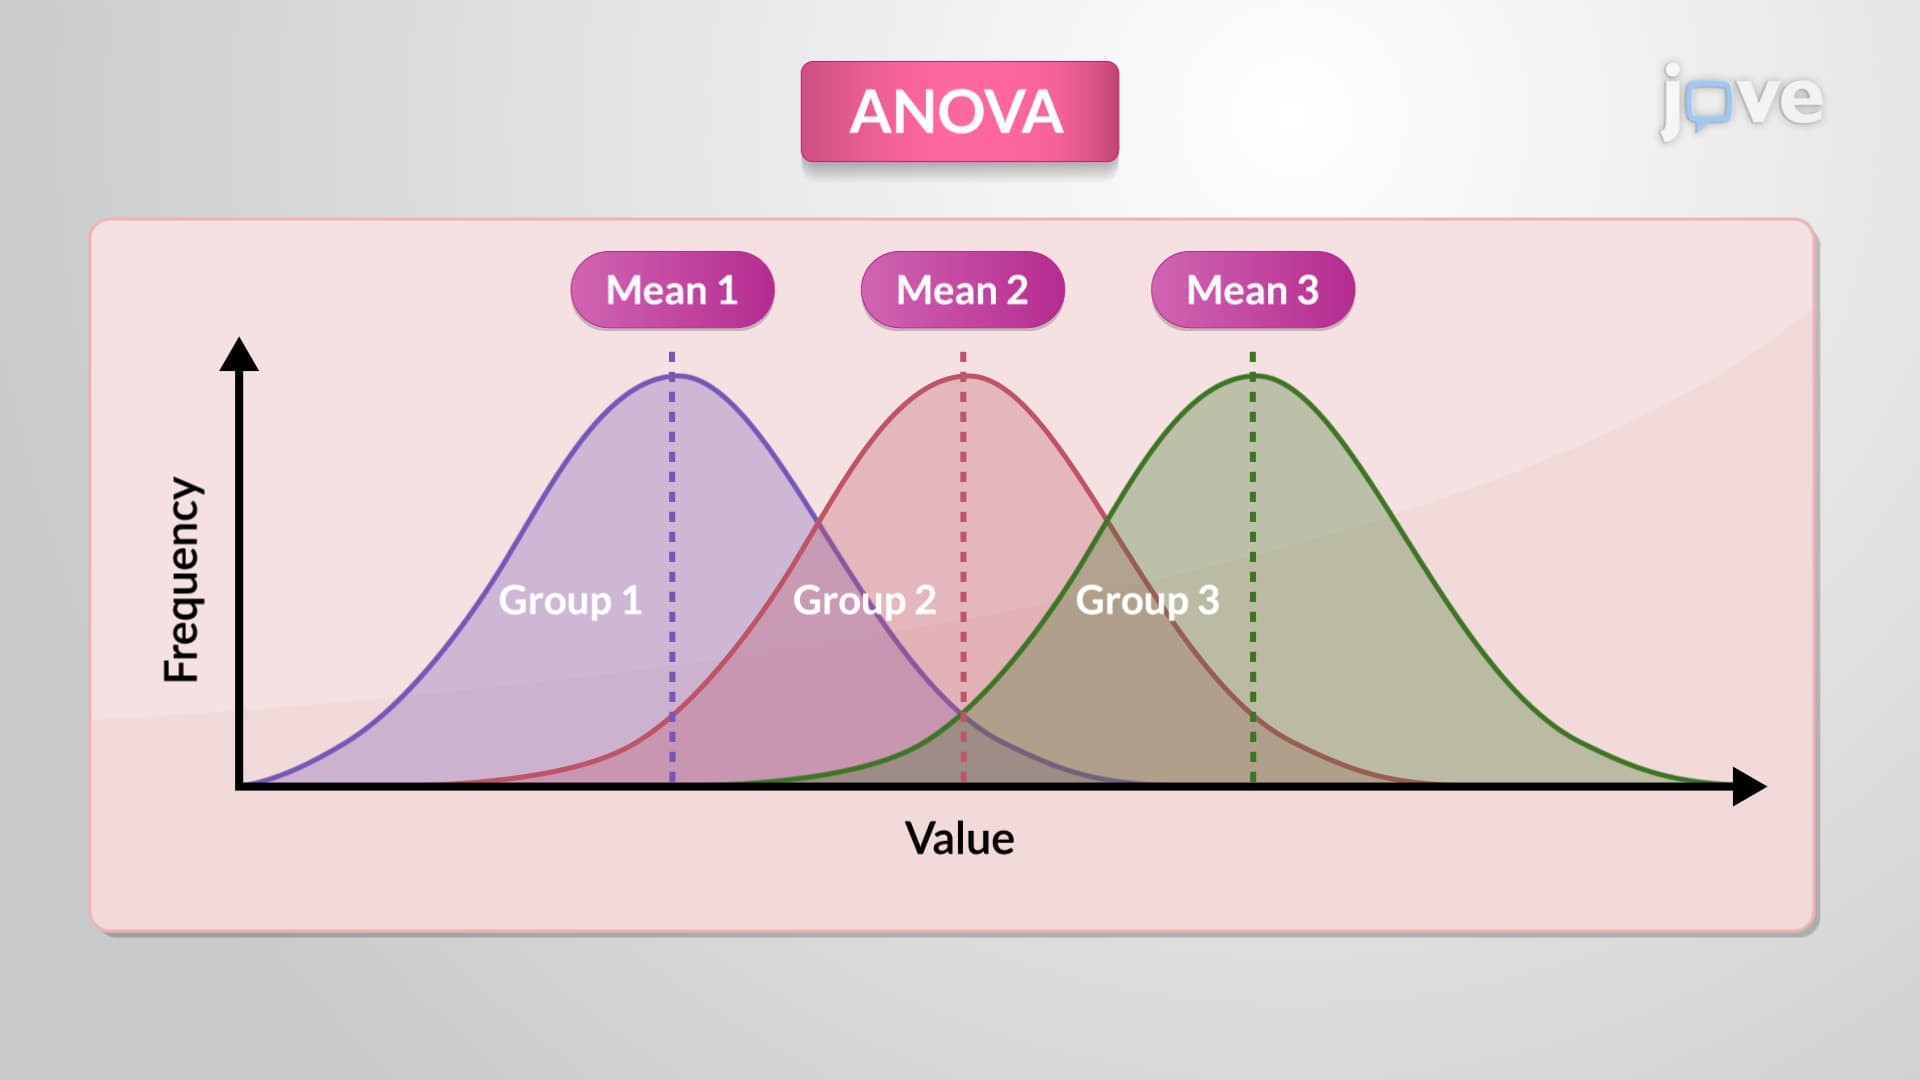
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares the...