
ランダム化試験におけるアウトカムの選択的な報告のための経験的証拠:プロトコルと出版された論文の比較
An-Wen Chan1, Asbjørn Hróbjartsson, Mette T Haahr
1Centre for Statistics in Medicine, Institute of Health Sciences, Headington, Oxford, England. anwen.chan@utoronto.ca
JAMA
|May 27, 2004

まとめ
ランダム化試験における選択的結果報告は一般的であり,有意な結果は完全に報告される可能性が高い. このバイアスは,公表された研究を信頼できないものにして,試験の登録と透明性のための公共プロトコルが必要になります.
科学分野:
- 臨床研究の方法論 臨床研究の方法論
- バイオ統計学 バイオ統計学
- 根拠に基づいた医学は,エビデンスに基づいた医療です.
背景:
- 選択的結果報告のバイアスが疑われるが,ケースレポートを超えた強力な経験的証拠がない.
- ランダム化試験におけるこのバイアスの程度と性質に関するデータは限られている.
研究 の 目的:
- ランダム化試験のコホートにおける結果報告バイアスの有病率と特徴を実証的に調査する.
- 報告された結果と報告されていない結果の差異と,統計的有意性との関係性を評価する.
主な方法:
- コホート研究では,102件のランダム化試験 (1994年~1995年) を分析し,プロトコルと公表された報告書を比較し,試験参加者を調査した.
- 出版物でメタアナリシスに必要なデータが不十分である場合には,アウトカムが不完全と分類された.
- 確率比は,統計的有意性およびプライマリアウトカム報告の一貫性に関連するバイアスを定量化するために計算されました.
主要な成果:
- 50%の有効性と65%の有害性の結果は,試験全体で不完全に報告されました.
- 統計的に有意なアウトカムが非有意なアウトカムよりも完全に報告される可能性が著しく高かった (ORsは有効性に対して2.4,有害性に対して4.7).
- 62%の試験では,プロトコルと出版物間の主要なアウトカムにおける不一致が示され,多くの試験参加者は報告されていないアウトカムを否定しました.
結論:
- ランダム化試験における結果報告は,しばしば不完全であり,偏っており,初期プロトコルと矛盾しています.
- 公開された研究は,この報告バイアスのために,介入の利点を過大評価することがあります.
- 治験の登録とプロトコルの公開は,透明性と信頼性を高めるために不可欠です.
関連する概念動画
 01:37
Statistical Significance
Once data is collected from both the experimental and the control groups, a statistical analysis is conducted to find out if there are meaningful differences between the two groups. A statistical analysis determines how likely any difference found is due to chance (and thus not meaningful). In psychology, group differences are considered meaningful, or significant, if the odds that these differences occurred by chance alone are 5 percent or less. Stated another way, if we repeated this...
 02:46
Chi-square Analysis
The chi-square test is a statistical hypothesis test. It is used to check whether there is a significant difference between an expected value and an observed value. In the context of genetics, it enables us to either accept or reject a hypothesis, based on how much the observed values deviate from the expected values.
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
 01:20
Random and Systematic Errors
Scientists always try their best to record measurements with the utmost accuracy and precision. However, sometimes errors do occur. These errors can be random or systematic. Random errors are observed due to the inconsistency or fluctuation in the measurement process, or variations in the quantity itself that is being measured. Such errors fluctuate from being greater than or less than the true value in repeated measurements. Consider a scientist measuring the length of an earthworm using a...
 01:13
Randomized Experiments
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
 01:04
Significance Testing: Overview
Significance testing is a set of statistical methods used to test whether a claim about a parameter is valid. In analytical chemistry, significance testing is used primarily to determine whether the difference between two values comes from determinate or random errors. The effect of a particular change in the measurement protocol, analyst, or sample itself can cause a deviation from the expected result. In the case of a suspected deviation/outlier, we need to be able to confirm mathematically...
 01:14
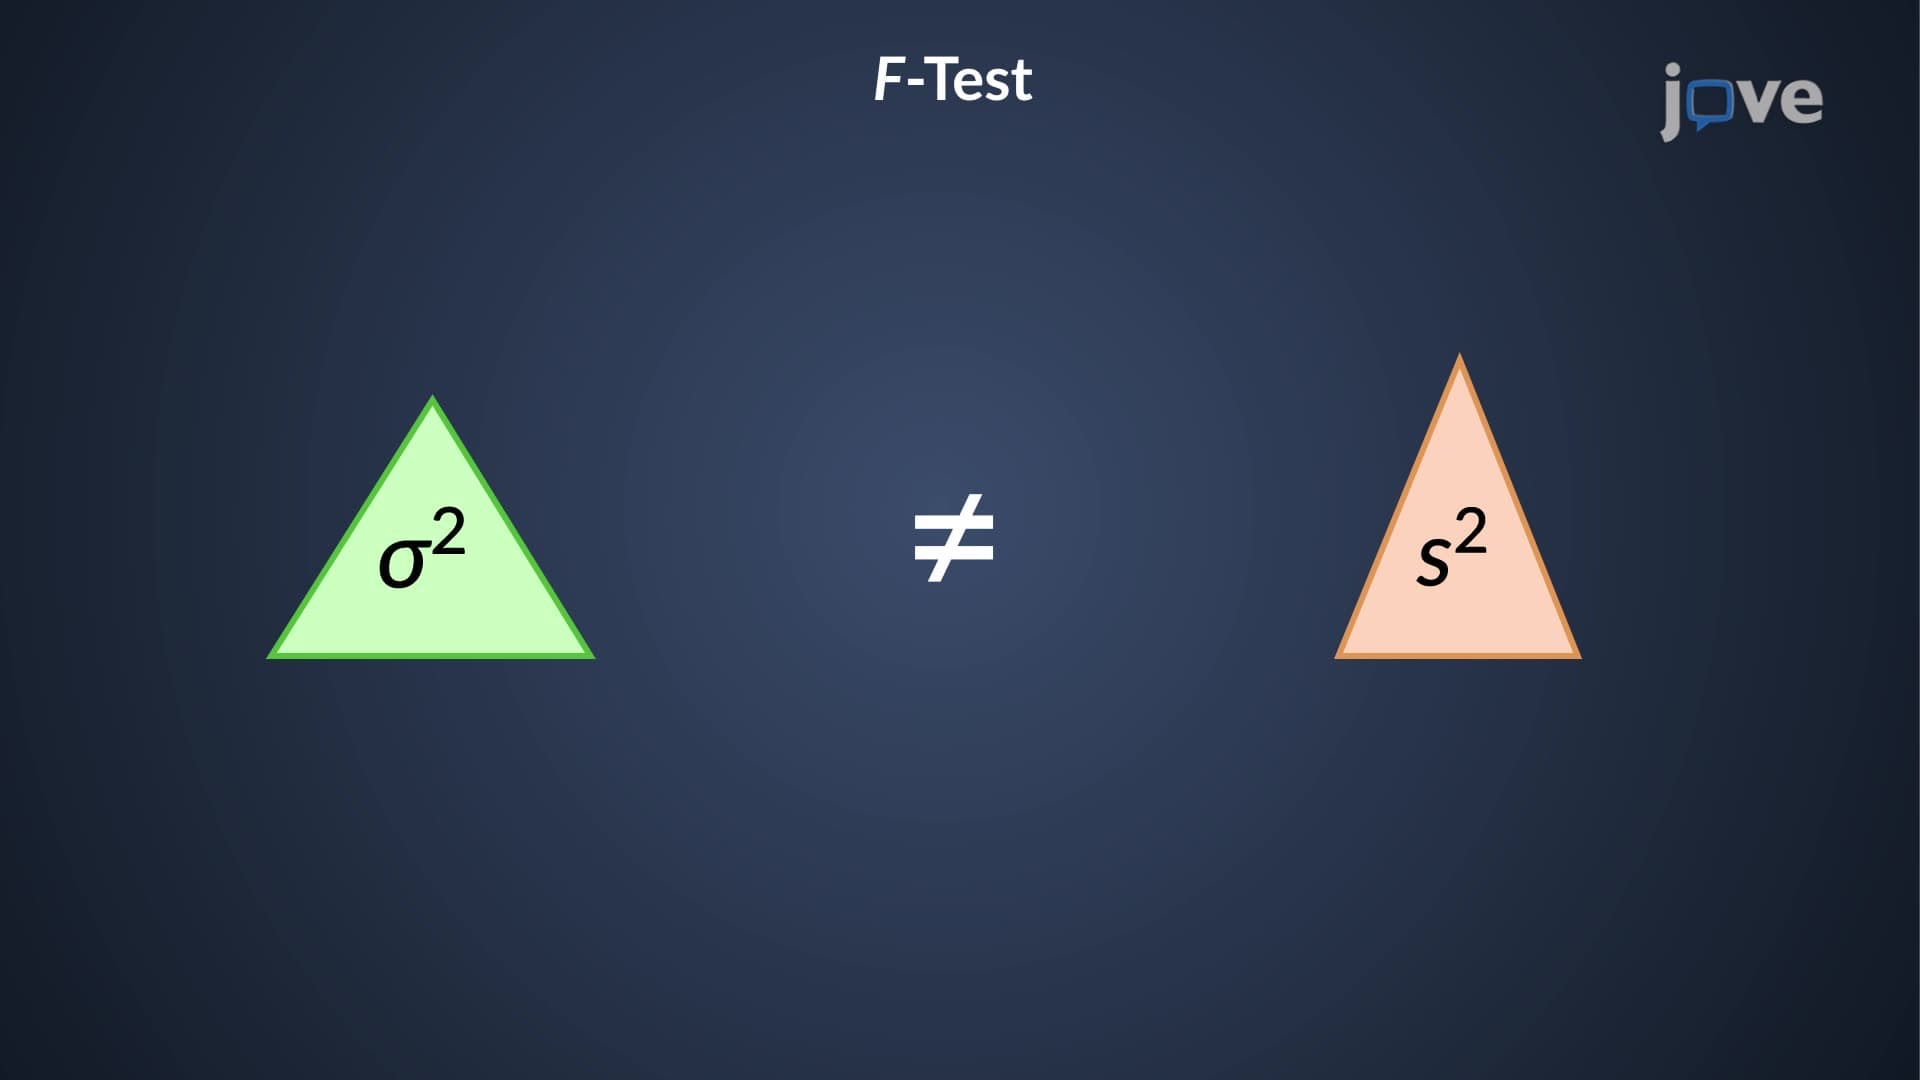
Identifying Statistically Significant Differences: The F-Test
The F-test is used to compare two sample variances to each other or compare the sample variance to the population variance. It is used to decide whether an indeterminate error can explain the difference in their values. The underlying assumptions that allow the use of the F-test include the data set or sets are normally distributed, and the data sets are independent of each other. The test statistic F is calculated by dividing one variance by another. In other words, the square of one standard...