
制限酵素のファミリー間の複雑なDNA認識ドメインの保存
G M Cowan1, A A Gann, N E Murray
1Department of Molecular Biology, University of Edinburgh, Scotland.
Cell
|January 13, 1989

まとめ
Sポリペプチドは,S型ポリペプチドである.
科学分野:
- 分子生物学は分子生物学である.
- 酵素学 酵素学とは
- 遺伝学 遺伝学とは
背景:
- マルチサブユニット型I制限酵素は,シーケンス固有のDNA認識のためにSポリペプチドを使用します.
- 2つの酵素ファミリー,KとAは,多様な二重のDNA標的を認識します.
- K族のS型ポリペプチドは,標的の認識に不可欠な変数配列領域を示す.
研究 の 目的:
- DNA配列認識におけるSポリペプチドのN末端ドメインの役割を明らかにする.
- I型制限酵素EcoEによって認識される特定のDNA配列を決定する.
- 異なる酵素ファミリーにわたるS遺伝子のアミノ酸とヌクレオチド配列を比較する.
主な方法:
- EcoAとEcoEからのS遺伝子の配列分析.
- 予測されたアミノ酸配列の比較とKファミリーメンバーの比較.
- エコエのターゲットDNA配列の決定.
主要な成果:
- KファミリーSポリペプチドのN端150アミノ酸は,1つの二重のターゲットコンポーネントの認識を指定します.
- EcoEはDNA配列5'GAG(N7) ATGC.を認識しています.
- GAGを認識する保存ドメインは,全体的な配列の不一致にもかかわらず,KファミリーとAファミリーの両方のSポリペプチドに存在します.
- StySB (K族) のGAG特異ドメインと,EcoAとEcoE (A族) Sポリペプチドの変数アミノ領域の間に,有意な配列同一性 (約50%) が発見されました.
結論:
- 異なるファミリーのタイプI制限酵素に共通するGAG認識およびメチル化ドメインが存在する.
- 全体的な配列の相違にもかかわらず,DNA認識ドメインの機能的保存は明らかです.
- この研究は,シーケンス特異性を与えるSポリペプチドのモジュラー性を強調しています.
関連する概念動画
 02:26
Conservation of Protein Domains Over Different Proteins
Protein domains are small structurally independent units that are part of a single amino acid chain. Although these domains are often structurally independent, they may rely on synergistic effects to perform their functions as part of a larger protein. Protein domains may be conserved within the same organism, as well as across different organisms.
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
 01:49
Conserved Binding Sites
Many proteins’ biological role depends on their interactions with their ligands, small molecules that bind to specific locations on the protein known as ligand-binding sites. Ligand-binding sites are often conserved among homologous proteins as these sites are critical for protein function.
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 02:53
Conservative Site-specific Recombination and Phase Variation
Because the DNA segments are cut and reorganized in a direction-specific manner, site-specific recombination has emerged as an efficient genetic engineering technique. Flippase and Cyclization recombinases or Flp and Cre, respectively, are two members of the tyrosine recombinase family derived from bacteriophages, that are used to mediate site-specific DNA insertions, deletions, and targeted expression of proteins in mammalian cell lines.
The recognition sites for Cre recombinase called LoxP...
The recognition sites for Cre recombinase called LoxP...
 02:51
Multi-species Conserved Sequences
Next-generation sequencing technologies have created large genomic databases of a variety of animals and plants. Ever since the human genome project was completed, scientists studied the genome of primates, mammals, and other phylogenetically distant living beings. Such large-scale studies have provided new insights into the evolutionary relationship between organisms.
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved DNA...
 01:11
Restriction Enzymes
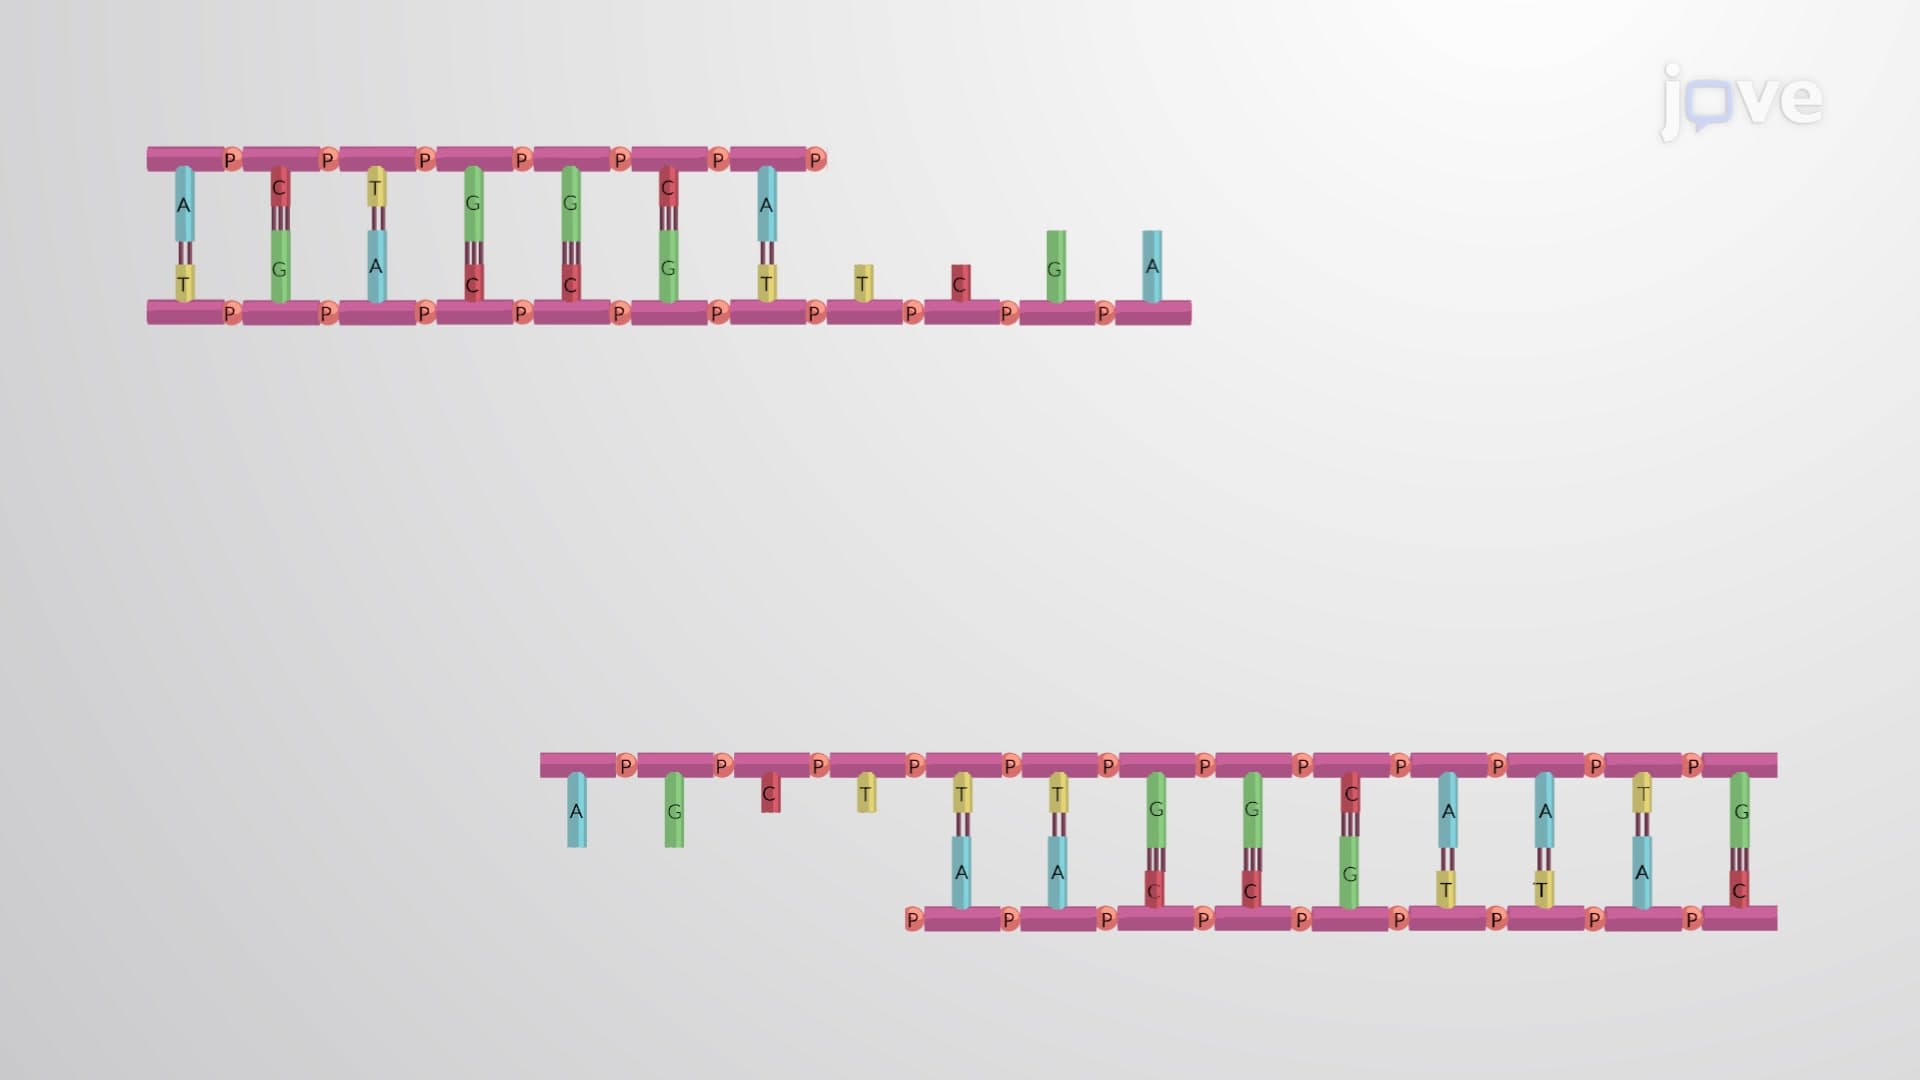
Restriction enzymes are bacterial enzymes used to cut DNA in a sequence-specific manner. To cleave DNA, they bind to specific palindromic sequences called restriction sites. Such palindromic DNA sequences or inverted repeats are commonly found in regions of functional significance, such as the origin of replication, gene operator sites, and regions containing transcription termination signals.
The host bacteria protect their own genomic DNA from these enzymes by methylating these sites. Some...
The host bacteria protect their own genomic DNA from these enzymes by methylating these sites. Some...
02:26Conservation of Protein Domains
Protein domains are small structurally independent units that are part of a single amino acid chain. Although these domains are often structurally independent, they may rely on synergistic effects to perform their functions as part of a larger protein. Protein domains may be conserved within the same organism, as well as across different organisms.
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...
A limited set of protein domains often duplicate and recombine during evolution. These domains can be organized in different combinations to form...