
人工ニューラルネットワークと多重線形回帰を比較して,米のカドミウム濃度を予測する:中国の広西でのフィールド研究
Junyang Zhao1, Fuhai Zheng2, Baoshan Yu1
1Guangxi Key Laboratory of Agro-Environment and Agric-Products Safety, College of Agriculture, Guangxi University, Nanning 530004, China.
Toxics
|August 27, 2025

まとめ
米中のカドミウム (Cd) を予測する2つのモデルを開発しました バックプロパガンダ人工ニューラルネットワーク (BP-ANN) モデルは,米のカドミウム含有量を予測する多重線形回帰 (MLR) モデルよりも優れた性能を示した.
科学分野:
- 環境科学
- 農業科学
- 土壌科学
背景:
- 土壌と米のシステムにおけるカドミウム (Cd) の転移は複雑で,現在の土壌と植物のモデルの有効性を制限しています.
- 米のCd含有量の正確な予測は,食品安全とリスク評価に不可欠です.
研究 の 目的:
- 米粒のカドミウム含有量を推定するために,逆伝播人工ニューラルネットワーク (BP-ANN) モデルと多重線形回帰 (MLR) モデルの予測性能を比較する.
- 米のカドミウム蓄積に影響を与える土壌の主要パラメータを特定する.
主な方法:
- 訓練と検証のために486個のペアされた土壌と米粒のサンプルを使用し,さらに30個のサンプルを広西省からテストするために使用しました.
- 土壌利用可能なカドミウム (ACd),土壌全体のカドミウム (TCd),土壌の有機物質 (SOM) およびpHを予測変数として使用した.
- ルート・ミーン・スクエア・エラー (RMSE),相対パーセント差 (RPD),および相関係数 (R2) を用いてモデルのパフォーマンスを評価した.
主要な成果:
- pH,TCd,ACdを使用したMLRモデルは,米カドミウム (RCd) のR2,RPD>2.398,RMSE>0.049を達成した.
- BP-ANNモデルは,同じ変数を用いて,RCdのR2とRMSEの0.104を得ました.
- BP-ANNモデルは,MLRモデルと比較して優れた予測精度を示した.
結論:
- バックプロパガンダ人工ニューラルネットワーク (BP-ANN) モデルは,米のカドミウム含有量を予測するのに有効です.
- BP-ANNは,土壌-米系におけるカドミウム予測のための従来の多重線形回帰 (MLR) よりも優れた性能を提供します.

関連する概念動画
 01:25
Multiple Regression
3.2K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.2K
 01:11
Regression Analysis
6.0K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
6.0K
 00:53
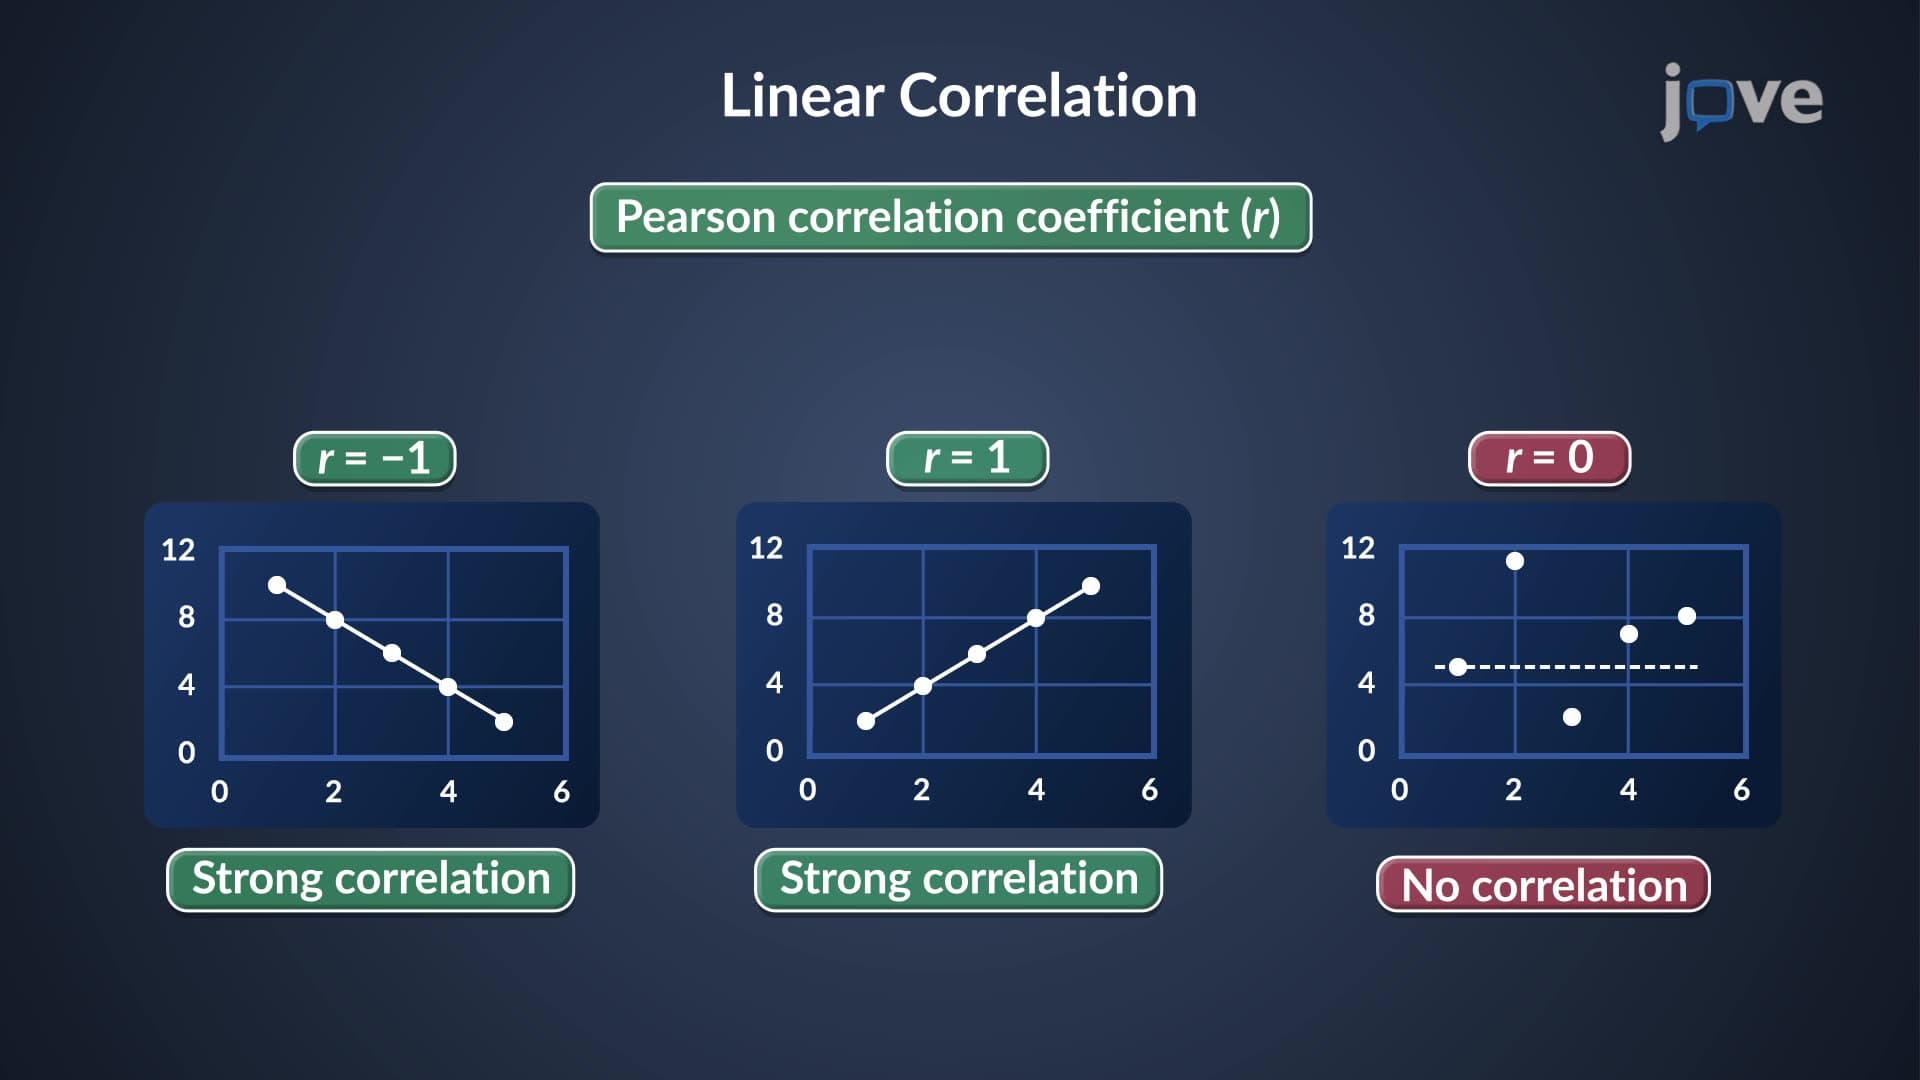
Correlation and Regression
1.8K
In statistics, correlation describes the degree of association between two variables. In the subfield of linear regression, correlation is mathematically expressed by the correlation coefficient, which describes the strength and direction of the relationship between two variables. The coefficient is symbolically represented by 'r' and ranges from -1 to +1. A positive value indicates a positive correlation where the two variables move in the same direction. A negative value suggests a...
1.8K
 01:11
Calculating and Interpreting the Linear Correlation Coefficient
6.4K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable, x, and the dependent variable, y. Hence, it is also known as the Pearson product-moment correlation coefficient. It can be calculated using the following equation:
6.4K