
ファクターベースの資産配分向け深層強化学習:静的および動的ベータ報酬設計の比較分析
1Seoul AI School, aSSIST University, Seoul, Republic of Korea.

Abstract:
Traditional asset allocation rules, while effective in stable phases, tend to erode once markets enter volatile regimes or undergo structural breaks. Research in deep reinforcement learning (DRL) has usually emphasized raw-return rewards, leaving aside the role of factor exposures ([Formula: see text]) that shape both risk-adjusted payoffs and adaptive responses. This paper advances a Factor-based Deep Reinforcement Learning for Asset Allocation (FDRL) framework in which [Formula: see text] sensitivities-estimated via rolling regressions on momentum, volatility, deviation, and volume signals-inform both the state representation and the reward design. Five reward variants are examined (Sharpe, Sortino, Static-[Formula: see text], Dynamic-[Formula: see text], Momentum-[Formula: see text]) using PPO, SAC, and TD3 across equities, cryptocurrencies, macroeconomic instruments, and mixed portfolios. Empirically, [Formula: see text]-based rewards generate heterogeneous but interpretable patterns. In equities, Dynamic-[Formula: see text] improves annualized returns from roughly 20% (Sharpe baseline) to 23-24%, with Sharpe rising from 1.04 to about 1.27 across windows. In cryptocurrencies, Dynamic-/Momentum-[Formula: see text] achieve 38-43% annual returns but remain highly regime-sensitive, with drawdowns often exceeding -35%. In macro instruments, Static-[Formula: see text] delivers the most stable behaviour, maintaining volatilities near 8-9% and limiting drawdowns to roughly -18%. In mixed-asset portfolios, Momentum-[Formula: see text] under TD3 produces the strongest gains (cumulative returns above 70-80%), exceeding equal-weight baselines whose CAGR remains near 19-22% with Sharpe ratios around 1.25. All findings were validated through beta-window sensitivity checks (30/60/90/120 days), regime-conditional analysis, and multiple robustness tests including HAC, Wilcoxon, jackknife Sharpe, moving-block bootstrap, and false-discovery-rate adjustments. These diagnostics confirm that the main performance patterns are not driven by window choice or serial dependence. Four contributions follow. First, a reward structure operationalizing time-varying [Formula: see text]. Second, systematic benchmarking of factor-sensitive objectives. Third, evidence on asymmetric outcomes across asset classes. Finally, a framework that reconciles responsiveness with interpretability and risk discipline in allocation.
さらに関連する動画
 07:05
Operant Protocols for Assessing the Cost-benefit Analysis During Reinforced Decision Making by Rodents
Published on: September 10, 2018
 08:24
The Joint Effect of Social Comparison and Social Distance on Evaluation of Intertemporal Choice Outcomes in Event-related Potential Studies
Published on: August 25, 2023
関連する概念動画
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:26
Equity Theory
 01:09
Decision Making: P-value Method
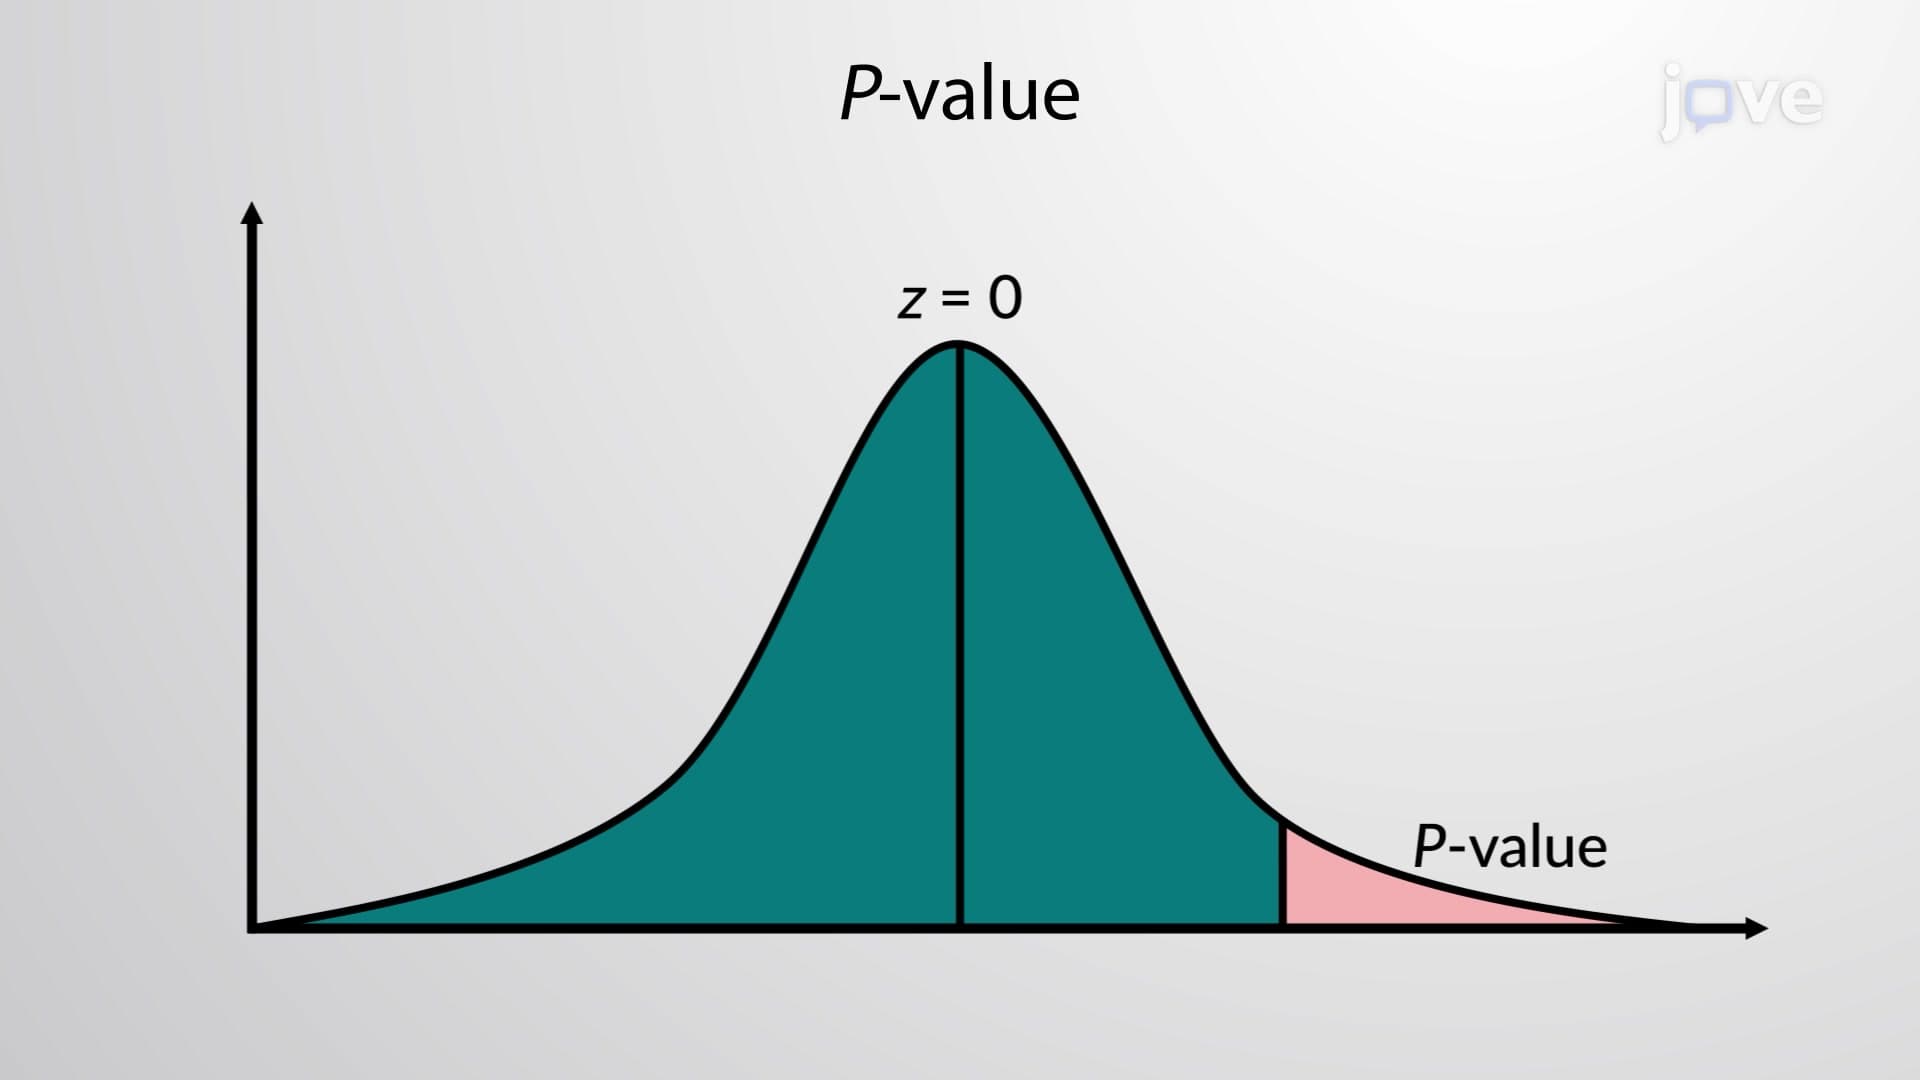
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 02:20
Dynamic Equilibrium
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:20
Actuarial Approach
Consider the example of a high-risk surgical procedure with significant early-stage mortality. A two-year clinical study is conducted,...