関連する実験動画
Updated: Feb 21, 2026
08:12
A Psychophysics Paradigm for the Collection and Analysis of Similarity Judgments
Published on: March 1, 2022
3.0K
ReMoDe - 順序データ分布における再帰的モダリティ検出
Madlen Hoffstadt1, Lourens Waldorp1, Javier Garcia-Bernardo2
1Department of Psychology, University of Amsterdam, Amsterdam, The Netherlands.
The British journal of mathematical and statistical psychology
|February 19, 2026

まとめ
ReMoDeは,オーダーナルデータのための新しいリキュルティブモダリティ検出方法である. ReMoDeは,ディストリビューションのモードを正確に識別し,シミュレーションにおける既存の方法を上回ります.
科学分野:
- 統計局 統計局 統計局 統計局 統計局
- データ分析 データ分析
背景:
- オーダーナルデータのモードを検出することは,心理学や医学のような学問に不可欠です.
- モダリティ検出の既存の方法は,しばしば記述的であり,並列データには適さない.
研究 の 目的:
- 単変数順位分布のための新しい再帰的モダリティ検出方法 (ReMoDe) を提案する.
- オーダーナルスケールに適用される現在の方法の限界に対処するために.
主な方法:
- モード検出のための再帰的意味性テストアプローチを開発した.
- 異なるサイズの172のシミュレートされた順序データセットを使用してベンチマーク研究を実施しました.
- 検出されたモードの安定性試験と計算されたp値とベイズ因子.
主要な成果:
- ReMoDeは,シミュレーションで確立されたモダリティ検出方法と比較して優れたパフォーマンスを示しました.
- この方法は,検出されたモードの統計的測定値 (p値,ベイズ因数) を提供します.
- オープンソースのRとPythonパッケージは,簡単に実装できるように提供されています.
結論:
- ReMoDeは,オーダーナルデータにおけるモダリティ検出のための堅牢で正確なソリューションを提供します.
- この方法は,分布の分析を強化し,研究者が極化や発生群などのパターンを特定するのを助けます.
関連する概念動画
 00:55
Ordinal Level of Measurement
35.0K
The way a set of data is measured is called its level of measurement. Correct statistical procedures depend on a researcher being familiar with levels of measurement. For analysis, data are classified into four levels of measurement—nominal, ordinal, interval, and ratio.
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
Data measured using an ordinal scale are similar to nominal scale data, but there is one major difference. The ordinal scale data can be ordered. An example of ordinal scale data is a list of the top five national parks...
35.0K
 01:07
What is a Mode?
27.3K
The mode is one of the commonly used measures of a central tendency. It is defined as the most frequent value in a data set.
There can be more than one mode in a data set if multiple values have the same highest frequency. For instance, suppose that the Statistics exam scores of 20 students are: 50; 53; 59; 59; 63; 63; 72; 72; 72; 72; 72; 76; 78; 81; 83; 84; 84; 84; 90; 93. Here, the mode is 72, as it occurs most frequently, five times.
A data set with two modes is called bimodal. For example,...
27.3K
 01:02
Ranks
523
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
523
 00:56
Nominal Level of Measurement
40.1K
The way a set of data is measured is called its level of measurement. Correct statistical procedures depend on a researcher being familiar with levels of measurement. Not every statistical operation can be used with every set of data. For analysis, data are classified into four levels of measurement—nominal, ordinal, interval, and ratio.
The data that cannot be measured but can be grouped into categories fall under the nominal level of measurement. Data that is measured using a nominal...
The data that cannot be measured but can be grouped into categories fall under the nominal level of measurement. Data that is measured using a nominal...
40.1K
 01:11
How Data are Classified: Categorical Data
45.9K
A variable, usually notated by capital letters such as X and Y, is a characteristic or measurement that can be determined for each member of a population. Data are the actual values of variables. They may be numbers, or they may be words. Datum is a single value.
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
45.9K
 00:55
Relative Frequency Distribution
13.9K
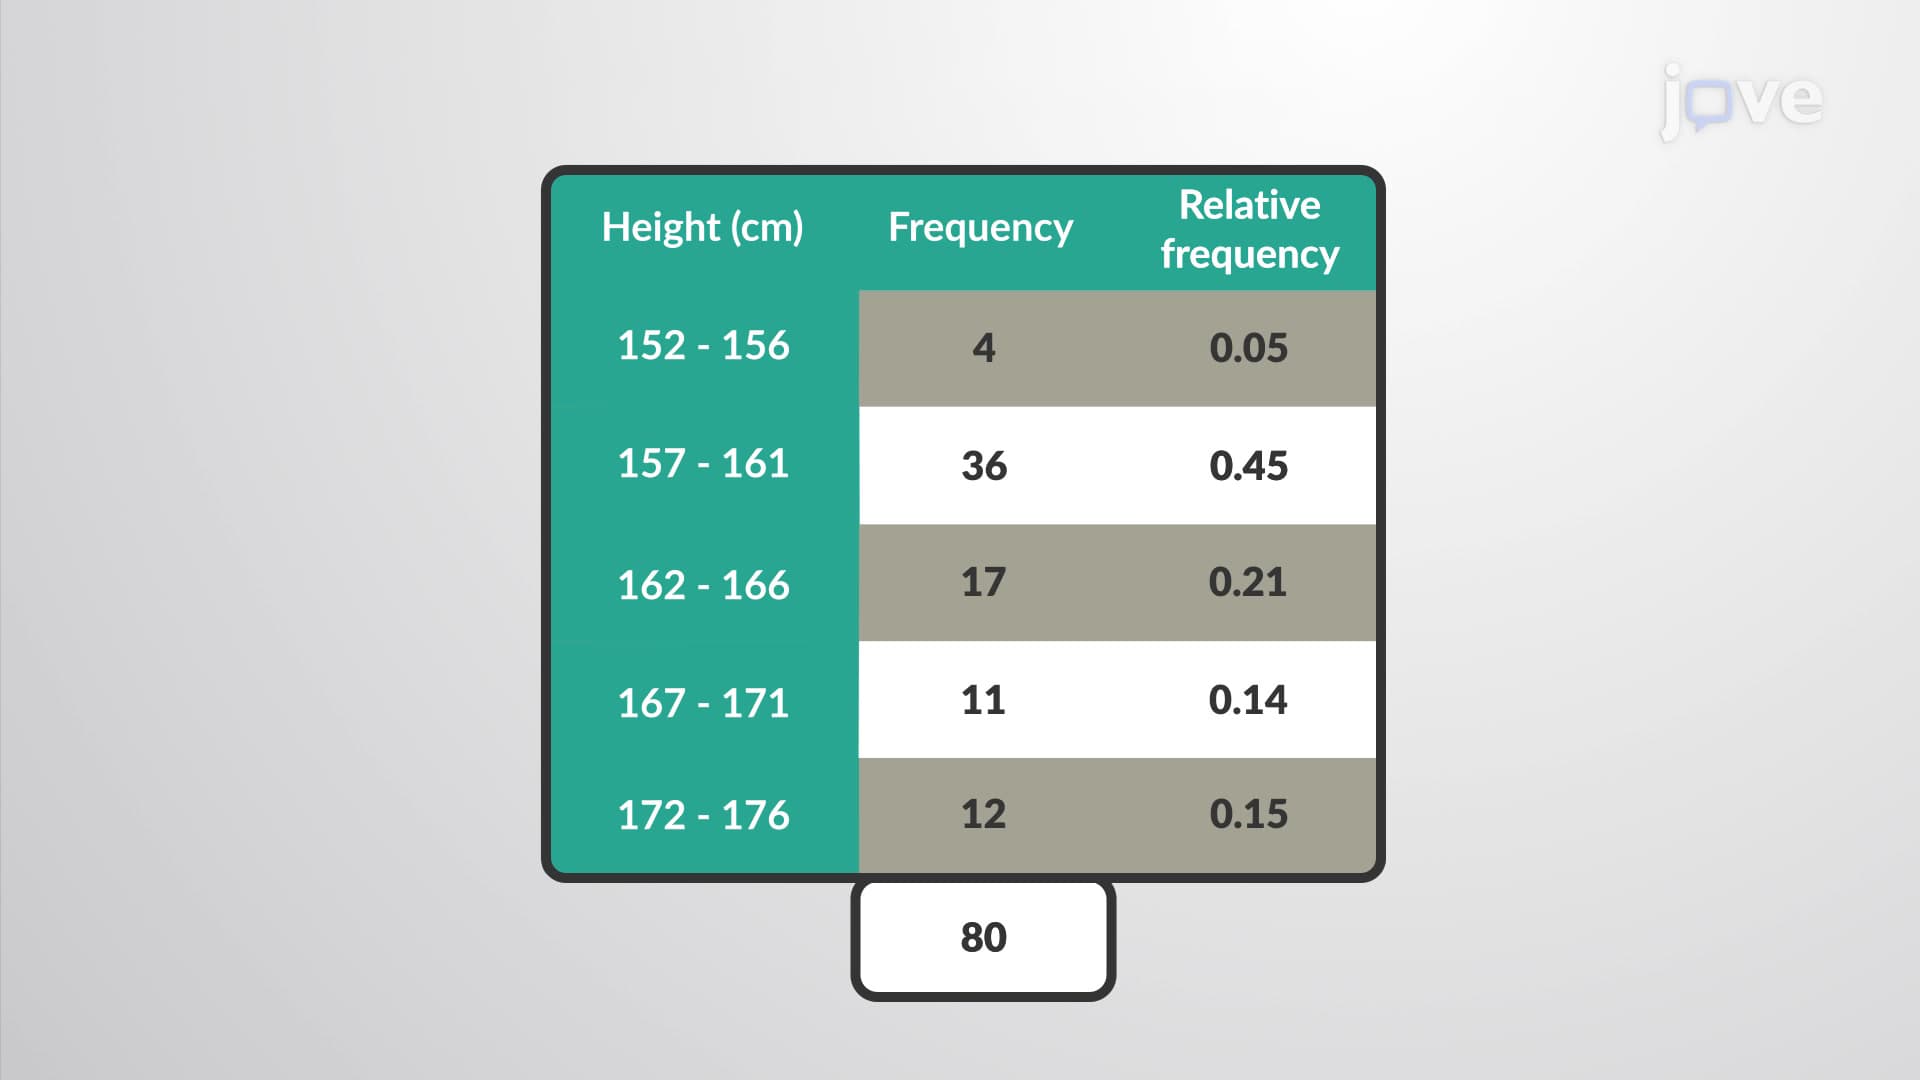
A relative frequency distribution is the proportion or fraction of times a value occurs in a data set. To find the relative frequencies, one can divide each frequency by the total number of data points in the sample. It is very similar to a regular frequency distribution, except that instead of reporting how many data values fall in a class, a relative frequency distribution reports the fraction of data values that fall in a class. These fractions or proportions are called relative frequencies...
13.9K